Biodiversity Heritage Library - Program news and collection highlights from BHL
  • Home
  • News
  • Featured Books
    • All Featured Books
    • Book of the Month Series
    • BHL at 20
  • User Stories
  • Campaigns
    • Fossil Stories
    • Garden Stories
    • Monsters Are Real
    • Page Frights
    • Her Natural History
    • Earth Optimism 2020
  • Tech Blog
  • Visit BHL
Home
News
Featured Books
    All Featured Books
    Book of the Month Series
    BHL at 20
User Stories
Campaigns
    Fossil Stories
    Garden Stories
    Monsters Are Real
    Page Frights
    Her Natural History
    Earth Optimism 2020
Tech Blog
Visit BHL
  • Home
  • News
  • Featured Books
    • All Featured Books
    • Book of the Month Series
    • BHL at 20
  • User Stories
  • Campaigns
    • Fossil Stories
    • Garden Stories
    • Monsters Are Real
    • Page Frights
    • Her Natural History
    • Earth Optimism 2020
  • Tech Blog
  • Visit BHL
Biodiversity Heritage Library - Program news and collection highlights from BHL
BHL News, Blog Reel, Tech Updates

What Is BHL’s New Persistent Identifier Working Group DOI’ng?

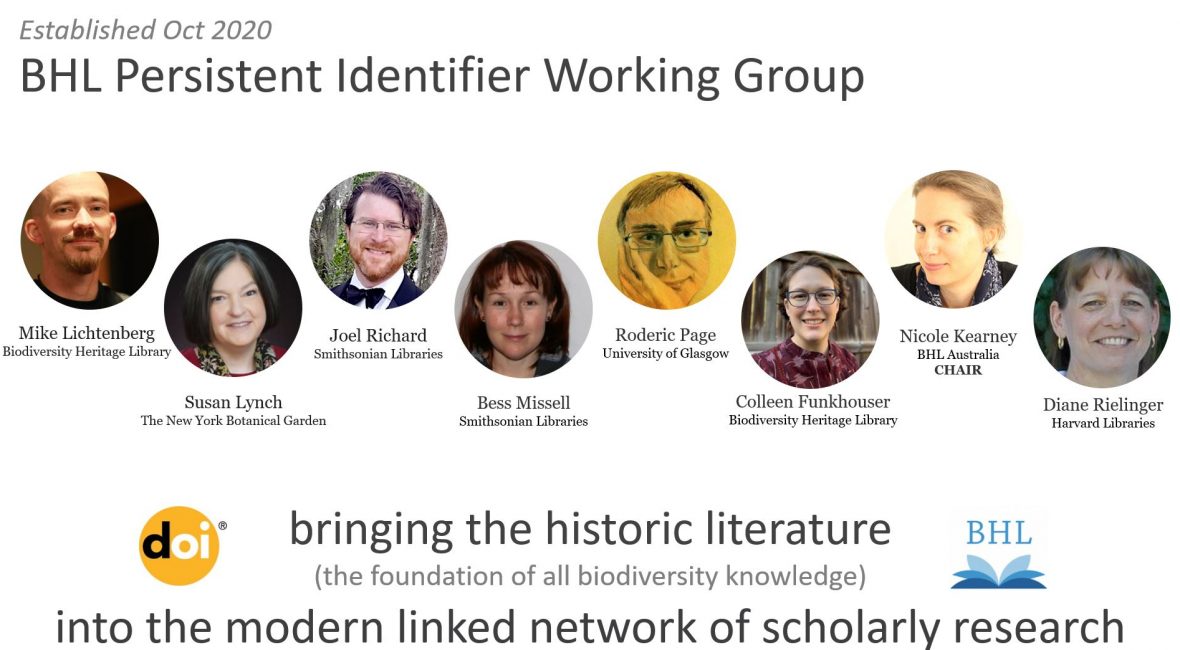
Graphic showing the members of BHL's Persistent Identifier Working Group

In October 2020, BHL launched a new working group with a momentous goal: to make the content on BHL persistently discoverable, citable and trackable using DOIs (Digital Object Identifiers).
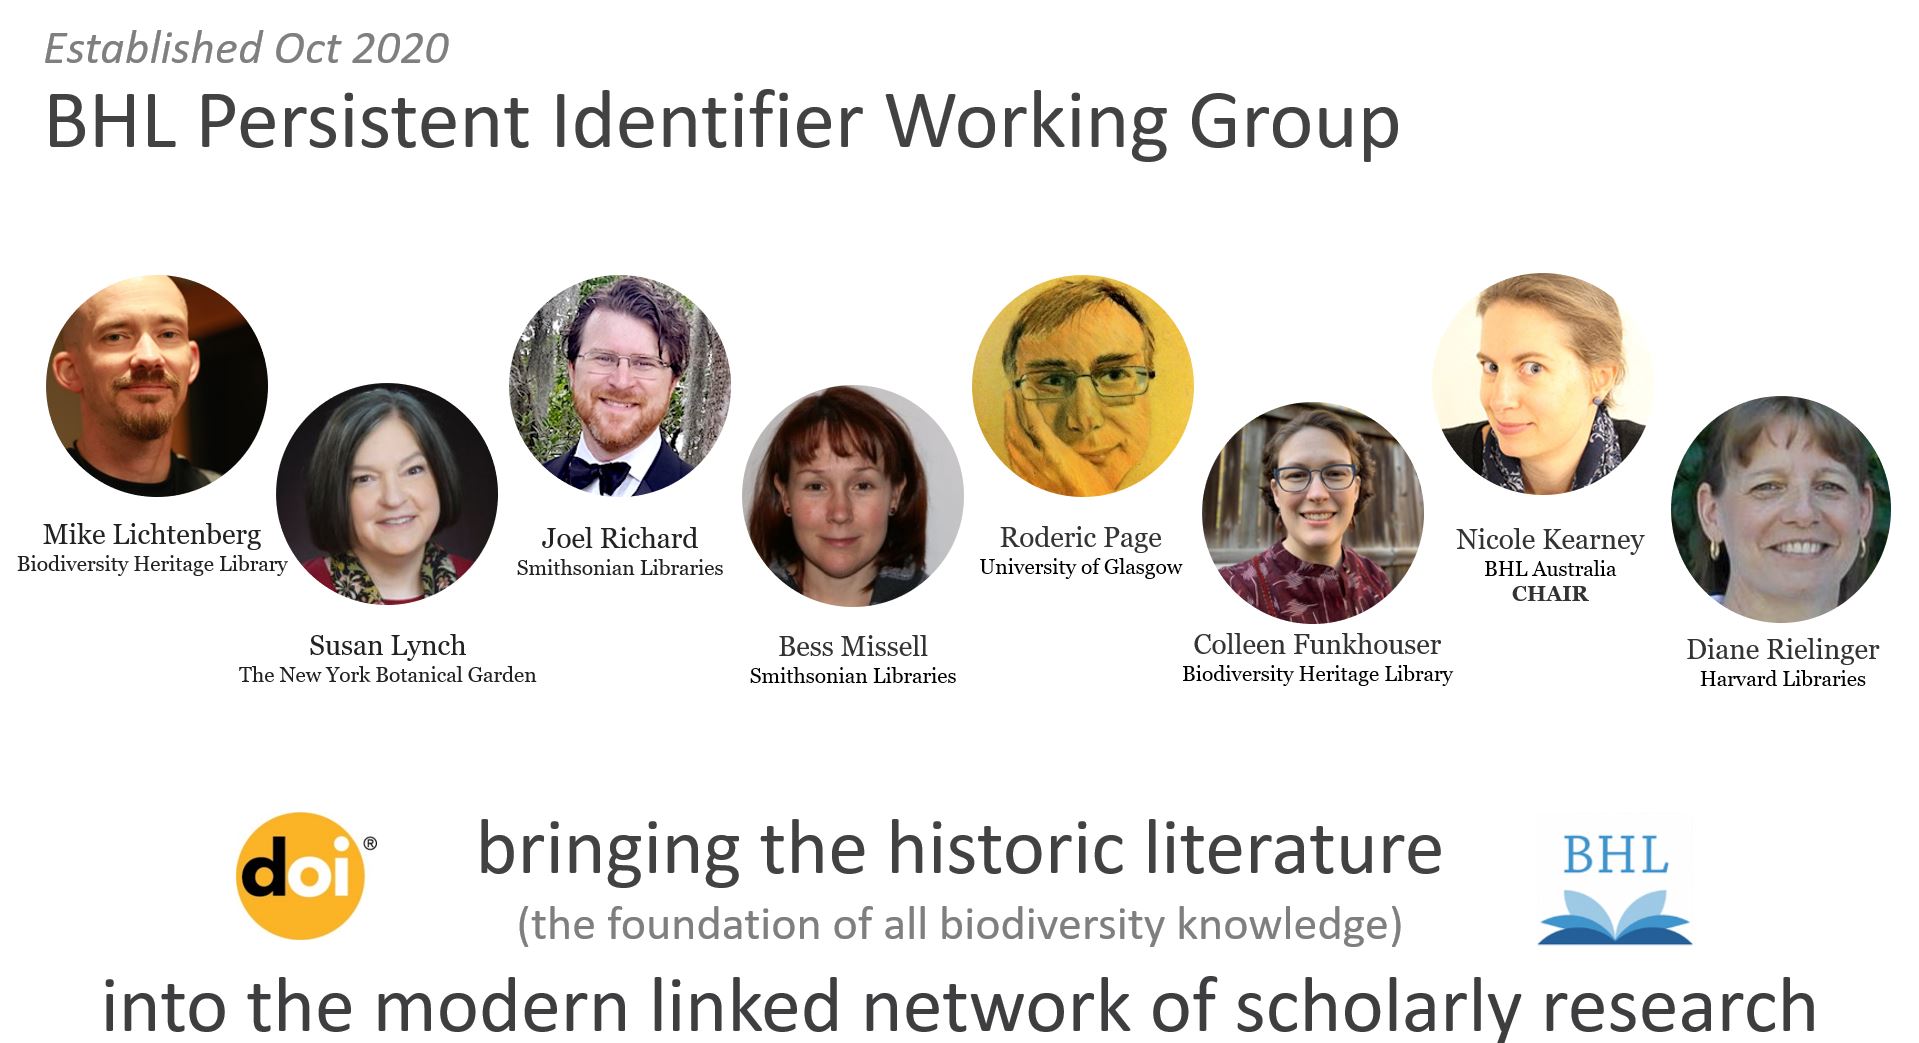
Graphic showing the members of BHL's Persistent Identifier Working Group

The members of BHL’s new Persistent Identifier Working Group (PIWG).

A DOI is like an electronic fingerprint in the form of a unique and permanent alphanumeric string that provides a persistent link to a piece of content online. Modern publications receive a DOI at the point of publication. This DOI becomes a key part of a publication’s bibliographic metadata that should be included in any mention or citation of that publication. Reference lists in modern publications are filled with DOIs, which allows readers to click from publication to publication in (in theory) a never-ending chain of knowledge.

This reciprocal linking of DOIs has created a great linked network of scholarly research, but that network is missing the historic literature. The vast majority of historic publications lack DOIs. This means they appear in reference lists as unlinked citations. In our increasingly online world, readers are far more likely to read (and thus cite) publications they can click through to (particularly when libraries are inaccessible during a global pandemic). The upshot of this is that the millions of pages of historic literature on BHL—the foundation of our understanding of biodiversity—is in danger of falling into obscurity.

BHL has been retrospectively minting DOIs for historic publications since 2011, but the focus has primarily been on monographs. BHL’s new Persistent Identifier Working Group (PIWG) is (at least initially) focusing on journal articles. Minting DOIs for articles on BHL is a far more complex and time-consuming task than minting DOIs for monographs. This is because article DOIs need article data: every journal volume uploaded onto BHL must be accompanied by journal and volume data, but there is no requirement that contributors provide article data.

Thankfully, there have been considerable efforts to add article data to BHL (and thereby make it possible to search for the titles and authors of these articles both within BHL and via external engines). A huge proportion of this article data has been contributed to BHL by Roderic Page via BioStor: 75% of the 300,753 articles indexed in BHL as of 4 May 2021 were “defined” by BioStor. It is very difficult to determine how many articles are actually on BHL (hidden within all those journal volumes). But, while we don’t know what proportion of BHL’s journal content still needs to be made discoverable, we know there is still a huge amount of work to do.

COVID-19 provided an unexpected opportunity to make a considerable dent in this work. With no access to scanners or library materials, a number of BHL contributors, including Harvard University Libraries, Muséum National d’Histoire Naturelle and BHL Australia, pivoted from making new content accessible to making their existing content on BHL more discoverable. For example, BHL Australia’s digitisation volunteers gathered, gap filled and checked article-level metadata for over 30,000 articles in 2020.

Once an article has been defined, i.e. it exists as a publication unit in BHL and has its own article landing page (and we’ve checked that the article does not already have a DOI), we can assign a DOI to it. Articles that have recently been assigned BHL DOIs include some very old publications, such as the first scientific description of the Duck-billed Platypus, published in 1799 (https://doi.org/10.5962/p.304567), and the species descriptions from A specimen of the botany of New Holland, the first publication dedicated to Australian flora (1793-5), e.g. https://doi.org/10.5962/p.312432. The PIWG has also started assigning DOIs to in-copyright publications (with permission from the rights holders). These include articles from the Bulletin of the British Museum, e.g. https://doi.org/10.5962/p.310418, and the Bulletin of the African Bird Club, e.g. https://doi.org/10.5962/p.308885.
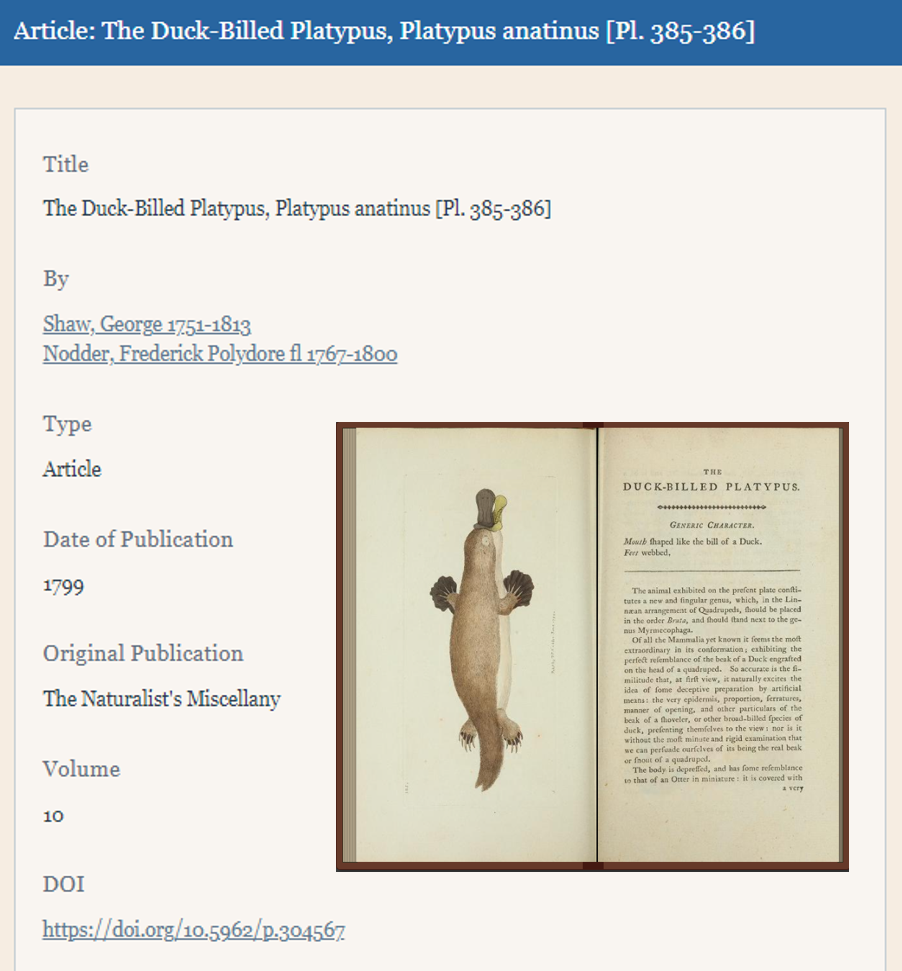
Screenshot of the landing page in BHL for the description of the The Duck-Billed Platypus, Platypus anatinus.

Shaw, George (1799), The Duck-Billed Platypus, Platypus anatinus, The Naturalist’s Miscellany: https://doi.org/10.5962/p.304567 (illustration by Frederick Polydore Nodder).

If an article on BHL has an existing non-BHL DOI, we add this key piece of bibliographic metadata to the BHL landing page for the article. This ensures that BHL users can link to the definitive version of the article (the one the DOI resolves to), and more importantly, that other parties (and their algorithms) can find our versions from elsewhere. This is particularly important when commercial websites lock their DOI’d versions of public domain articles behind paywalls. Having their DOIs on our freely accessible versions ensures that services like Unpaywall can find them. To learn more about how this works, see our blog post: BHL Journal Articles Are Now Discoverable via Unpaywall.

DOIs not only improve discoverability and enable persistent linking to our historic content; they also allow us to track how BHL content is being used. In the six months following the minting of its new DOI (Oct 2020 to April 2021), the 1799 Platypus description was tweeted by 219 Twitter accounts, referenced in six Wikipedia pages, picked up by one news outlet and cited in one academic paper (data from Altmetric, April 2021). We know this because the article has a DOI.
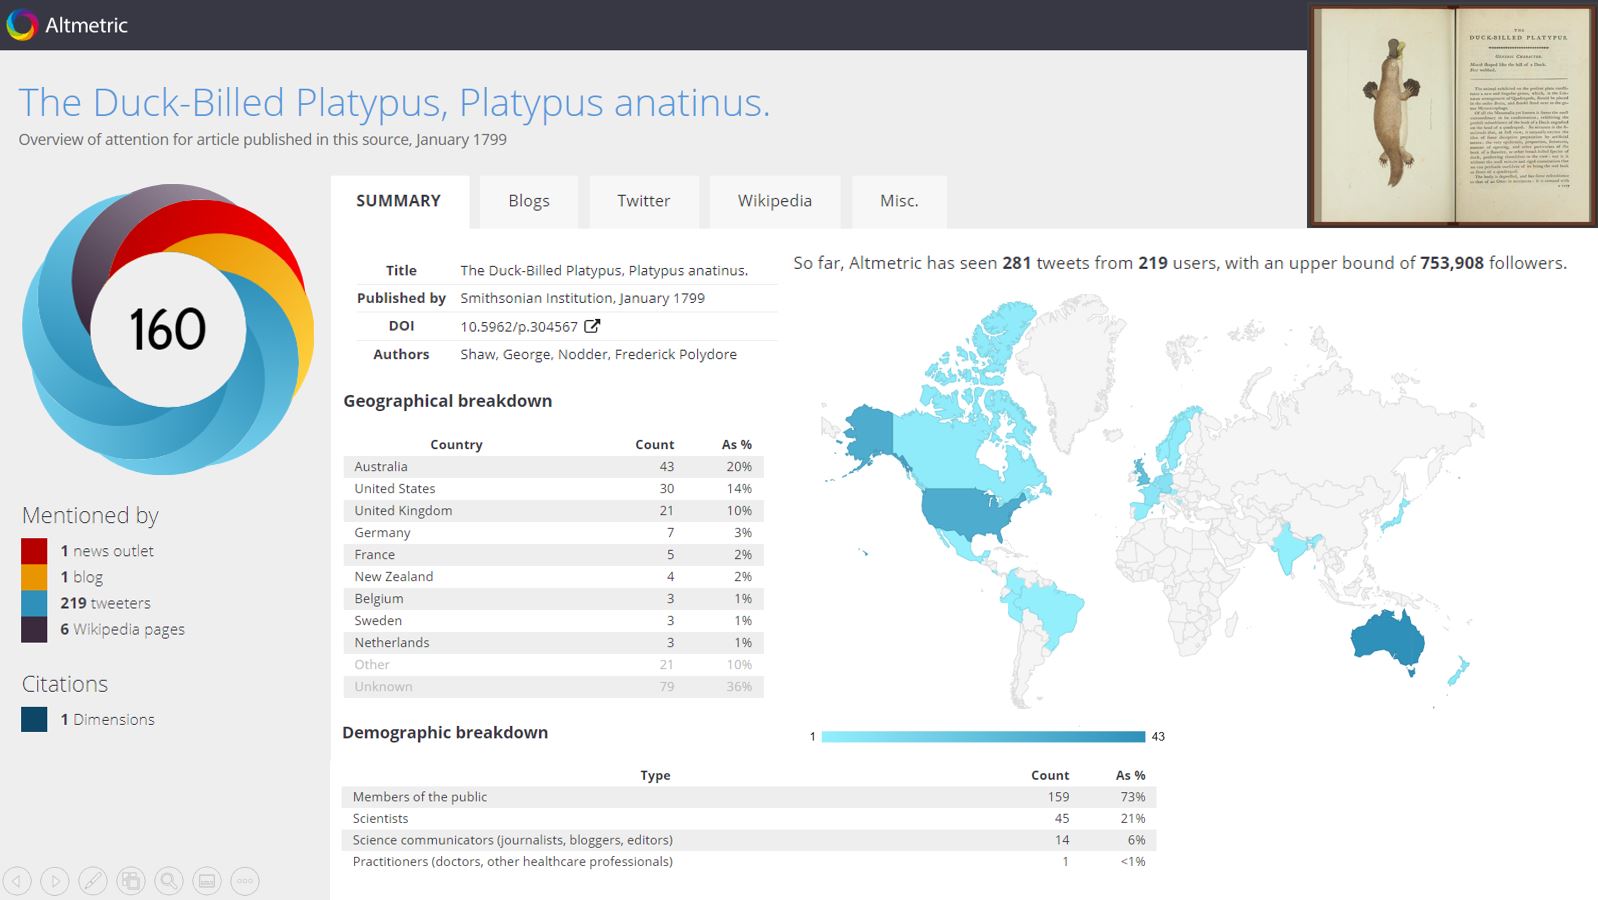
Screenshot of the Altmetric dashboard for the first scientific description of the Duck-billed Platypus

Altmetric’s overview of attention for the first scientific description of the Duck-billed Platypus (Shaw 1799): https://www.altmetric.com/details/91788579.

The PIWG has spent the past six months creating, refining and testing tools that will allow BHL contributors to do this work themselves. We have also been producing documentation that explains a) how to use the new tools, and b) why this work is so important. These tools will facilitate every step in the article discoverability and DOI assignment process including: downloading existing article data for a given journal title to allow for correction and gap-filling (in development); bulk uploading of article data for new articles (available now); and adding articles and titles to BHL’s (new) DOI Assignment Queue (available now). Our dream is that, whenever anyone uploads a journal volume to BHL, they also provide the data for the articles it contains (and thus take responsibility for making that content discoverable).

The Persistent Identifier Working Group (PIWG) is fueled by the technical expertise, metadata dexterity and incredible passion of:

  • Nicole Kearney, Manager BHL Australia (Chair)
  • Mike Lichtenberg, BHL Lead Developer
  • Susan Lynch, Systems, Digitization & Web Services Librarian, The New York Botanical Garden
  • Bess Missell, Metadata Librarian, Smithsonian Libraries and Archives
  • Roderic Page, Professor of Taxonomy, University of Glasgow
  • Joel Richard, BHL Technical Coordinator | Head of Web Services & IT, Smithsonian Libraries, Smithsonian Libraries and Archives
  • Diane Rielinger, Digital Projects Librarian, Botany Libraries, Harvard University Herbaria
  • Colleen Funkhouser, BHL Program Manager

The specific goals of the group are:

  • To add article-level metadata to journal articles on BHL
  • To add existing DOIs to (new and existing) article landing pages on BHL (particularly for those articles where the DOI’d version is behind a paywall elsewhere)
  • To assign BHL DOIs to articles that lack DOIs

Want to know more about BHL’s Persistent Identifier Working Group? See:

  • Discovering the Platypus: From its scientific description to its DOI, Biodiversity Information Science and Standards (TDWG) Conference, 6 October 2020: https://youtu.be/4UVSEoWsSrw?t=1285
  • #RetroPIDs: making historic Platypus Infinitely Discoverable (PID), PIDapalooza: the Festival of Persistent Identifiers, 28 January 2021: https://youtu.be/CSeQNe5KR5U

For the latest news about BHL’s DOI work, check out #RetroPIDs on Twitter.
May 10, 2021by michelle.underhill
BHL News, Blog Reel, Tech Updates

BHL Improves the Speed and Accuracy of its Taxonomic Name Finding Services with gnfinder

New and improved BHL name finding services

BHL has deployed a new taxonomic name finding tool to improve the speed and accuracy of identifying names throughout its 58+ million pages.

BHL is now using Global Names Architecture’s (GNA) gnfinder tool to locate taxonomic names in the BHL corpus. Prior to this deployment, BHL’s name finding services were based on an index of scientific names created by GNA developers six years ago by parsing every page in BHL one by one. This took 45 days to accomplish, and the cost of repeating this process made updating or improving the index infeasible.

The gnfinder tool uses fast, scalable programming languages to significantly reduce computational time. Using Open Source applications in Go and Scala, the tool detects candidate scientific names and compares them to millions of scientific name-strings aggregated by GNA for verification. The new process decreases the time needed for name detection and name verification from 35 days to 5 hours and from 7 days to 12 hours, respectively. As a result, the entire BHL corpus can now be indexed in less than a day, compared to the 45 days needed for the previous index. Additionally, by significantly reducing computational time, implementing iterative improvements to the index is now achievable.

The accuracy of the names identified has also been improved with this deployment. By eliminating questionable results and false positives from the previous index, gnfinder produces a more accurate index of names in BHL. More than 34 million unique names — representing more than 239 million total instances of taxonomic name strings — were identified across the BHL corpus as of 21 July 2020. Of these, approximately 11.7 million are “Verified Names”, meaning they are unique names that have been resolved against a name authority (NameBank, Catalogue of Life, etc).

The gnfinder tool was developed by Dmitry Mozzherin and Alexander Myltsev as part of GNA project work at the University of Illinois at Urbana-Champaign. Mozzherin shared more about the process of developing this tool at the Biodiversity Next conference in Leiden, The Netherlands in 2019. Learn more in the presentation slides.

You can learn more about how the BHL implementation of the gnfinder tool works in our FAQ.

We would like to thank our colleagues at Global Names Architecture — especially Dmitry Mozzherin, Alexander Myltsev, and David Patterson — for their work to develop these tools. Thanks also to Joel Richard (BHL Technical Coordinator and Head of Web Services and IT at Smithsonian Libraries) and Mike Lichtenberg (BHL Lead Developer) for their work to deploy gnfinder on the BHL website.

If you have questions about gnfinder or would like to provide feedback or suggestions, please contact Global Names Architecture via the Global Names BHL project on GitHub.

Global Names development on BHL indexing is supported by National Science Foundation grants #1356347 and #1645959 as well as the Species File Group at the University of Illinois.

July 21, 2020by michelle.underhill
BHL News, Blog Reel, Tech Updates

Changes Coming to the BHL Data Exports Files on 10 April 2019

On 10 April 2019, we will implement additions and changes to the export files available from the Biodiversity Heritage Library.

The updates involve the following:

  1. A new set of exports will be created alongside the existing exports. The new set will contain only data for material that is hosted by BHL. No externally-hosted content will be included in these files. Because these files are added in addition to the existing export files, no existing users should be affected.
  2. The BHL author Identifiers will be added to the creator.txt and partcreator.txt tab-delimited files. The format of these files will change to accommodate the additional data; the author identifier will now be the second “column” in each file. Because of this, anyone regularly harvesting from these files may be affected.

Additional detailed information about these updates will be reflected on the Data Exports: Developer and Data Tools webpage, effective 10 April 2019.

If you have questions, please feel free to submit feedback via this form.

April 3, 2019by michelle.underhill
Blog Reel, User Stories

What’s This Bird? Classify Old Natural History Drawings with R

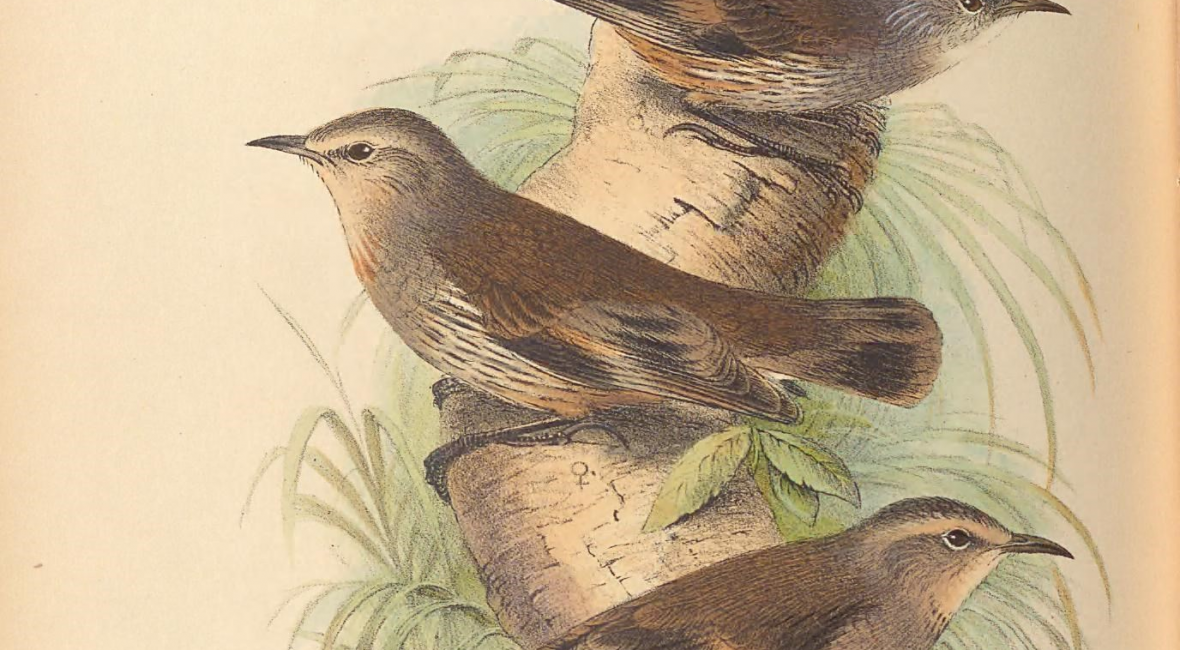
illustration of birds

This post was originally published on the rOpenSci blog on 28 August 2018 and is republished with permission of the author, Dr. Maëlle Salmon, and rOpenSci.

Armed with rOpenSci’s packages binding powerful C++ libraries and open taxonomy data, how much information can we automatically extract from images? Maybe not much, but, experimenting with gorgeous drawings from a natural history collection, we can least explore image manipulation, optical character recognition (OCR), language detection, and taxonomic name resolution with rOpenSci’s packages.

Free natural history images and appropriate R tooling!

A long time ago I had bookmarked the Flickr account of the Biodiversity Heritage Library (BHL). So many beautiful images of biodiversity, moreover free to use! In particular, I downloaded all pictures from one of the Birds of Australia albums (contributed in BHL by Museums Victoria).

I wanted to try to extract the bird names from images using packages of Jeroen Ooms’, rOpenSci’s post-doc hacker & C(++)-bindings wizard. For that I worked with magick for image manipulation, tesseract for optical character recognition (OCR), cld2/cld3 for language detection… Quite the armory! We’ll also sprinkle some taxonomy magic by Scott Chamberlain, one of rOpenSci’s co-founders, to resolve the names extracted.

OCR bird naming workflow, piece by piece

In this section, we explain the different elements of our R workflow: preparing images, extracting text, resolving taxonomic names.

Image preparation

I saved the pictures locally in a “birds” folder. Yes, I click-buttoned instead of using the Flickr API for which e.g. Jim Hester wrote a minimal R wrapper… I don’t do everything with R scripts (yet).

library("magrittr") 
filenames <- fs::dir_ls("birds")

Each image shows a bird and its name. Images are either landscape- or portrait-oriented, but for the sake of simplicity, I’ll act as if they were all portrait-oriented. A possible easy and lazy fix here would be to duplicate images rotated (magick::image_rotate) in all possible directions and then to apply the workflow to all 4 versions of each image, hoping to get good data from one of the rotated versions.

magick::image_read(filenames[1])
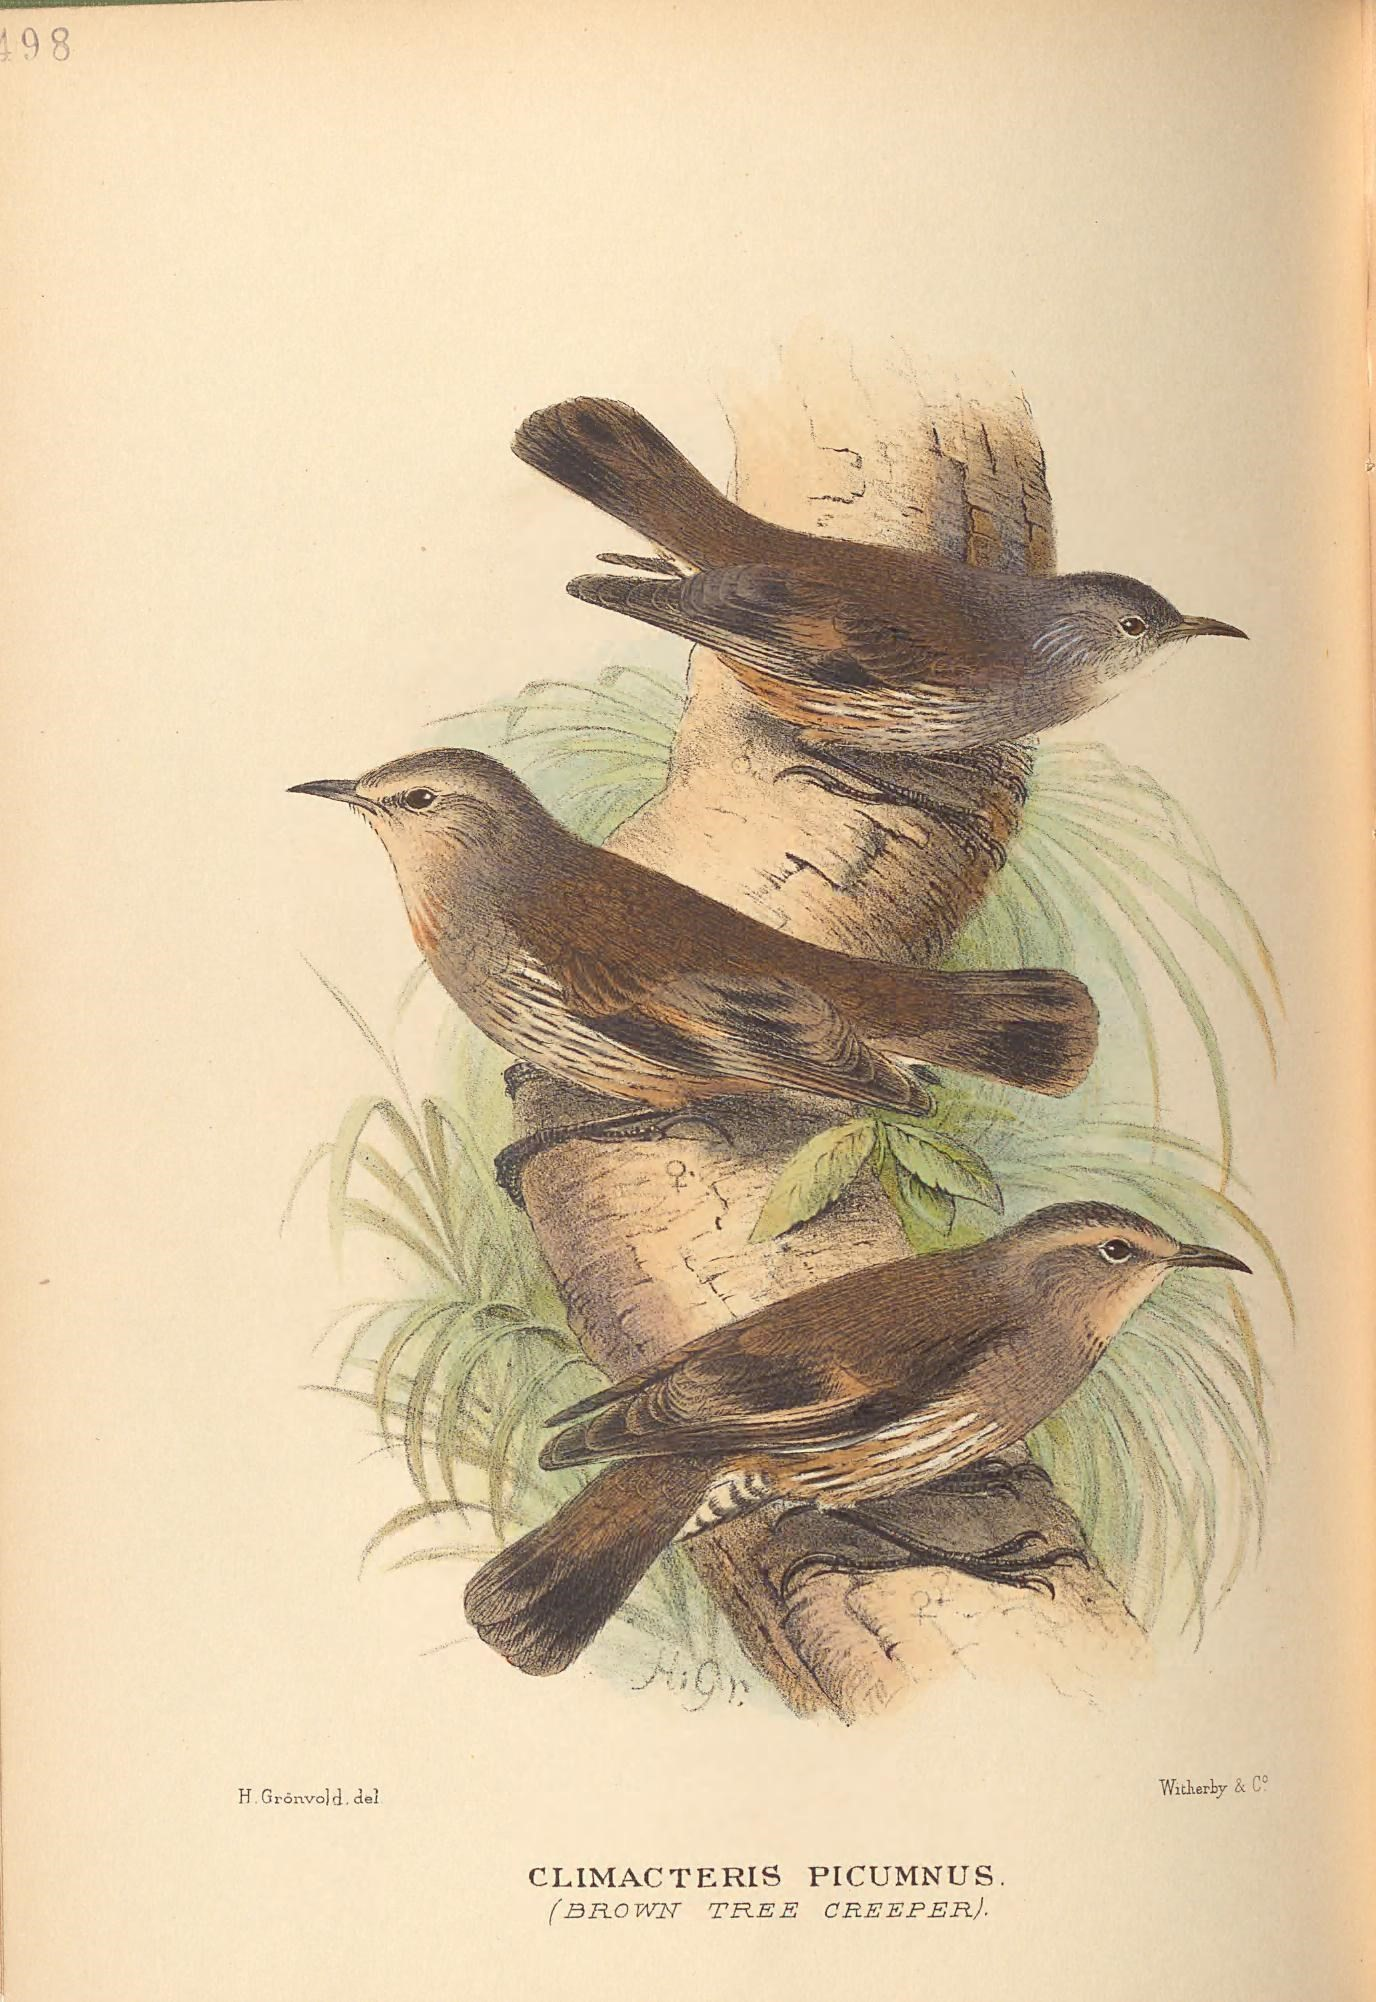
illustration of birds

Mathews, Gregory M. The Birds of Australia. v. 11 (1923-24). Art by Henrik Grönvold. Contributed in BHL from Museums Victoria.

From that image, I wanted to extract the name indicated below the bird. To maximize the efficiency of OCR, I shall first prepare the image, since the accuracy of OCR depends on the quality of the input image which can be influenced a bit. This part could be tweaked even more, and in real life examples it’ll be worth spending time trying different magick functions and parameter values. Since I have in mind the case of a bunch of images to be batch-processed, nothing is done by hand.

crop_bird <- function(filename){
  image <- magick::image_read(filename)

  height <- magick::image_info(image)$height

  # crop the top of the image
  image <- magick::image_crop(image, 
                     paste0("+0+",round(0.75*height))) %>%
    # convert the image to black and white
    magick::image_convert(type = "grayscale") %>%
    # increase brightness
    magick::image_modulate(brightness = 120) %>%
    magick::image_enhance() %>%
    magick::image_median() %>%
    magick::image_contrast() 

  # we'll need the filename later
  attr(image, "filename") <- filename

  return(image)
}

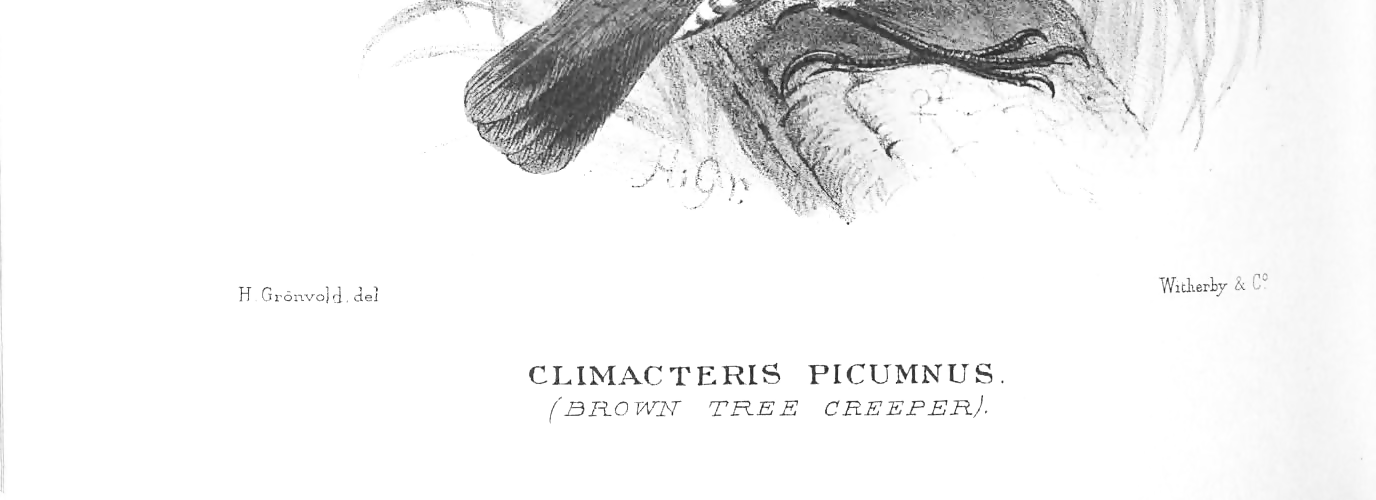
crop_bird(filenames[1])

scientific name of birds on a drawing

It does look cleaner now!

Text extraction

Now is the actual OCR step! The tesseract package provides bindings to the Tesseract OCR engine, free software currently sponsored by Google. It is a powerful engine, with a ton of parameters. Here again, tweaking a lot is warranted. Particularly useful reads are hocr vignette and this Wiki page of Tesseract about improving the quality of the output. The hocr package might be of interest for post-processing of OCR results.

Below, the only option changed from default is the page segmentation mode choosing 1 for “Automatic page segmentation with Orientation and script detection (OSD)”. When using Latin instead of English training data the results were not as good.

One can use either tesseract::ocr for a file path, url, or raw vector to image, or magick::image_ocr for a magick object which is quite handy in our pipeline.

The function below also filters results of the OCR using language detection. By only keeping text recognized as either Latin or English by one of the two language detection packages cld2 and cld3 that are interfaces to Google compact language detectors 2 and 3, one gets a first quality filter. If not doing that, the output would contain more unusable text.

get_names <- function(image){
  filename <- attr(image, "filename")
  ocr_options <- list(tessedit_pageseg_mode = 1)

  text <- magick::image_ocr(image, options = ocr_options)
  text <- stringr::str_split(text, "\n", simplify = TRUE)
  text <- stringr::str_remove_all(text, "[0-9]")
  text <- stringr::str_remove_all(text, "[:punct:]")
  text <- trimws(text)
  text <- stringr::str_remove_all(text, "~")
  text <- text[text != ""]
  text <- tolower(text)

  # remove one letter words
  # https://stackoverflow.com/questions/31203843/r-find-and-remove-all-one-to-two-letter-words
  text <- stringr::str_remove_all(text, " *\\b[[:alpha:]]{1,2}\\b *")
  text <- text[text != ""]

  # keep only the words that are recognized as either Latin
  # or English by cld2 or cld3
  if(length(text) > 0){
    results <- tibble::tibble(text = text,
                 cld2 = cld2::detect_language(text),
                 cld3 = cld3::detect_language(text),
                 filename = filename)

  results[results $cld2 %in% c("la", "en") |
          results$cld3 %in% c("la", "en"),]
  }else{
    return(NULL)
  }


}

(results1 <- filenames[1] %>%
  magick::image_read() %>%
  get_names())
## NULL

Nothing! Now if we replace magick::image_read with the previously defined crop_bird function that crops and cleans the image…

(results2 <- filenames[1] %>%
  crop_bird() %>%
  get_names())
## # A tibble: 2 x 4
##   text                 cld2  cld3  filename                          
##   <chr>                <chr> <chr> <chr>                             
## 1 climacteris picumnus <NA>  la    birds/n115_w1150_42399797481_o.jpg
## 2 brown tree creeper   en    <NA>  birds/n115_w1150_42399797481_o.jpg

We get a result! So we see that the image transformation was quite useful.

Now, these names look fine, but how to be sure they’re actually taxonomic names?

Taxonomic name resolution

The taxize package by Scott Chamberlain, is a taxonomic toolbelt for R, providing access to many fantastic data sources and tools for taxonomy. One of them, the Global Name Resolver, provides, well, resolution of taxonomic names, sadly not common names. taxize::gnr_resolve has many options, of which only one is used below: best_match_only = TRUE means it’ll only return the best match from the different data sources.

latin <- results2$text[results2$cld2 == "la"|
                         results2$cld3 == "la"]
taxize::gnr_resolve(latin,
  best_match_only = TRUE)
## # A tibble: 1 x 5
##   user_supplied_name submitted_name  matched_name   data_source_tit~ score
## * <chr>              <chr>           <chr>          <chr>            <dbl>
## 1 climacteris picum~ Climacteris pi~ Climacteris p~ NCBI             0.988

English names could be cleaned up a bit using the spelling package, also an rOpenSci package, since spelling::spell_check_text would output possible typos.

OCR bird naming workflow in action!

First the two steps image processing and OCR are applied to all images.

bird_names <- purrr::map(filenames, crop_bird) %>%
  purrr::map_df(get_names)

Out of 51 images only 17 are present in the final table with possible names which is a bit disheartening, but one could surely do better in the image processing and OCR tweaking steps! Maybe one could frame the parameter search as a machine learning problem. Please also keep in mind that such natural history images are quite hard to parse.

The name resolution information can be added to this table.

safe_resolve <- function(text){

  results <- taxize::gnr_resolve(text,
                                 best_match_only = TRUE)

  if(nrow(results) == 0){
    list(NULL)
  }else{
    list(results)
  }
}

bird_names <- dplyr::group_by(bird_names, text) %>%
  dplyr::mutate(gnr = ifelse(cld2 == "la" | cld3 == "la",
                             safe_resolve(text),
                             list(NULL)))

We do not get much resolution, but we knew the names weren’t very good to start with. A better (untested here!) idea here might be to get a full list of names of Australian birds, potentially leveraging the taxizedb package by Scott Chamberlain, and to then fuzzy-match them with the names we have.

unique(bird_names$gnr)
## [[1]]
## # A tibble: 1 x 5
##   user_supplied_name submitted_name  matched_name   data_source_tit~ score
## * <chr>              <chr>           <chr>          <chr>            <dbl>
## 1 climacteris picum~ Climacteris pi~ Climacteris p~ NCBI             0.988
## 
## [[2]]
## [1] NA
## 
## [[3]]
## NULL
## 
## [[4]]
## # A tibble: 1 x 5
##   user_supplied_na~ submitted_name  matched_name  data_source_title  score
## * <chr>             <chr>           <chr>         <chr>              <dbl>
## 1 austrodicaeum ii~ Austrodicaeum ~ Austrodicaeu~ The Interim Regis~  0.75
## 
## [[5]]
## # A tibble: 1 x 5
##   user_supplied_name submitted_name  matched_name   data_source_tit~ score
## * <chr>              <chr>           <chr>          <chr>            <dbl>
## 1 melithreptus laet~ Melithreptus l~ Melithreptus ~ CU*STAR          0.988
## 
## [[6]]
## # A tibble: 1 x 5
##   user_supplied_na~ submitted_name matched_name  data_source_title   score
## * <chr>             <chr>          <chr>         <chr>               <dbl>
## 1 rad isdlvorniode  Rad isdlvorni~ Rad Baker & ~ The Interim Regist~  0.75

Conclusion

rOpenSci packages supporting this (and your) workflow

In this post, we made use of R packages quite useful to wrangle information from diverse formats:

  • magick for image manipulation,
  • tesseract for optical character recognition (OCR),
  • cld2/cld3 for language detection.

We also used a function from taxize allowing us to use the Global Name Resolver. Discover more packages from our suite here.

Applicability of this OCR bird naming workflow

Actually, the BHL itself provides OCR output for its collection, see this example. I wasn’t able to find information about the software powering this OCR. What I was able to find out is that the BHL uses purposeful gaming in its OCR workflow. The raw OCR results aren’t much better than what we got in this post which is comforting.

More data from the Biodiversity Heritage Library

If you’re interested in other types of data from the BHL, in addition to the images, have a look at the rbhl package, part of rOpenSci’s suite, that interacts with the BHL API. One can e.g. search all books by the same author as the one we used images from.

author <- rbhl::bhl_authorsearch("Gregory M Mathews")
books <- rbhl::bhl_getauthortitles(creatorid = author$CreatorID)
head(books$FullTitle)
## [1] "A manual of the birds of Australia,"                                                                                                                                                                                                                                          
## [2] "A list of the birds of the Phillipian sub-region : which do not occur in Australia. "                                                                                                                                                                                         
## [3] "A manual of the birds of Australia /"                                                                                                                                                                                                                                         
## [4] "A list of the birds of Australia : containing the names and synonyms connected with each genus, species, and subspecies of birds found in Australia, at present known to the author /"                                                                                        
## [5] "Austral avian record; a scientific journal devoted primarily to the study of the Australian avifauna."                                                                                                                                                                        
## [6] "Arcana, or, The museum of natural history : containing the most recent discovered objects : embellished with coloured plates, and corresponding descriptions : with extracts relating to animals, and remarks of celebrated travellers; combining a general survey of nature."

Or we could get all books whose title contains the words “birds” and “australia”.

australia_birds <- rbhl::bhl_booksearch(title = "birds Australia")
head(australia_birds$FullTitle)
## [1] "Handbook to the birds of Australia. : [Supplementary material in Charles Darwin's copy]."
## [2] "An introduction to The birds of Australia /"                                             
## [3] "The useful birds of southern Australia : with notes on other birds /"                    
## [4] "The Birds of Australia"                                                                  
## [5] "The birds of Australia,"                                                                 
## [6] "The birds of Australia,"

And to get the OCR results of the pages of the book we used, we could write:

library("magrittr")

# ocr=TRUE to extract OCR for all pages
rbhl::bhl_getitempages("250938", ocr = TRUE) %>%
  # for each page transform the type into a string
  dplyr::group_by(PageUrl) %>%
  dplyr::mutate(page_type = toString(PageTypes[[1]])) %>%
  # keep only the illustration pages
  # that are like the ones we used 
  dplyr::filter(page_type == "Illustration") %>%
  # from the data.frame extract the OCR
  dplyr::pull(OcrText) %>%
  head()
## [1] "491 \nFAL CUNCULUS LEUCOGASTER. \n( WHITE -BELLIED £ If BIKE - TIT) \nFALCUNCULUS FRONTATUS. \nSHRIKE - TIT). \n"                                                                                                                   
## [2] "492 \nA** \nOREOICA GUTTURALIS. \n(CRESTED BELL-BIRD). \n"                                                                                                                                                                          
## [3] "APHELOCEPHALA LEUCOPSIS \n( WHITE FACE ). \n"                                                                                                                                                                                       
## [4] "* \nAPHELOCEPHALA PE CTORALIS. \n(CHE <3 TNUT -BREASTED WHITEFA CEj. \nAPHELOCEPHALA NIGRICINCTA. \n(BE A CK-BAH.DED WHITE FA CEj. \n"                                                                                              
## [5] "H . Gronvold. del. \nWitherLy & C° \nSPHENOSTOMA CRIS TATUM \n(WEDGE BIEL). \n"                                                                                                                                                     
## [6] "49 6 \nH \n(jronvolcl. del. \nN E O SIT TA LE CJ C O CE PHAI.A. \n( WHITE ¦ HE AID EE THE EH UN HE FL). \nNEOSHTA ALBATA \n(F IE E> T Ft E EE UNNEFlj. \nNEOSITTA CHRYSOPTERA \nf OFi. A. NGE - wing-e d tree runner). \nWitWLjA \n"

So there’s quite a lot to explore!

More birding soon!

Follow this series on the rOpenSci blog to explore this topic further! In the meantime, happy birding!

October 4, 2018by michelle.underhill
BHL News, Blog Reel, Tech Updates

Announcing the New “About BHL” Site!

About BHL homepage

Homepage for the new “About BHL” site.

We’re excited to announce the launch of the new “About BHL” site!

What is BHL’s history? Who’s involved in the Library? What tools and services does BHL offer? How do you search, download content or access data and developer tools in BHL? How can you get involved in the Library? What projects has BHL engaged in?

Find the answers to these questions and much more information about the Biodiversity Heritage Library on our new “About BHL” site at about.biodiversitylibrary.org!

The new “About” site, which lives alongside and is linked from the BHL website at biodiversitylibrary.org, replaces our previous wiki-based “About BHL” pages and features several improved features and functionality. Read on to learn more about some of these new features.

New Look & Feel

The site has been designed to mirror the look of the BHL website. We’ve also integrated our social accounts into the site with streams for our Instagram, Twitter and blog feeds in the right sidebar. Also, check out our testimonials feed above the footer to learn more about BHL’s impact on global research from real users!

testimonials feed on new About site

Testimonials feed on new “About BHL” site.

Improved Navigation

With our new top menu and category-specific sidebar menus, it’s now easier than ever to navigate through our “About” content and find exactly what you need. But just in case you still can’t find what you’re looking for, we’ve placed a prominent “Contact Us” button in the header.

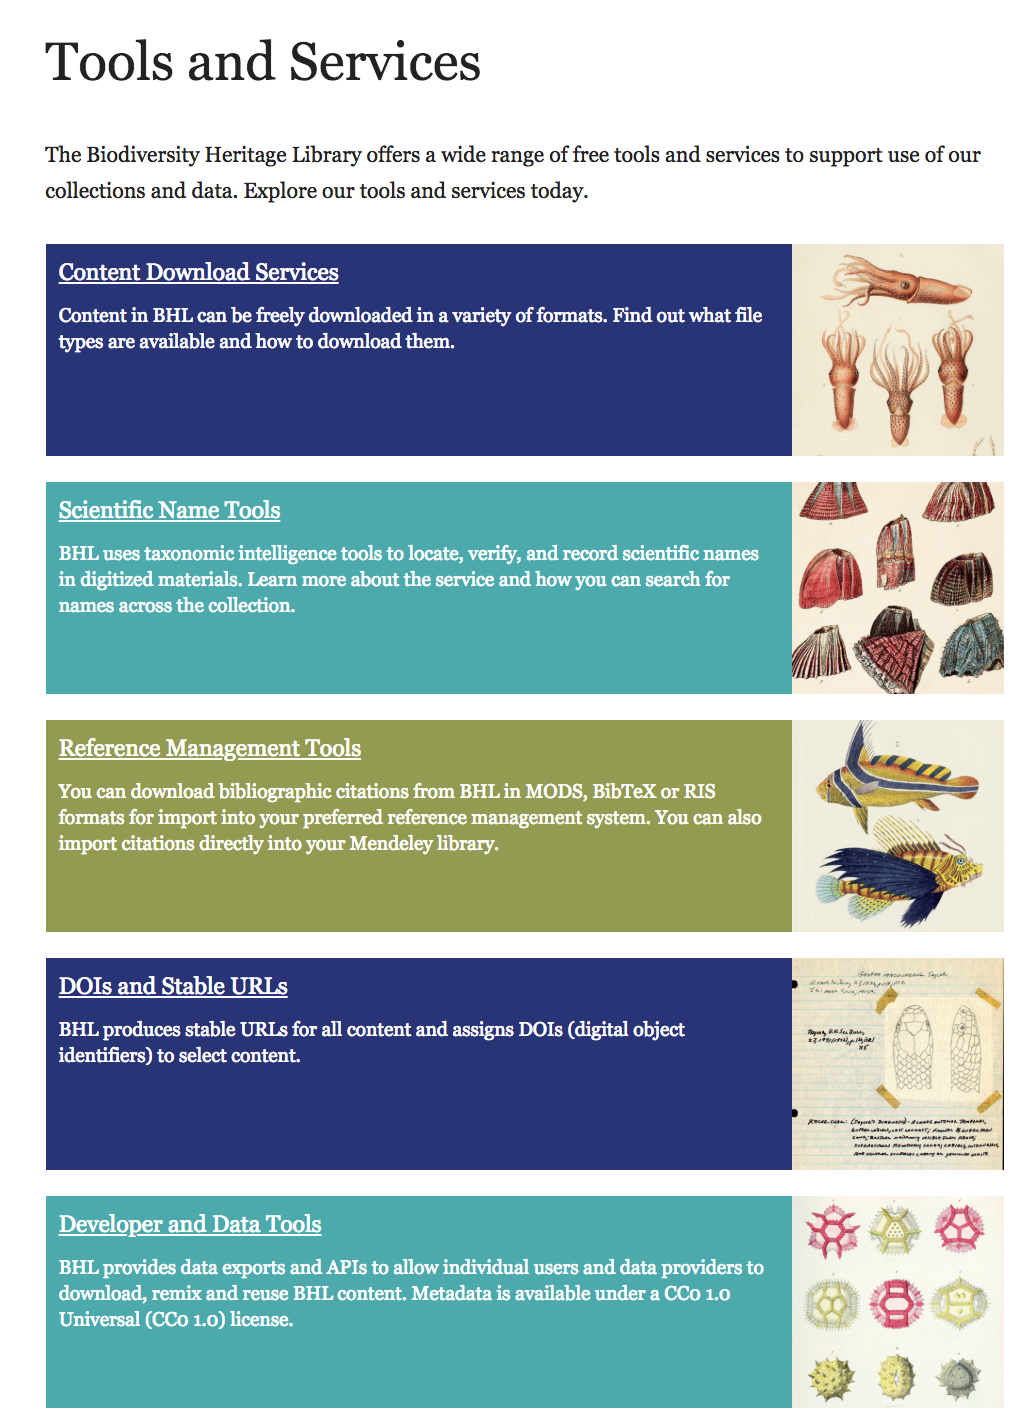
Consolidated Tools & Services

tools and services landing page on the new About site.

Tools and services landing page on the new “About BHL” site.

We consolidated links to information about our various tools and services into a single landing page to make it easier for you to explore what BHL has to offer and find the services you need.

New FAQ Center

We’ve created a new FAQ center to help answer some of the most frequent questions we receive. We’ll continue to add to this FAQ with new questions as appropriate. Have a question you don’t see listed? Send us feedback and we can add it!

Have questions or comments about the new “About BHL” site? Feel free to contact us or leave a comment on this post.

September 17, 2018by michelle.underhill

Help Support BHL

BHL's existence depends on the financial support of its patrons. Help us keep this free resource alive!

search

About BHL

The Biodiversity Heritage Library (BHL) is the world’s largest open access digital library for biodiversity literature and archives. BHL operates as a worldwide consortium of natural history, botanical, research, and national libraries working together to digitize the natural history literature held in their collections and make it freely available for open access as part of a global “biodiversity community.”

Join Our Mailing List

Sign up to receive the latest news, content highlights, and promotions.

Subscribe Now

Subscribe to Blog via Email

Enter your email address to subscribe to this blog and receive notifications of new posts by email.

Join 319 other subscribers

Subscribe to Blog Via RSS

Subscribe to the blog RSS feed to stay up-to-date on all the latest BHL posts.

Access RSS Feed

Inspiring Discovery through Free Access to Biodiversity Knowledge.

The Biodiversity Heritage Library makes it easier than ever for you to access the information you need to study and explore life on Earth…for free, anytime, anywhere.


64+ Million Pages of
Biodiversity Literature Online.

EXPLORE

Tools and Services
to Transform Research.

EXPLORE

300,000+
Illustrations on Flickr.

EXPLORE

ABOUT | HARMFUL CONTENT | PRIVACY | SITE MAP | TERMS OF USE