Biodiversity Heritage Library - Program news and collection highlights from BHL
  • Home
  • News
  • Featured Books
    • All Featured Books
    • Book of the Month Series
    • BHL at 20
  • User Stories
  • Campaigns
    • Fossil Stories
    • Garden Stories
    • Monsters Are Real
    • Page Frights
    • Her Natural History
    • Earth Optimism 2020
  • Tech Blog
  • Visit BHL
Home
News
Featured Books
    All Featured Books
    Book of the Month Series
    BHL at 20
User Stories
Campaigns
    Fossil Stories
    Garden Stories
    Monsters Are Real
    Page Frights
    Her Natural History
    Earth Optimism 2020
Tech Blog
Visit BHL
  • Home
  • News
  • Featured Books
    • All Featured Books
    • Book of the Month Series
    • BHL at 20
  • User Stories
  • Campaigns
    • Fossil Stories
    • Garden Stories
    • Monsters Are Real
    • Page Frights
    • Her Natural History
    • Earth Optimism 2020
  • Tech Blog
  • Visit BHL
Biodiversity Heritage Library - Program news and collection highlights from BHL
BHL News, Blog Reel, Tech Updates

Interlinking BHL Data in the Wikimedia Project Ecosystem

Cover of white paper with image of earth from space

The planet is at a critical juncture, where urgent action is required to combat climate change, biodiversity loss, and secure a sustainable future for our planet. With the release of the recent BHL Wikimedia white paper entitled Unifying Biodiversity Knowledge to Support Life on a Sustainable Planet, the Biodiversity Heritage Library Secretariat hopes that an expanded data vision for the BHL community presents new opportunities to take bold steps forward into Wikimedia projects and the emergent semantic web.

Cover of white paper with image of earth from space

Dearborn, J. (2023). Unifying Biodiversity Knowledge to Support Life on a Sustainable Planet. Biodiversity Heritage Library. https://doi.org/10.21428/bcf8962c.699434fb

The white paper sheds light on BHL’s crucial role as a member of the biodiversity informatics community and reveals a series of key use cases and big data challenges that, if addressed, could be opportunities to enhance global biodiversity data infrastructure.

Addressing BHL’s Big Data Challenges

Three significant challenges remain for BHL to solve in the era of big data:

  1. correcting and transcribing OCR text;
  2. improving search precision and retrieval within the BHL interface; and
  3. expanding interlinkages and deposits of data from BHL into global knowledge bases, e.g. depositing species occurrence data in Global Biodiversity Information Facility (GBIF).

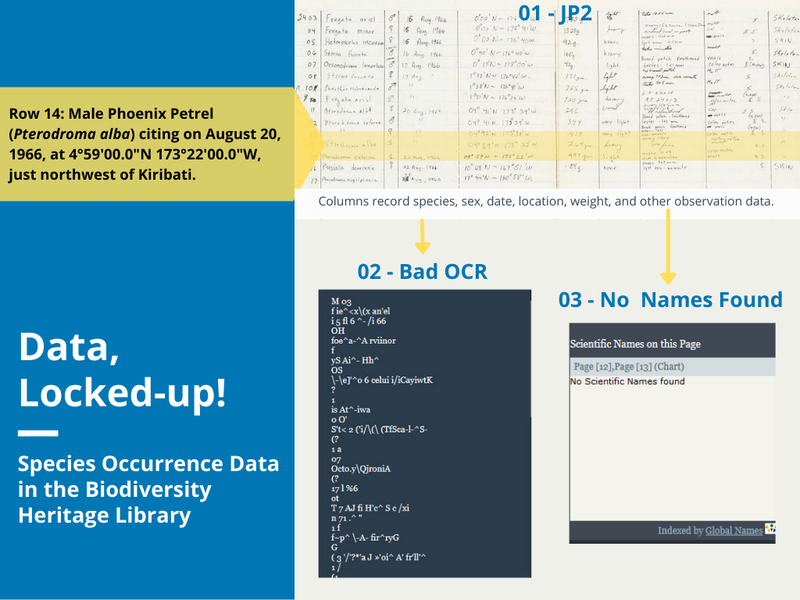
Example of handwritten observation data with poor quality OCR and no scientific names found on the page

By working to address these challenges, BHL aims to ensure data accuracy, enhance user experience, and forge stronger connections within the global biodiversity data infrastructure.

If liberated, the data in BHL’s collection will:

  1. improve scientific understanding of ecological change, deeper into time;
  2. assist decision-makers in shaping global environmental policy informed by the historical record; and
  3. bridge knowledge gaps and facilitate information exchange regarding our planet’s history.

Unlocking BHL’s Power with Wikimedia Projects

Within the white paper, Wikimedia’s core projects, particularly Wikidata, take center stage. BHL is already engaged in projects to load title, author and article metadata into Wikidata. By integrating more of BHL’s biodiversity and climate-related data into the collaborative and unified ecosystem of Wikidata, BHL can unlock new opportunities for data-driven insights.

Thumbnails of each chapter and appendix in the white paper

Call to Action: Vote for the Most Impactful Use Cases!

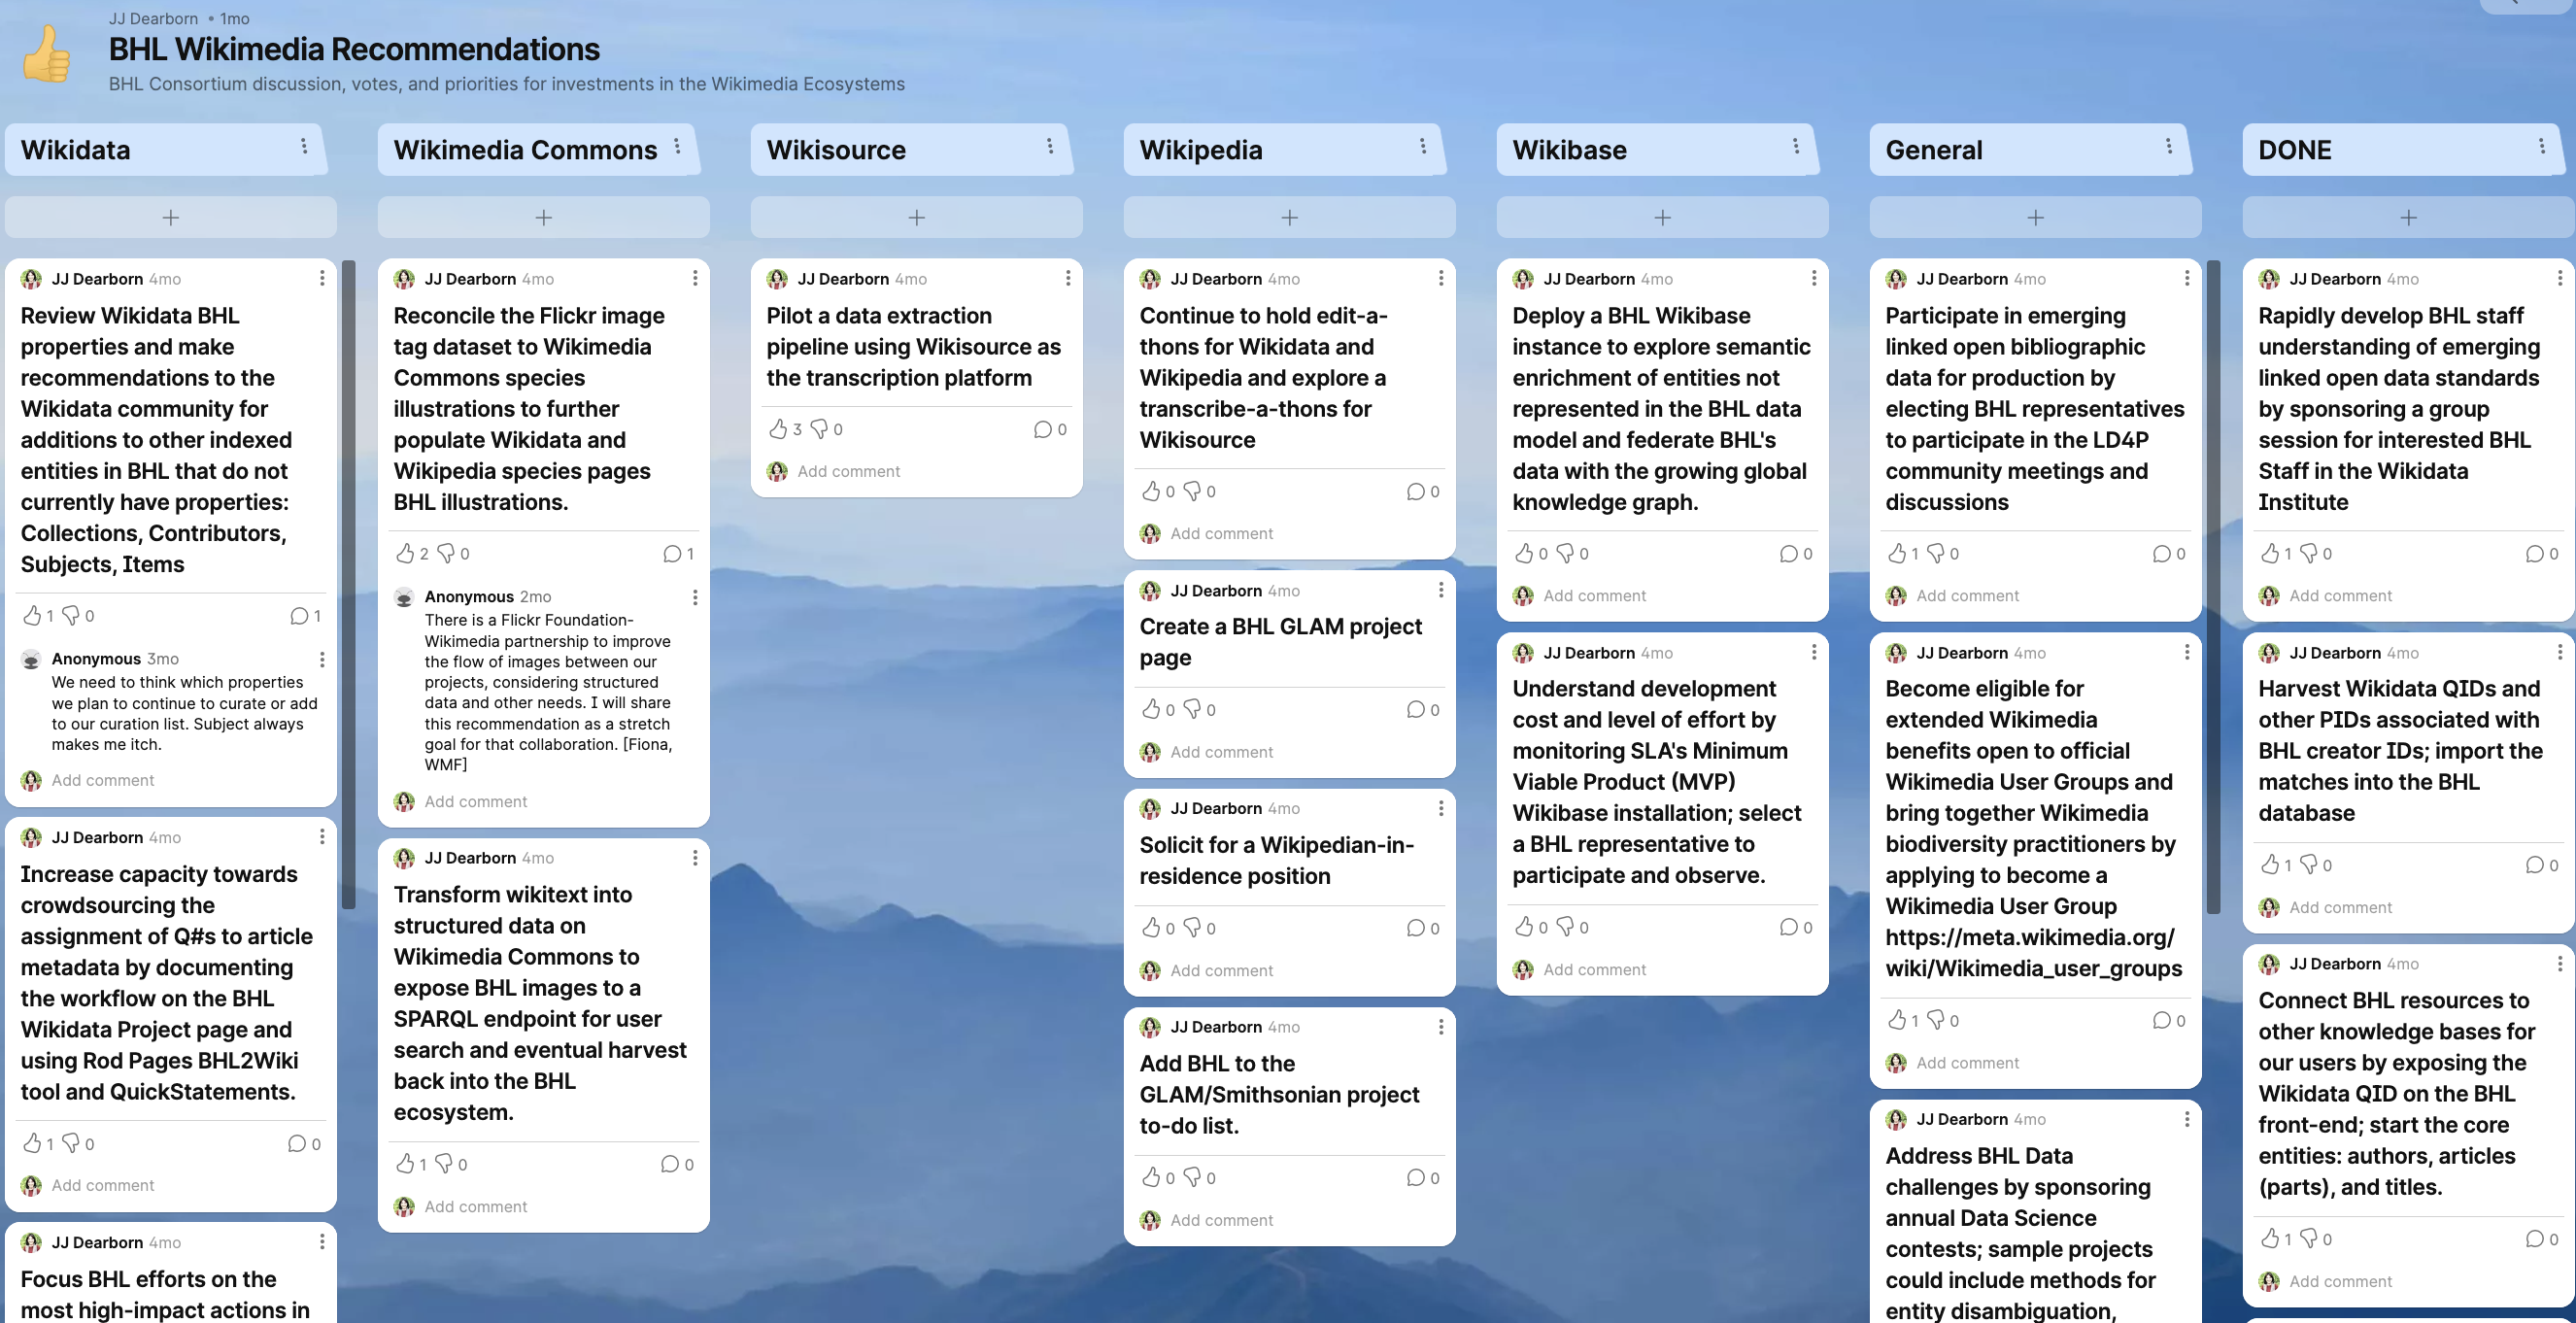
BHL partners, Wikimedians, and key BHL collaborators are encouraged to actively participate in shaping the future of BHL by voting and commenting on which use cases the community believes will have the most significant impact. Your input and insights are invaluable in guiding the direction of BHL’s Wikimedia projects. Visit the voting platform to share your thoughts, provide feedback, and cast your vote to take action on 25 recommended use cases. Let’s work together to identify the areas of maximum impact for BHL that will help transform BHL’s data into interlinked knowledge in the semantic web.

Screenshot of 25 BHL wikimedia recommendations on voting platform

VOTE NOW!

Through a range of potential applications for BHL data in the Wikimedia ecosystem and the pursuit of solutions for BHL’s big data challenges, BHL is making the case for deeper integration of its collection into biodiversity knowledge networks. The release of the white paper demonstrates unique opportunities for BHL to improve biodiversity research infrastructure, increase understanding of our planet’s biodiversity and impact climate policy.

August 25, 2023by mdimeo
BHL News, Blog Reel, Tech Updates

BHL is Round Tripping Persistent Identifiers with the Wikidata Query Service

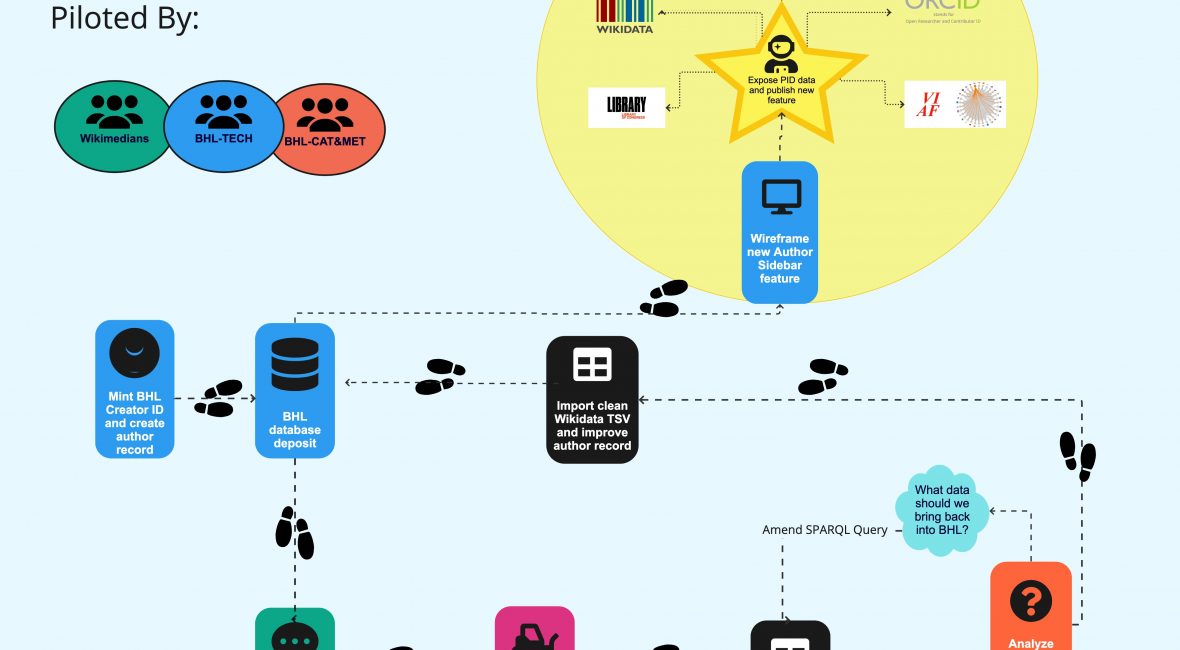
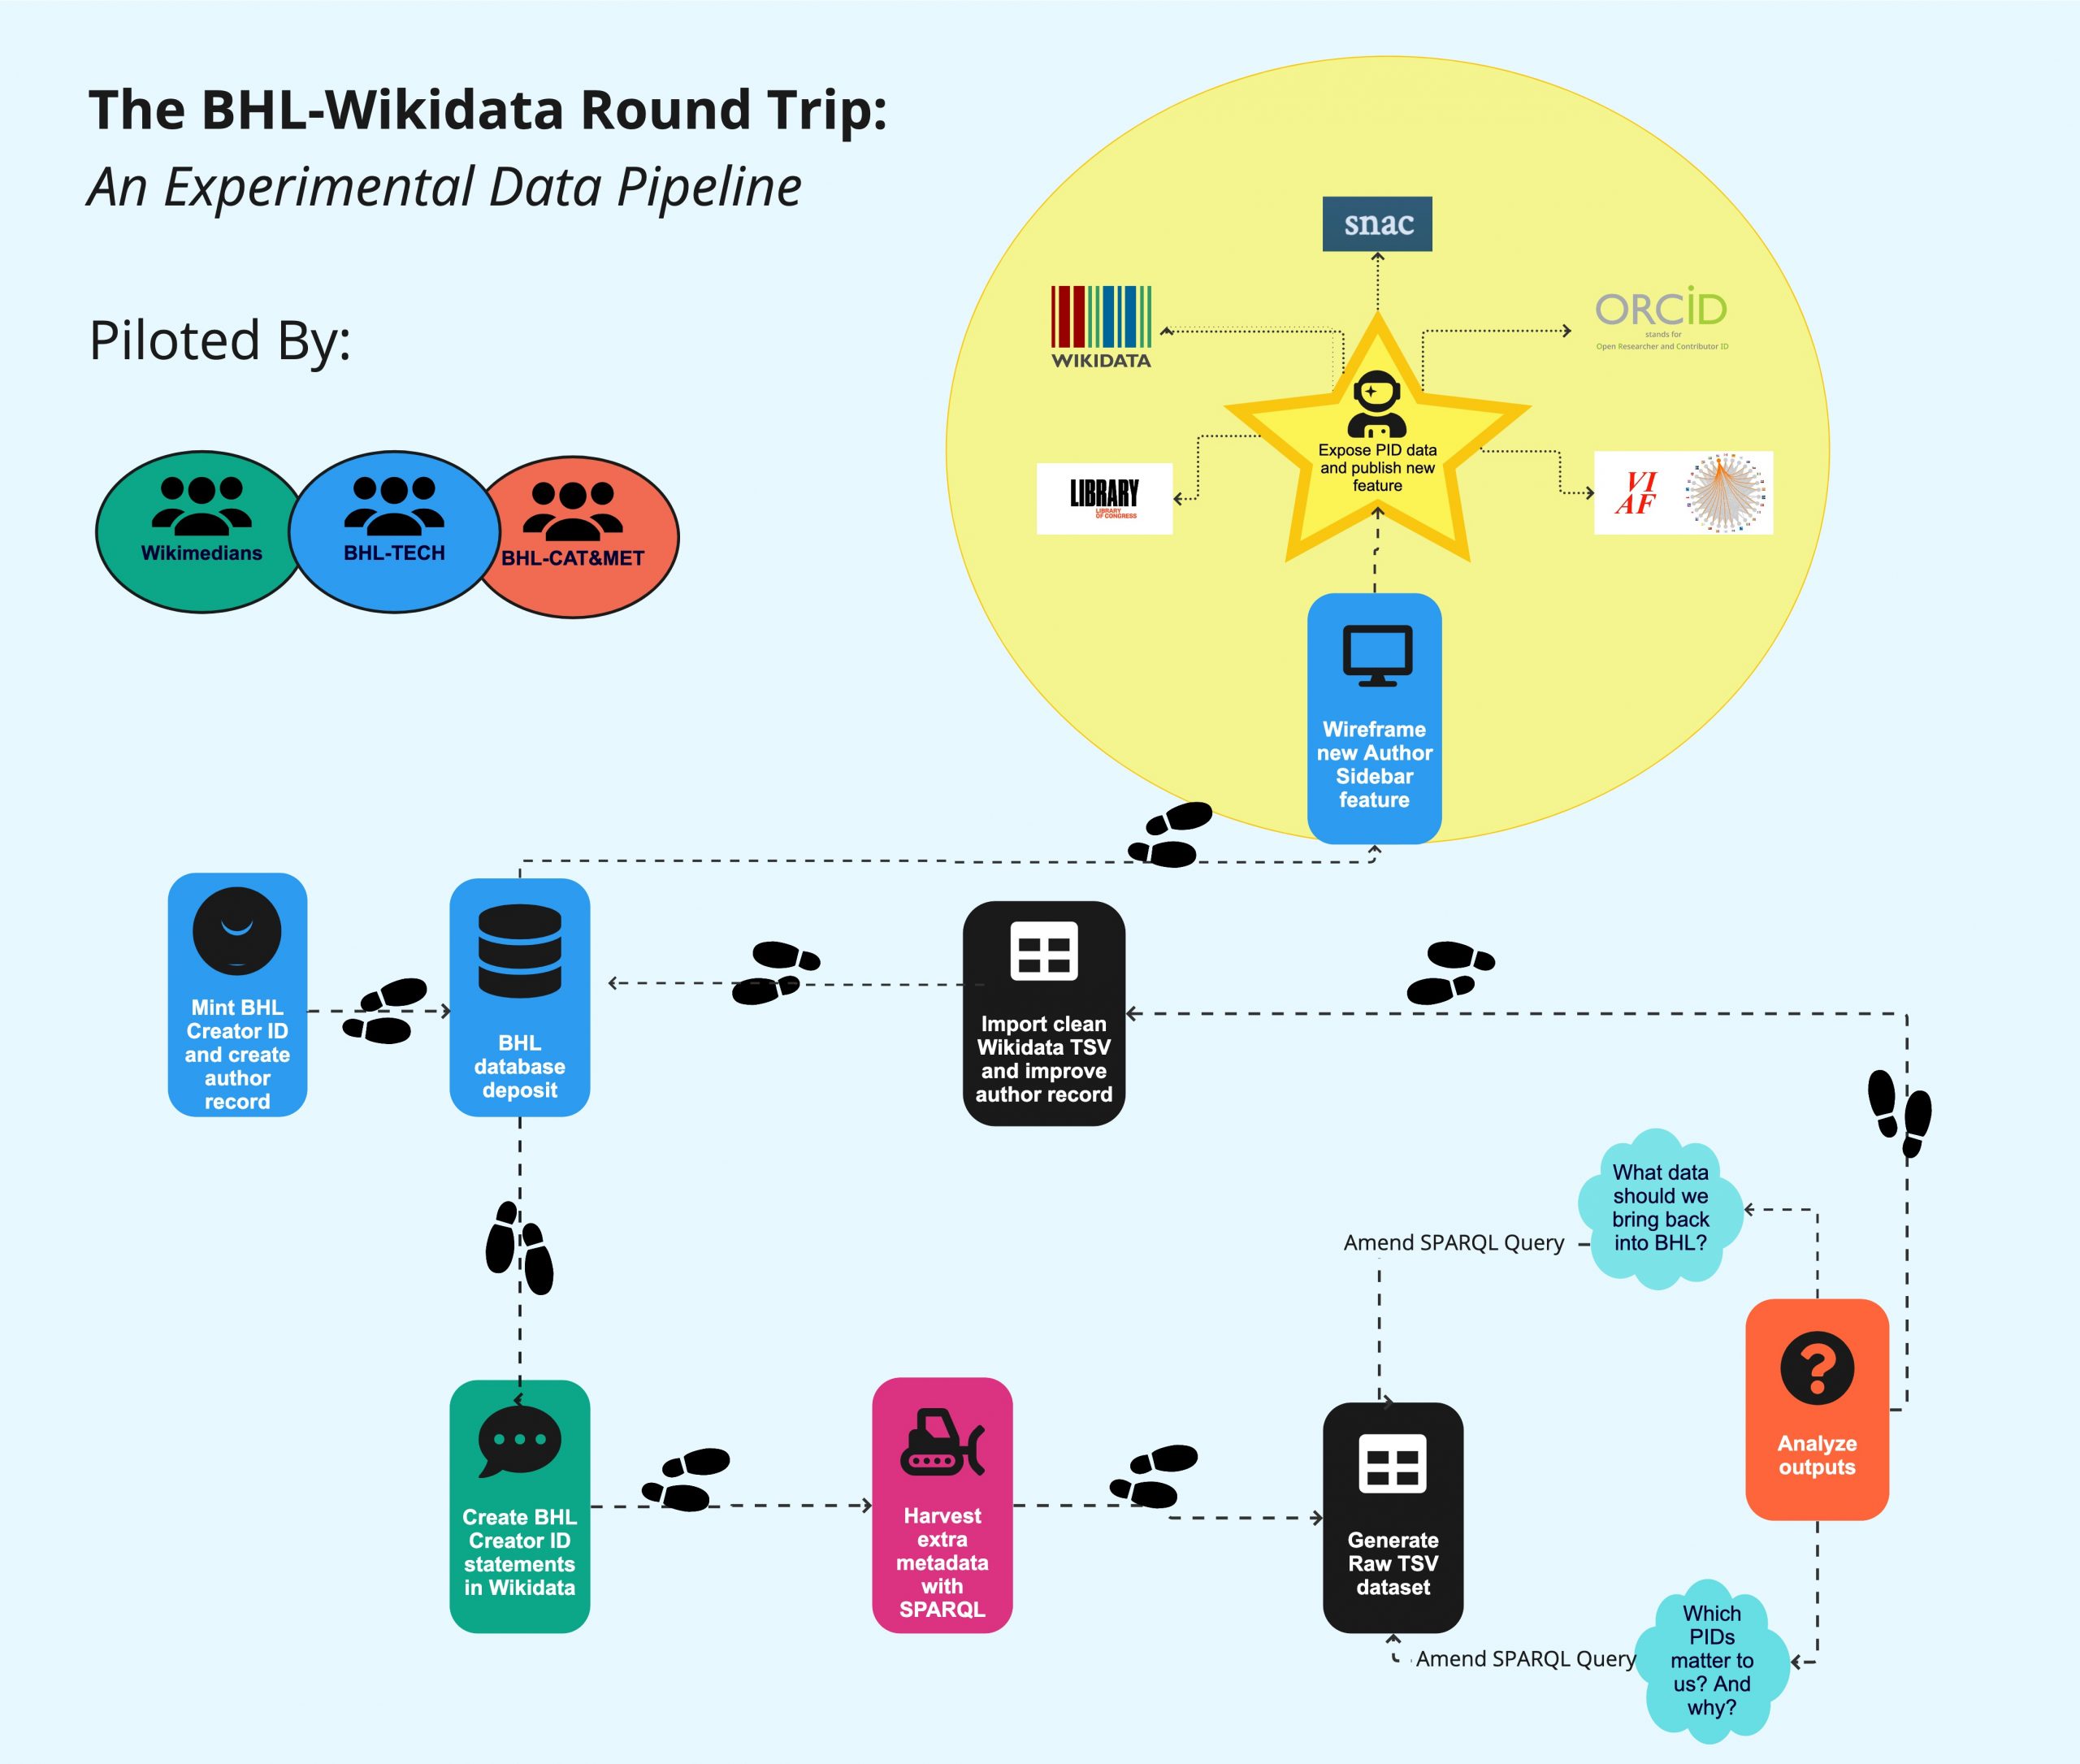
Diagram of the 8 steps detailed below of the BHL wikidata round trip.

In the Spring of 2022, the BHL Cataloging and Metadata Committee investigated the possibility of harvesting persistent identifiers (PIDs) from Wikidata as part of the group’s longstanding project to disambiguate and deduplicate author records in the BHL database. The motivation behind this one-time experimental data harvest was to see if BHL could:

  1. Enhance BHL author records with additional PID data points;
  2. Improve the committee’s ability to disambiguate author names in the BHL database; and
  3. Respond to an outstanding user request from two of Wikimedia’s super star editors, Siobhan Leachman and Andy Mabbett, to expose BHL’s author data on BHL and include hyperlinks to other authoritative knowledge bases on the web.
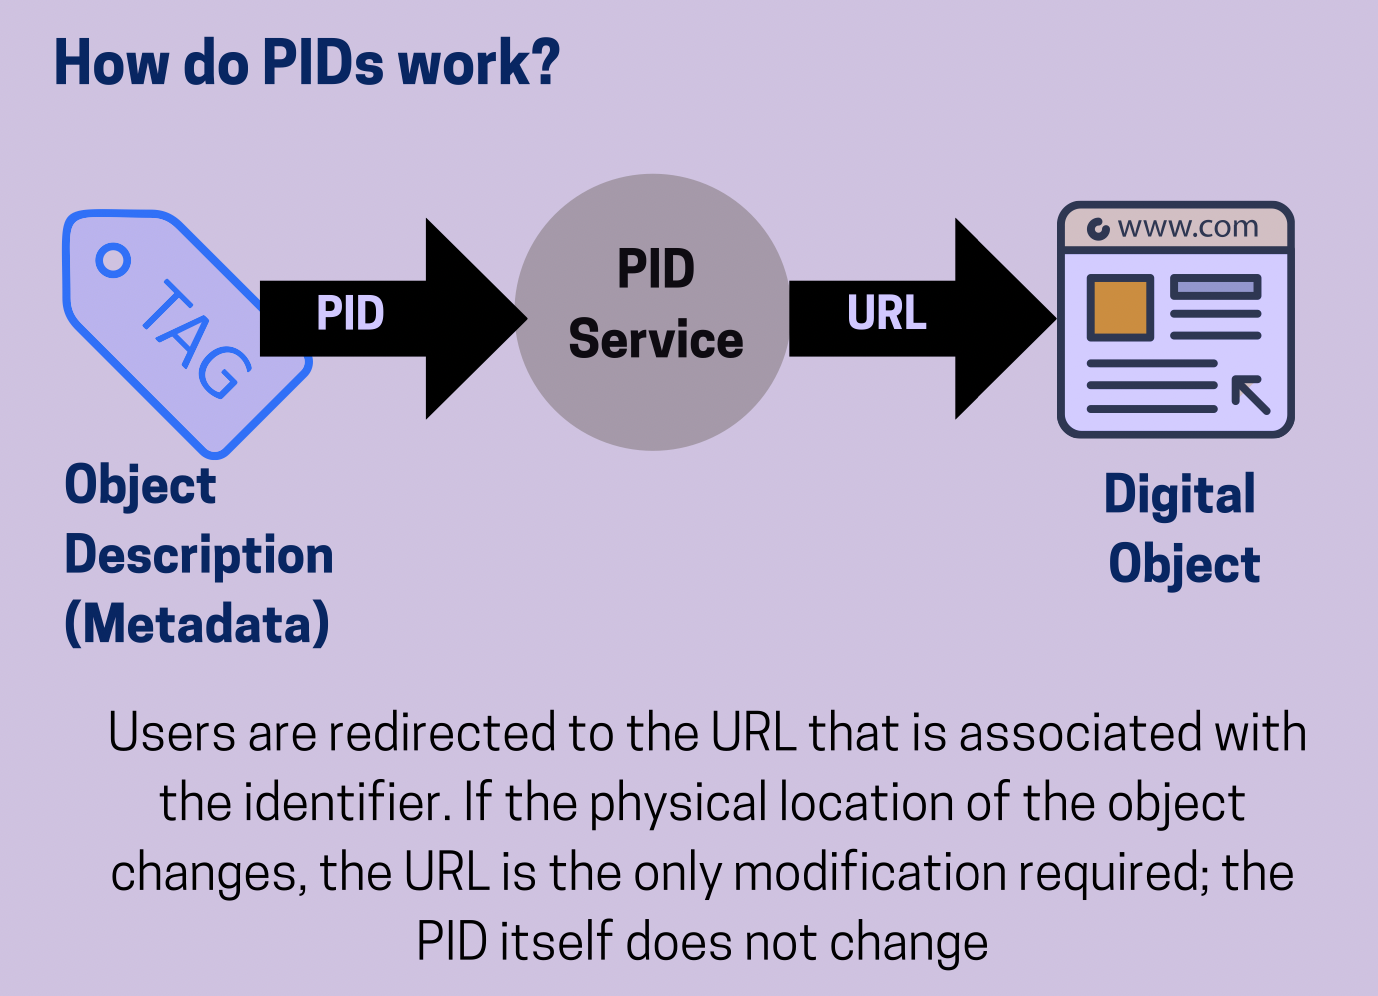
How do PIDs work? Users are directed to the URL that is associated with the identifier. If the physical location of the object changes, the URL is the only modification required; the PID itself does not change.

Persistent identifiers can become resolvable links that connect two knowledge bases (like BHL and Wikidata) together.

In particular, Wikimedians wanted to see the Wikidata Q identifier exposed, providing a link to the corresponding creator item record in Wikidata.

There are multiple motivations for undertaking this work. By adding the BHL Creator ID to the corresponding Wikidata item, Wikidata editors help link BHL to the richer biographical data about that person held in Wikidata. The Wikidata item for a person may contain links to their Wikipedia page or to images of the person held in the image repository Wikimedia Commons. Wikidata items also act as identifier hubs and contain links to other databases and identifiers.

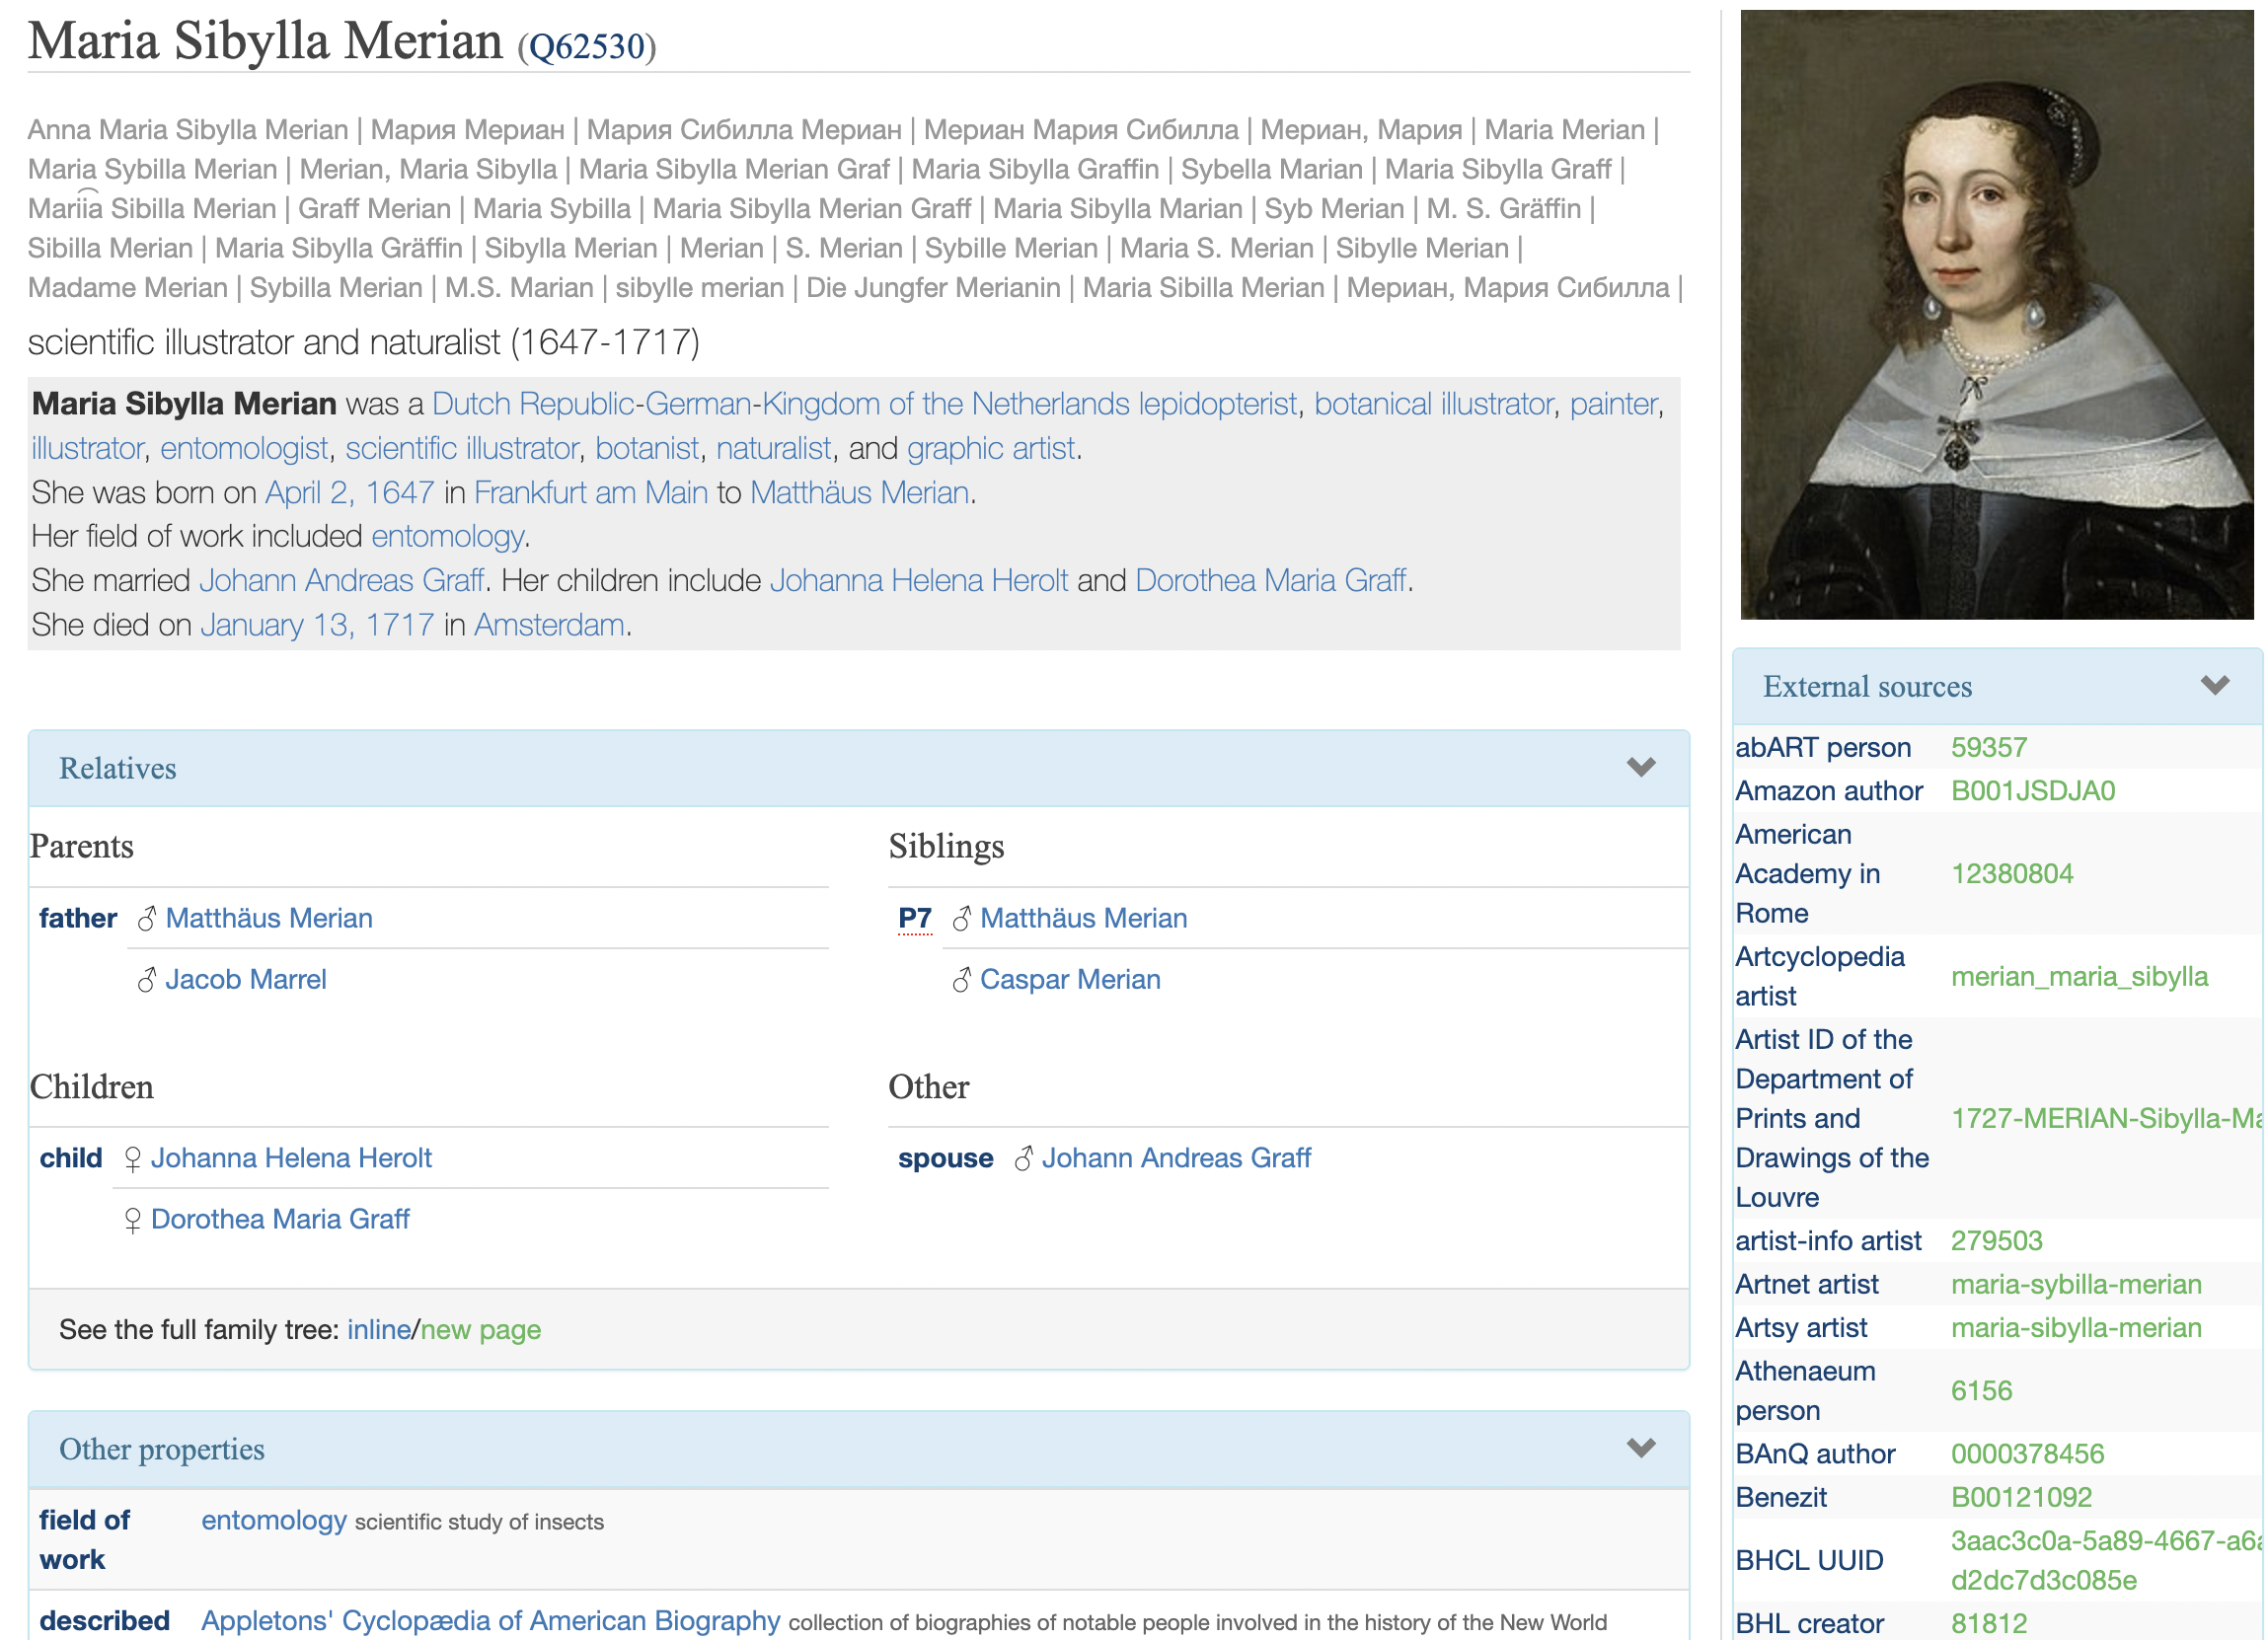
Maria Sibylla Merian's wikidata entry, including name variants, biographical information, external sources, an image, and more

Maria Sibylla Merian in Wikidata, rendered with the Reasonator Tool; note the External sources section and BHL’s Creator ID entry.

By adding the BHL Creator ID to this list of identifiers, the Wikidata editor is linking the content held in BHL to the content held in multiple other datasets and repositories.

These extra author data points provide Wikimedians and BHL catalogers with crucial clues that aid in name disambiguation. In particular, hyperlinks to other knowledge bases are incredibly valuable because they lead to new knowledge pathways that help confirm a person’s identity in a complex game of “Who’s Who?”

Workflow Overview

The diagram below illustrates the experimental data pipeline from BHL to Wikidata and back.

Diagram of the 8 steps detailed below of the BHL wikidata round trip.

The BHL to Wikidata Round Trip Overview

The BHL to Wikidata Round Trip Steps

  1. BHL Creator ID and record are created when digital content is harvested into BHL and/or articles are defined in BHL.
  2. Wikimedians record BHL Creator IDs as a statement in corresponding Wikidata items via various community workflows. (See: Mix’n’match deep dive below and/or read about QuickStatements for two ways volunteers are populating Wikidata with BHL’s Creator IDs).
  3. BHL subsequently harvests additional metadata from Wikidata for any author item where a BHL Creator ID statement has been added.
  4. Data outputs are analyzed for quality and breadth.
  5. SPARQL queries and data outputs are iteratively refined to match BHL’s requirements until a quality dataset can be generated for import.
  6. Clean data is imported into the BHL database.
  7. The new author record sidebar displays data on BHL.
  8. PIDs are converted into resolvable URIs, opening up new research pathways for BHL’s users.

Quick note: In Wikidata BHL author records are represented by the Wikidata BHL Creator ID; the presence of this Wikidata property in a Wikidata item provides a powerful connection point that can be used later by BHL to ingest more information about any named entity. A popular author matching tool in Wikidata is Mix’n’match.

Getting BHL Authors in Wikidata with Mix’n’match

Mix’n’match is a Wikidata tool that empowers editors to match Wikidata items to entries in other databases. One of the datasets in Mix’n’match is the BHL Creator ID dataset.

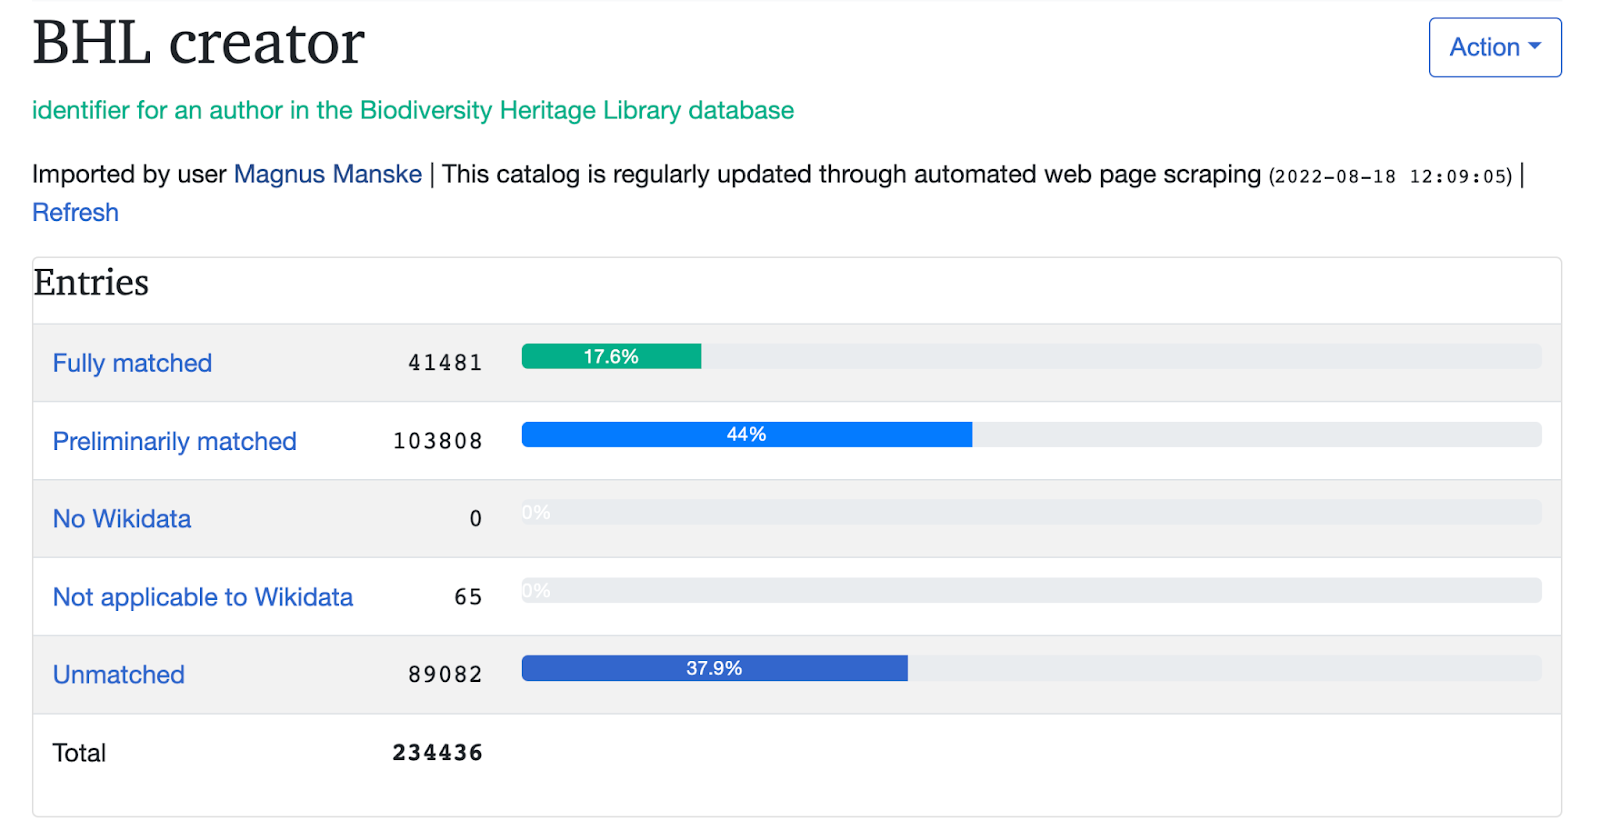
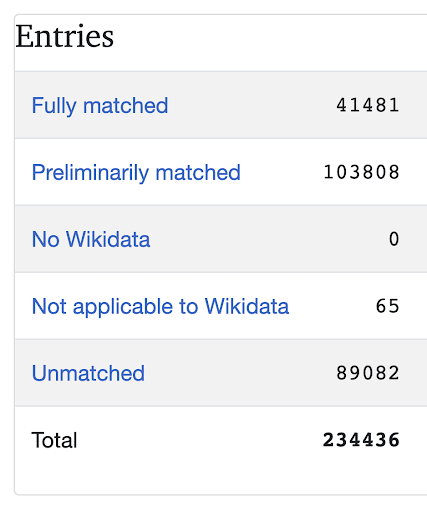
Summary from the mix'n'match tool for the BHL creator ID dataset

A summary of the completeness of matching the BHL Creator ID dataset to Wikidata as of January 2023

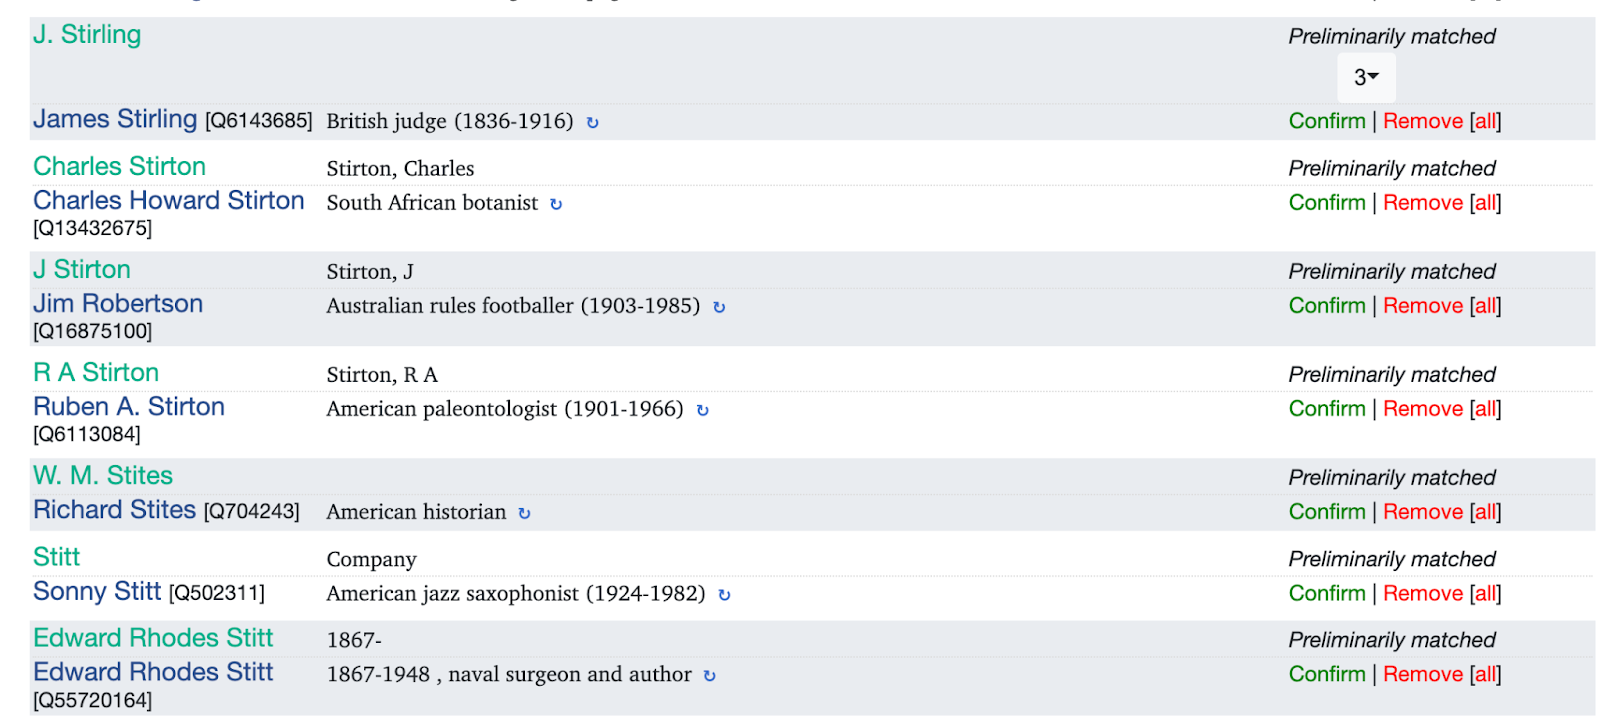
When the BHL Creator ID dataset is uploaded into Mix’n’match, an algorithm undertakes fuzzy name matching. The tool then suggests a preliminary match to a Wikidata item. Wikidata editors working on the dataset have the choice of whether to confirm the suggested match or to remove it.

Sample matches suggested by the mix'n'mtch tool

Examples of possible matches suggested by the Mix’n’match algorithm with the BHL creator in green and the Wikidata item in blue.

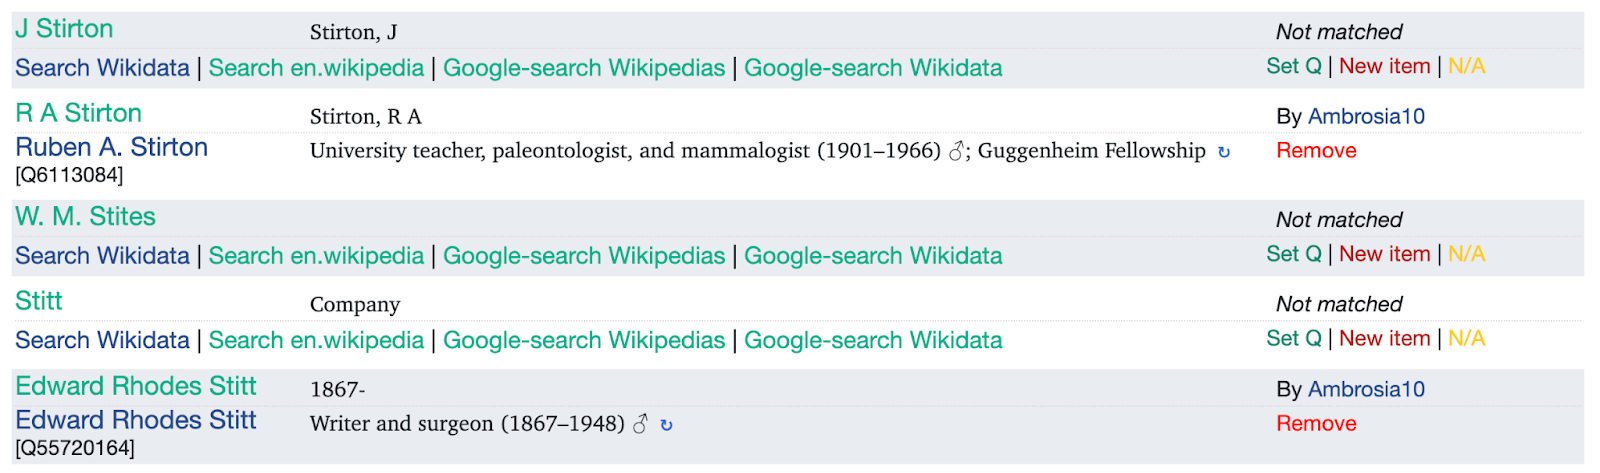
If the Wikidata editor confirms the match, the BHL Creator ID is automatically added to the Wikidata item for the creator. If the editor rejects the match, the editor can add a correct Wikidata item ID, create a new Wikdiata item if the creator is not yet in Wikidata or, in some cases, decide that the BHL Creator ID isn’t applicable to Wikidata. If the editor simply rejects the match without further action, the BHL Creator ID will be added to the unmatched portion of the dataset.

Examples of confirmed and unconfirmed matches in the Mix'n'match tool

Results after the Wikidata editor Ambrosia10 has confirmed or removed the Mix’n’match algorithm suggestions.

The act of linking the BHL Creator ID to the Wikidata item also helps to disambiguate the creator. It removes much of the uncertainty about who the creator is. Names are not unique but by linking identifiers to biographical data, editors can ensure that similarly named people or people whose names have changed over time are all associated with the correct Wikidata item. This addresses the age-old problem of how to assign correct attribution to the right person.

This work also assists BHL. By ensuring BHL Creator ID’s are matched to the Wikidata item, the Wikidata editor can assist BHL in weeding out the duplicate entries for creators in BHL’s database. After matching has taken place, BHL is also able to ingest any of the other identifiers listed on the creator’s Wikidata item, thus enriching the metadata held in BHL’s database.

Currently there are over 230,000 entries in the BHL Creator ID dataset. Of these, just over 41,000 have been matched to Wikidata items. There is a long way to go before this dataset is complete. In the spirit of “many hands make light work,” BHL encourages Wikidata editors to work alongside BHL staff who were recently trained and certified in Wikidata Advanced Concepts by Wiki Education. Our collaborative work will help increase the number of Creator IDs in Wikidata.

Summary from the mix'n'match tool for the BHL creator ID dataset

BHL Creator ID dataset completeness statistics as of January 2023.

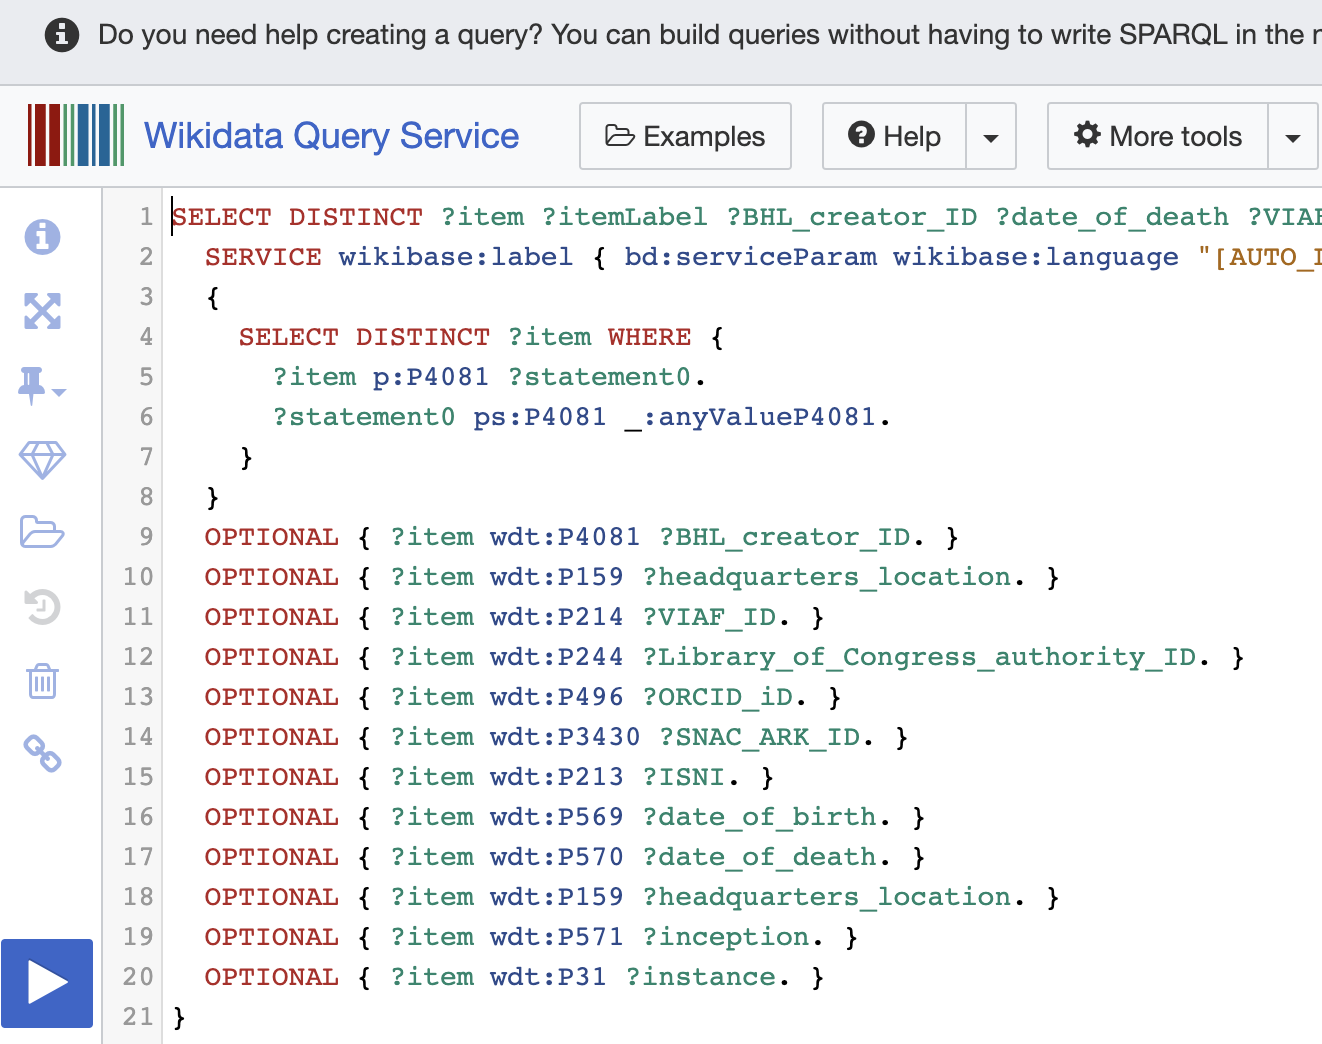
Once BHL Creator ID statements were recorded on Wikidata items, either through manual edits or workflows like Mix’n’match or QuickStatements, then BHL created custom SPARQL queries using the Wikidata Query Service to output data of interest.

Example of a SPARQL query using the wikidata query service

The SPARQL query language is used to query and return data from semantic databases like Wikidata.

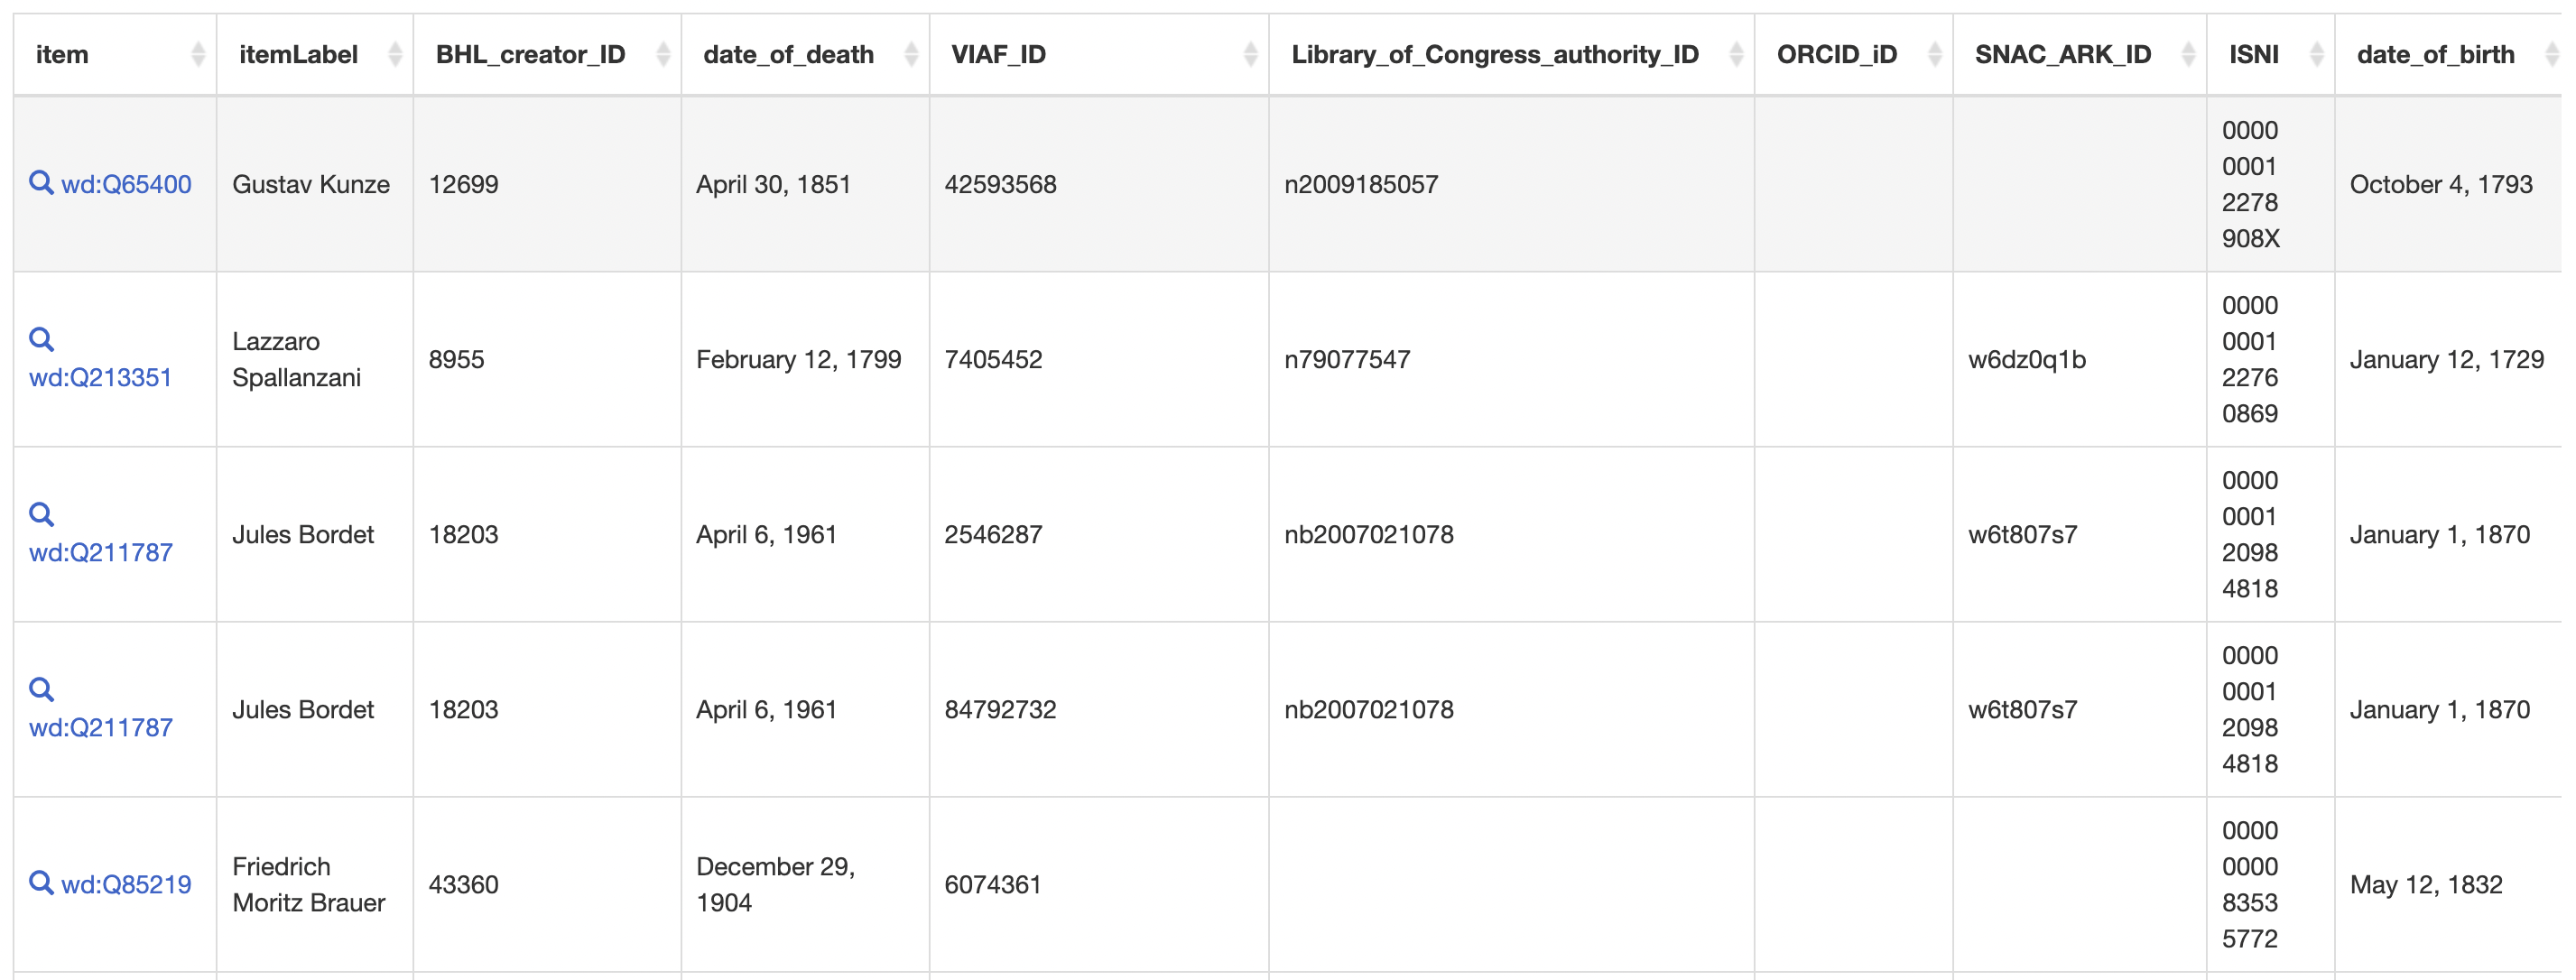
Once the data was brought back, the BHL Cataloging and Metadata Committee discussed and reviewed the records with the aim of bringing key data points back into the BHL database.

Sample data returned from the SPARQL query, including item ID, itemLabel, BHL_creator_ID, date_of_death, VIAF_ID, Library_of_congress_authority_ID, ORCID_ID, ISNI, date_of_birth

Snippet of raw data brought back by the BHL Cataloging and Metadata Committee’s SPARQL query.

In total, the BHL Cataloging and Metadata Committee was able to “round trip” 88,507 persistent identifiers (PIDs) associated with BHL Creator records from the following authoritative knowledge bases:

  • Virtual International Authority File (VIAF)
  • Wikidata
  • Social Networks and Archival Context (SNAC)
  • ResearchGate
  • ORCID
  • Library of Congress Authorities

There are still more PIDs out there to gather but practicality calls for moderation – moderation of the quantity that the Wikidata Query Service can bring back and the amount feasible to curate in BHL. After many discussions, the above list was chosen by narrowing down the PIDs that seem most appropriate in the BHL context. A comprehensive policy on Uniform Resource Identifiers (URIs) in the BHL ecosystem is now being drafted by BHL committees.

Additionally, in post-work analysis, the Committee did find that the data modeling of corporate names in Wikidata differs from the library world, and pulling in identifiers for corporate names was not worth the effort (at least at this time).

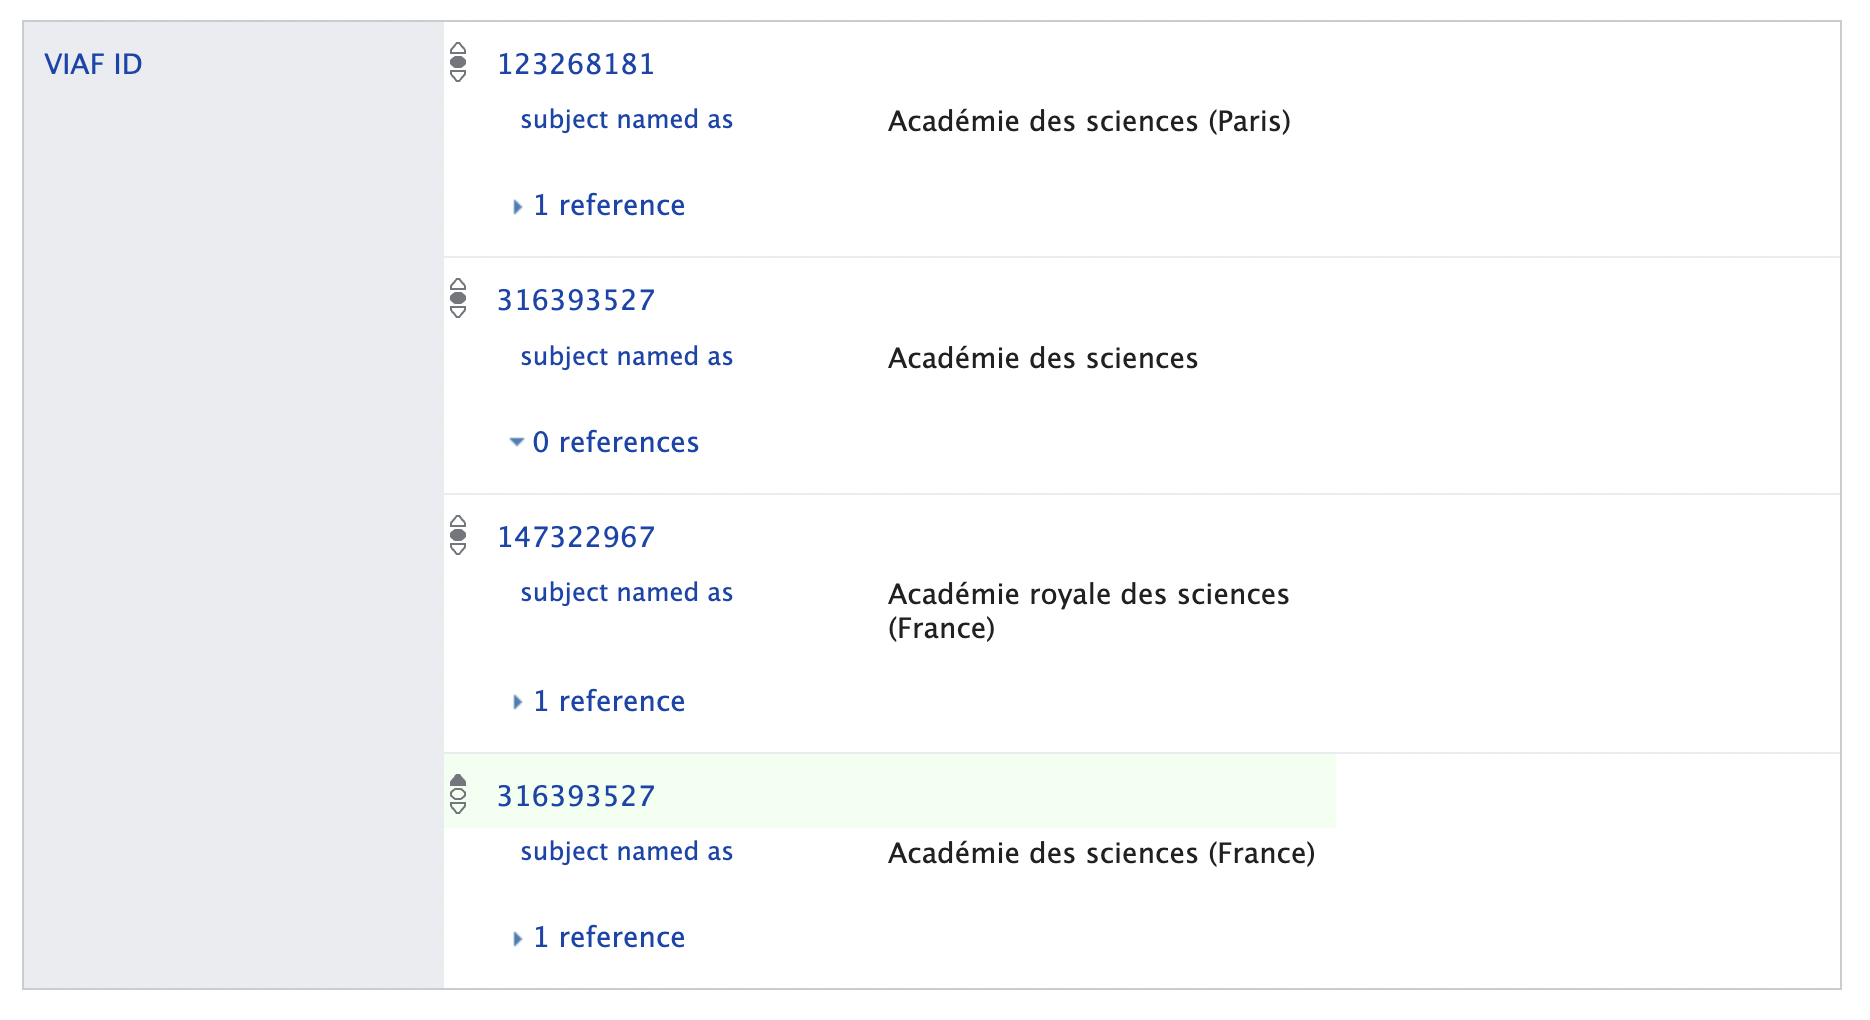
Below is an example of Académie des sciences (France), which receives multiple item records in library databases like VIAF for each name change. However, in Wikidata these name changes are collapsed and will appear on one item record; this divergence means that one-to-one matches are not possible without a lot of manual clean-up from BHL Staff.

Example of the Wikidata entry for VIAF ID for Académie des sciences

Divergent data models: Wikidata corporate names collapse name changes.

It’s important to note that data modeling in Wikidata is in its nascent stages and librarians should have a vested interest in shaping the best practices of the community so all of humanity can model the world’s knowledge together. As we have seen with this one-time experiment, there is little to lose, and so much to gain!

The Result: A New Author Record Sidebar for BHL

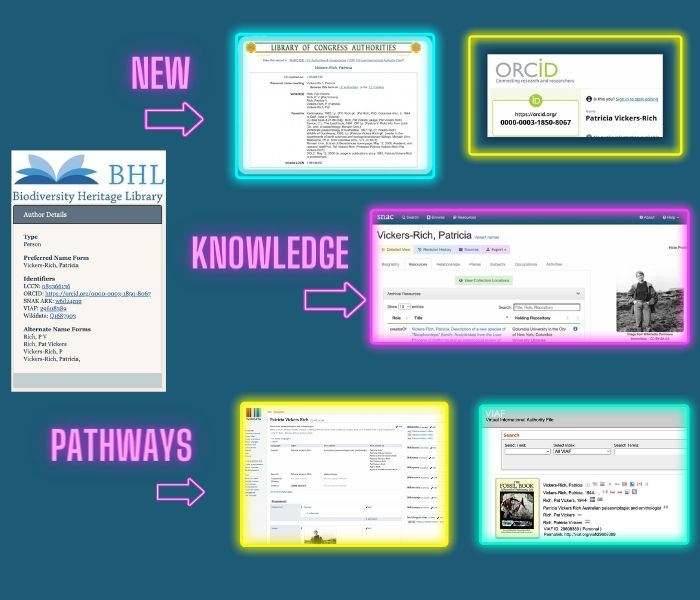
Thanks to the feedback from the Wikimedia community, BHL’s Lead Developer created an Author Record sidebar. Click on any BHL author name on the BHL website and the author details will appear on the right-hand side. Below is an example of Australian paleontologist and ornithologist, Patricia Vickers-Rich in BHL. 

Graphic example of an author record with detailed sidebar and the pages to which it links out, such as ORCID, Library of Congress Authorities, Wikidata, SNAC

A New Wikimedian Driven Feature: The BHL Author Record Sidebar!

The goal of this new feature was to expose existing and recently harvested identifiers as resolvable links that could open up critical knowledge pathways for BHL’s users on their information journeys. Other key data points are provided such as preferred name forms, entity type, and alternative name forms that give additional context for disambiguation research.

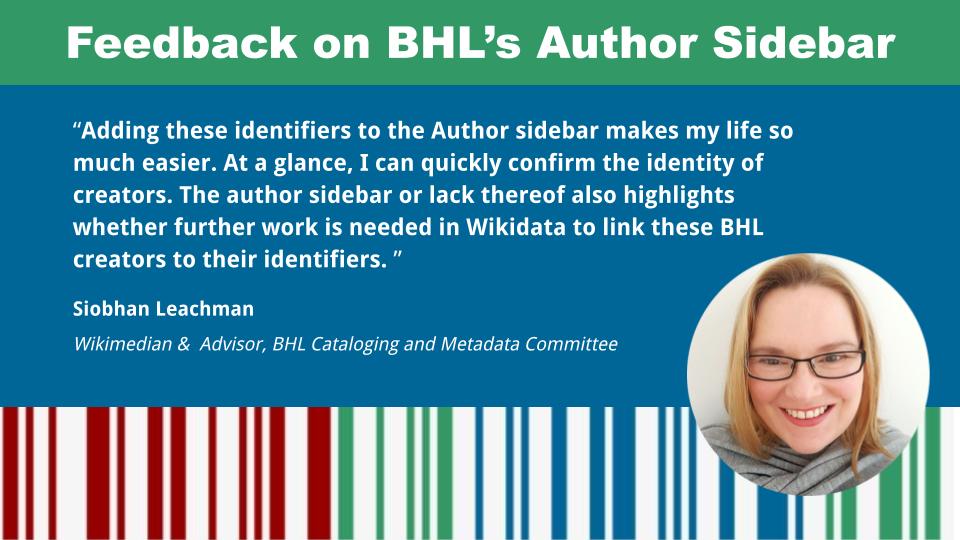
A quote from Siobhan Leachman on BHL's new author sidebar: Adding these identifiers to the author sidebar makes my life so much easier. At a glance, I can quickly confirm the identify of creators. The author sidebar or lack thereof also highlights whether further work is needed in wikidata to link these BHL creators to their identifiers."

Next Steps for BHL Committees?

Please let us know in the comments what you think of this experiment. Should BHL pursue similar persistent identifier harvests for other entity types? Or perhaps, a recurring harvest for BHL Authors?

Additional BHL entities:

  • Titles
  • Scientific Names
  • Subjects
  • Media (illustrations, scientific plates, photos)

Let us know! Your feedback is crucial to BHL’s evolution as a biodiversity knowledge base.

If you are new to Wikidata, Mix’n’match is a great place to start. There are many tutorials and resources available on the web including this great YouTube introduction on how to use the tool.

Additionally, a workflow for BHL articles has been piloted and is currently underway thanks to BHL’s Persistent Identifier Working Group. For more details on how to roundtrip BHL Article Q identifiers, please refer to the group’s documentation at: Wikidata:WikiProject_BHL/Projects

BHL committees and working groups are actively scoping many projects. Sign-up here to get involved!

Related Posts

For more information on the assignment of DOIs, a very important type of persistent identifier specific to scholarly publications, check out Nicole Kearney’s blog post What Is BHL’s New Persistent Identifier Working Group DOI’ng?

For a list of all of the new features and data quality improvements BHL made in 2022, check out the post BHL Technical Development: Year in Review

February 15, 2023by mdimeo
BHL News, Blog Reel, Tech Updates

Providing More Robust Data in BHL’s OAI-PMH Dublin Core Feed

Overview of Live Data from BHL

Recently, BHL performed a comprehensive review of all live data feeds and outputs to ensure that we are providing robust metadata to our downstream consumers. Live BHL data can be found at BHL’s Developer and Data Tools. BHL’s live data outputs include:

  • API v3
  • OAI-PMH

OAI-PMH is an acronym for the Open Archives Initiative Protocol for Metadata Harvesting. It allows other discovery services and aggregators to harvest BHL’s metadata in standard formats such as Metadata Object Description Schema (MODS) and Dublin Core (DC).

The OAI-PMH protocol only requires metadata to be expressed in the unqualified Dublin Core (DC) format. However, it also can be extended to express the metadata in other formats. Because unqualified DC is constrained to just 15 core elements, it is not uncommon for OAI-PMH repositories to also provide metadata in a more robust format. BHL provides MODS in addition to DC. Consumers of the BHL OAI-PMH feed are encouraged to use the MODS-formatted data instead of Dublin Core because it provides additional data elements that aid in user discovery.

It’s important to note that BHL provides five sets of metadata via OAI-PMH:

  1. Item = This set contains individual volumes hosted by BHL. The content is viewable in BHL.
  2. Title = This set contains metadata about the monographs and journals represented in BHL.
  3. Part = This set contains articles/chapters/treatments/etc. hosted by BHL. The content is viewable in BHL.
  4. Item External = This set contains individual volumes not hosted by BHL. The content must be viewed on a site not maintained by BHL.
  5. Part External = This set contains articles/chapters/treatments/etc. not hosted by BHL. The content must be viewed on a site not maintained by BHL.

Improving BHL’s OAI-PMH Dublin Core Feed

To provide more robust data in BHL’s OAI-PMH Dublin Core feed, three changes have been made to the feed:

  1. Creative Commons (CC) license information was added as a second <rights> element;
  2. A <relation> element was added to titles that are part of a monographic series, allowing BHL to model more complex bibliographic relationships that exist in the BHL database; and
  3. A non-standard “type” attribute was removed from the <relation> element for parts.

Important: If you are a developer, using the non-standard “type” attribute in your code at the part-level, this is a breaking change. Please take note and update your code accordingly.

Below is an example output of a monographic series using the <relation> element at the title-level:

<OAI-PMH xmlns="http://www.openarchives.org/OAI/2.0/" xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance" xsi:schemaLocation="http://www.openarchives.org/OAI/2.0/ http://www.openarchives.org/OAI/2.0/OAI-PMH.xsd">
<responseDate>2023-01-31T13:45:05Z</responseDate>
<request verb="GetRecord" metadataPrefix="oai_dc" identifier="oai:biodiversitylibrary.org:title/965"> https://www.biodiversitylibrary.org/oai </request>
<GetRecord>
<record>
<header>
<identifier>oai:biodiversitylibrary.org:title/965</identifier>
<datestamp>2008-01-02T11:47:12Z</datestamp>
<setSpec>title</setSpec>
</header>
<metadata>
<oai_dc:dc xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance" xmlns:oai_dc="http://www.openarchives.org/OAI/2.0/oai_dc/" xmlns:dc="http://purl.org/dc/elements/1.1/" xsi:schemaLocation="http://www.openarchives.org/OAI/2.0/oai_dc/ http://www.openarchives.org/OAI/2.0/oai_dc.xsd">
<dc:title>Adephagous and clavicorn Coleoptera from the Tertiary deposits at Florissant, Colorado, with descriptions of a few other forms and a systematic list of the nonrhynchophorous Tertiary Coleoptera of North America</dc:title>
<dc:creator>Scudder, Samuel Hubbard, 1837-1911</dc:creator>
<dc:subject>Beetles, Fossil</dc:subject>
<dc:subject>Paleontology</dc:subject>
<dc:subject>Tertiary</dc:subject>
<dc:publisher>Washington, Govt. print. off, 1900</dc:publisher>
<dc:contributor>Smithsonian Libraries</dc:contributor>
<dc:date>1900</dc:date>
<dc:type>Book</dc:type>
<dc:type>text</dc:type>
<dc:identifier>https://www.biodiversitylibrary.org/bibliography/965</dc:identifier>
<dc:identifier>info:doi/10.5962/bhl.title.965</dc:identifier>
<dc:language>English</dc:language>
<dc:relation>https://www.biodiversitylibrary.org/bibliography/42496</dc:relation>
</oai_dc:dc>
</metadata>
</record>
</GetRecord>
</OAI-PMH>

Data harvesters currently consuming BHL’s OAI-PMH feeds, please update your code accordingly. Also, feel free to leave a comment for the BHL Technical Team with any feedback regarding any of our live data outputs. Thank you and happy harvesting!

Related Links

  • Open Archives Initiative Protocol for Metadata Harvesting
  • Metadata Object Description Schema (MODS)
  • Dublin Core
  • Developer and Data Tools – BHL
February 3, 2023by mdimeo
BHL News, Blog Reel, Tech Updates

BHL Technical Development: Year in Review

Technical development: year in review. Critical updates. New features and enhancements. Data quality improvements.

Critical Upgrades

For BHL, 2022 was a year to focus on critical upgrades for the BHL platform to ensure the sustainability of our services for our global users. Although BHL’s basic technical infrastructure remains the same, consisting of years of refinement, knowledge, and reliability, a few updates were definitely in order. BHL major upgrades included:

  • Upgraded .NET Framework to version 6 (see What’s New in Version 6? for a rundown of the benefits for BHL)
  • Upgraded Elasticsearch from 5.4.2 to v.7.17 (search functions remain the same)
  • Converted SOAP services to REST (two SOAP services used by the BHL website and utility applications have been converted to REST services implemented in .NET 6)
  • Upgraded Global Names GNFinder tool from 0.19.5 to 1.0.0

Most of these upgrades were “behind-the-scenes” work and would not be noticeable to a majority of our users. However, keeping up with these important enhancements is a crucial component of any technology project. To learn more about the technology stack that drives BHL, click on the above links for a deep dive into some of the products and services we utilize to make BHL a reality.

New Features and Enhancements

In 2022, BHL deployed three new exciting user-driven features on the BHL website: the BHL text source indicator, the author record sidebar, and pre-generated article PDFs.

Text Source Indicator

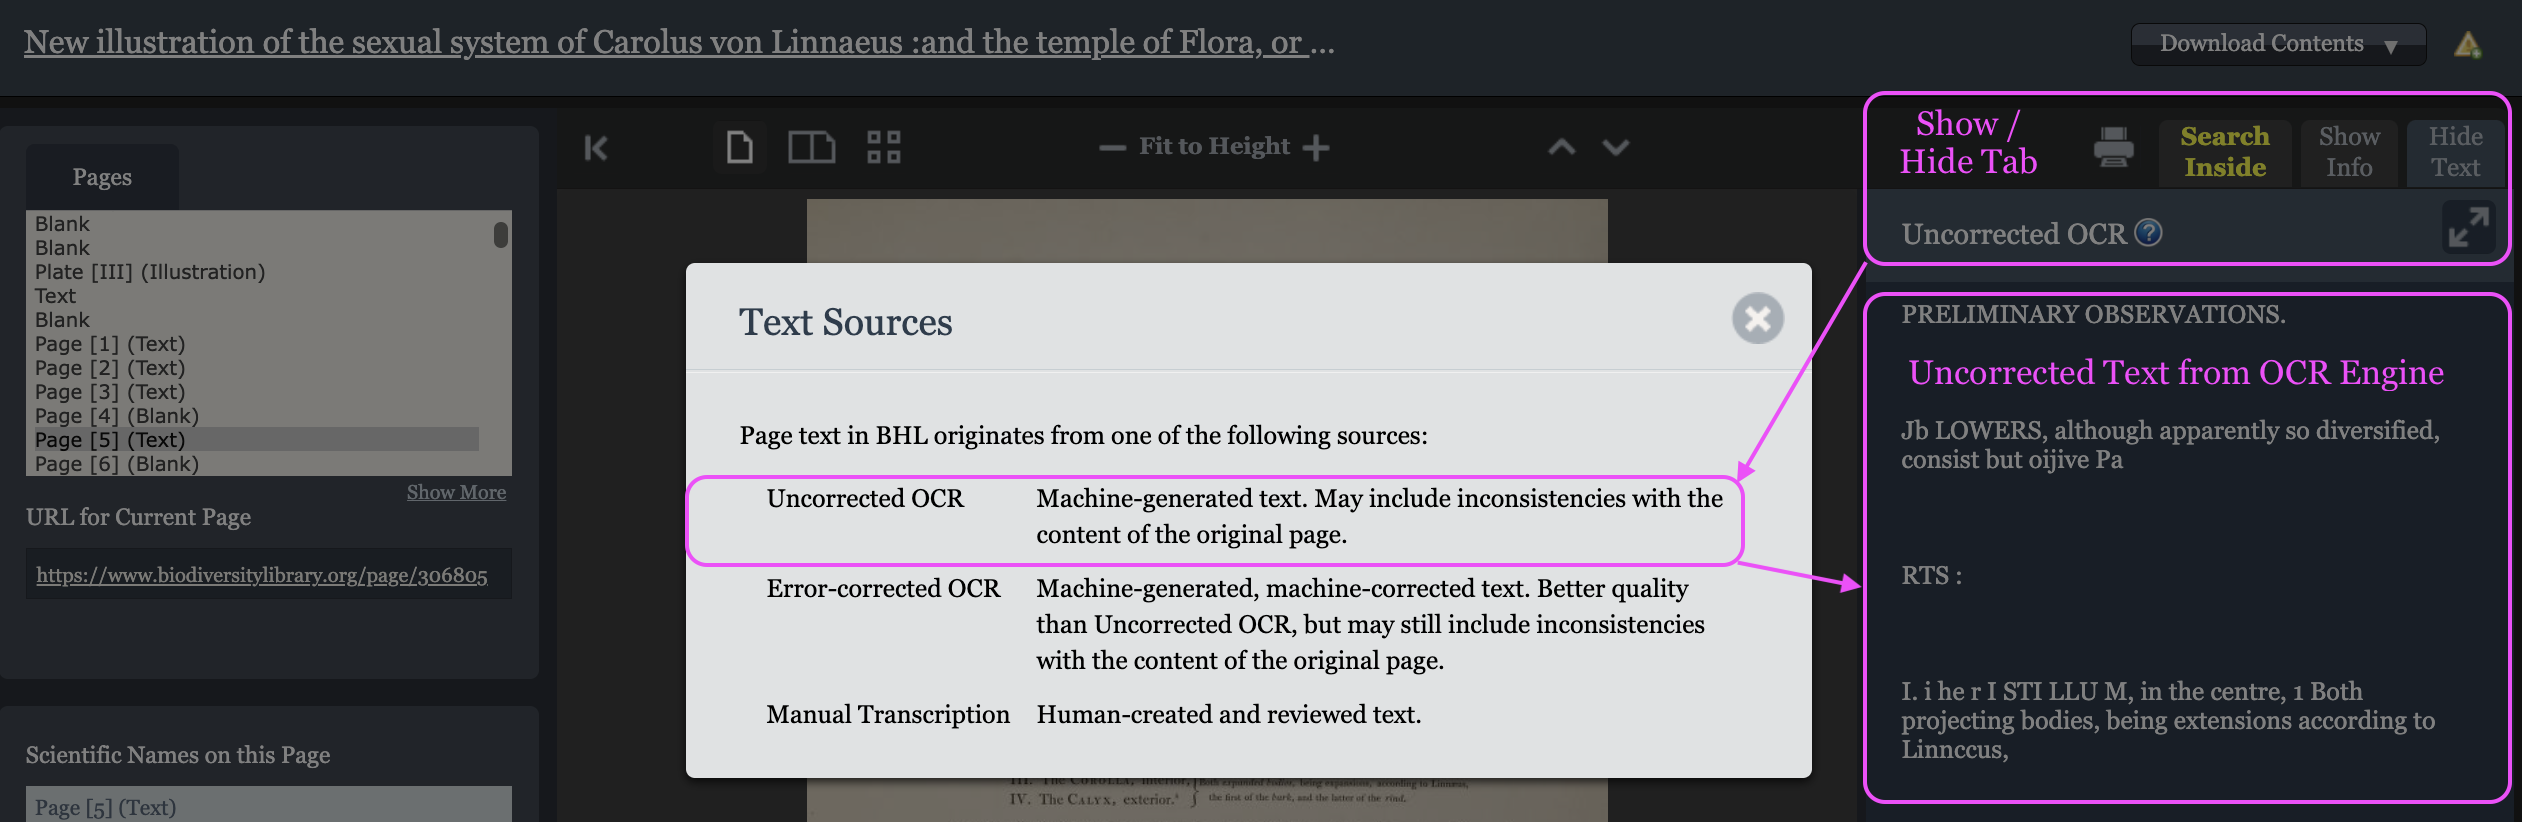
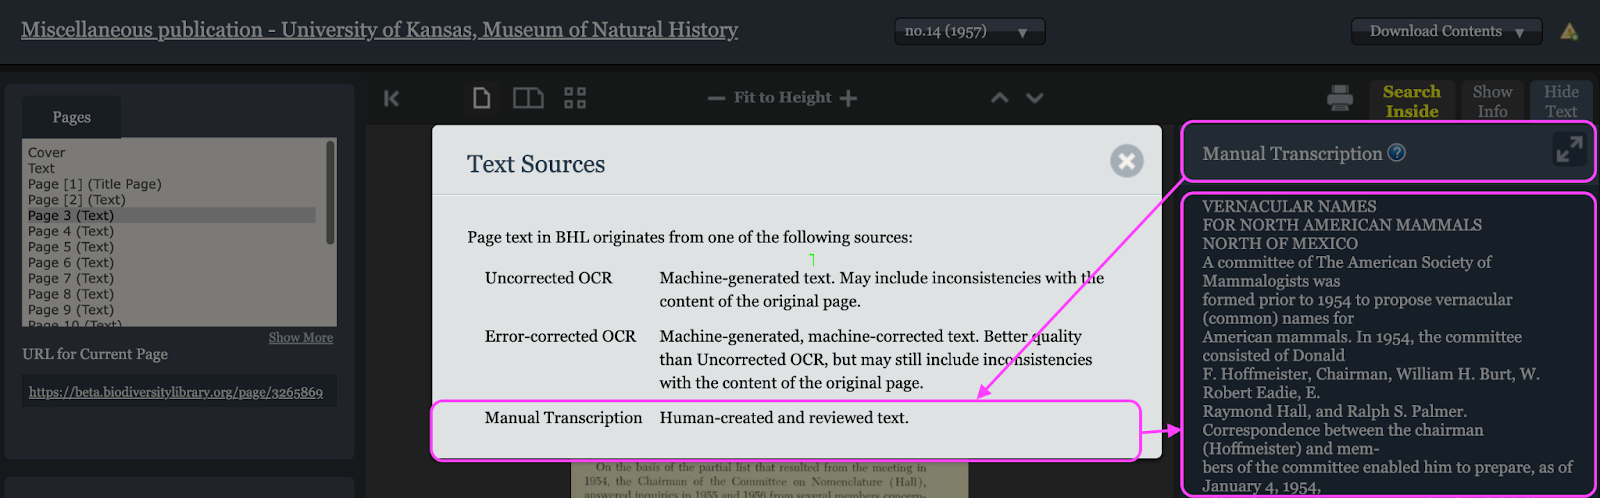
Many of our users would like to know where BHL’s text output comes from. The Show Text tab now gives BHL users more information about whether the content has been manually transcribed by a human versus automatically generated by a machine via an OCR engine like Tesseract or ABBYY FineReader.
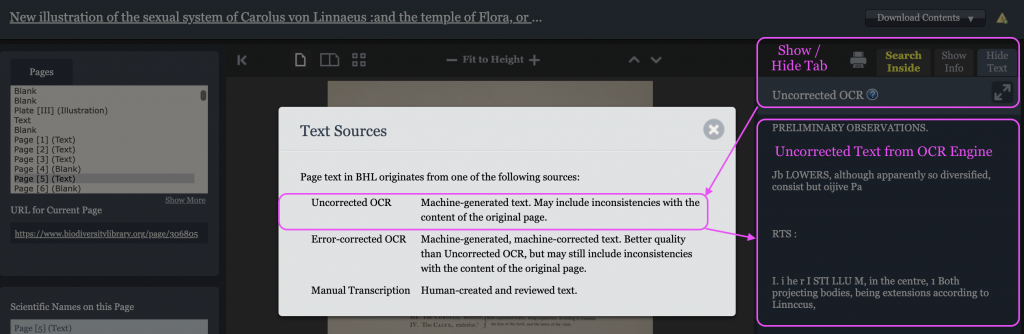
Screenshot of the BHL bookviewer with sample text highlighting the new text source indicator with uncorrected OCR

An example of uncorrected text from an OCR engine with lower quality text output

The Text Source Indicator helps our users understand and determine what quality they should be expecting from the item they are viewing.
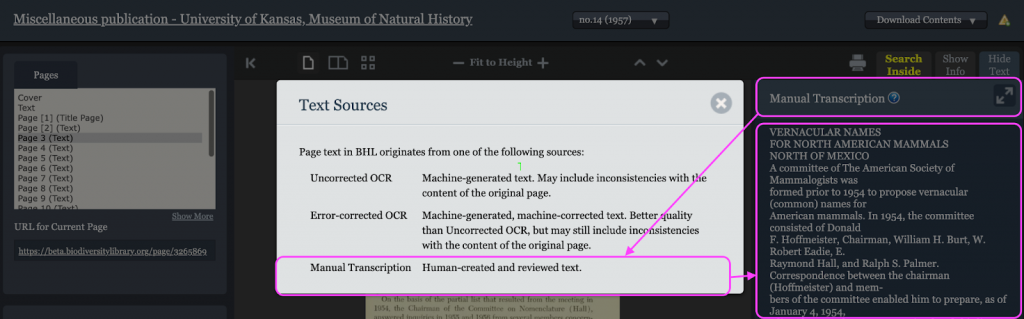
Screenshot of the BHL bookviewer with text source indicator showing manual transcription

An example of manually transcribed text with higher quality text output

Many thanks to the BHL Transcription Upload Tool Working Group (TUTWG) for this important feature request and providing the critical feedback to ensure the Text Source Indicator is useful to BHL’s global user base.

Author Record Sidebar

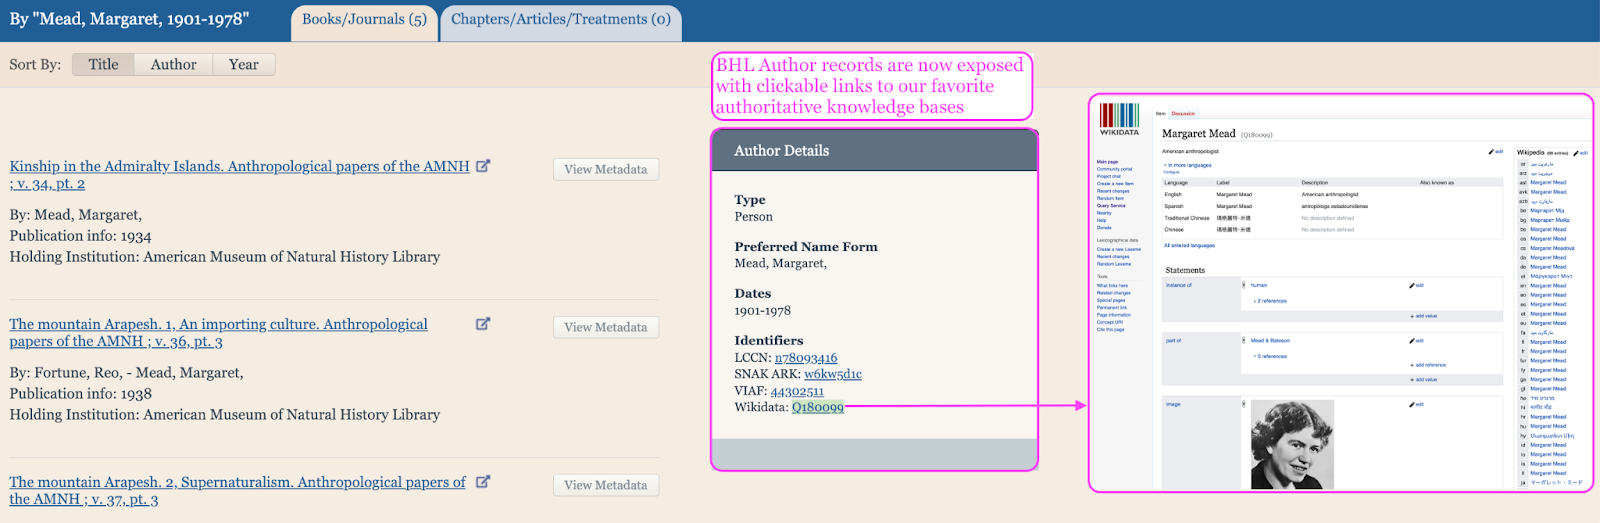
BHL is now exposing author data to help open-up new research pathways beyond the BHL portal. The Author Record sidebar was born out of a response to user requests from two Wikimedians, Siobhan Leachman and Andy Mabbett, who provided critical feedback that they would like to see Wikidata Q numbers exposed alongside author names to further facilitate downstream name disambiguation work.
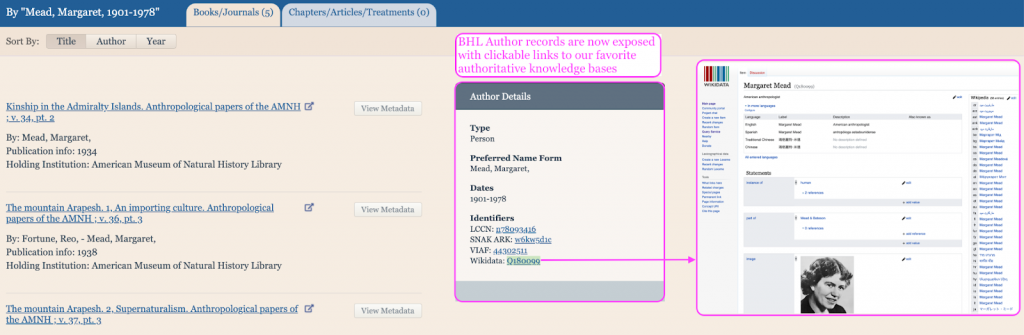
Screenshot of author search results showing new author details and links to authoritative knowledge bases such as wikidata

Author data stored in BHL is now displayed with author search results. Data includes clickable URIs to authoritative name registries including Wikidata.

A special thanks to Siobhan, Andy, and the BHL Cataloging and Metadata Committee for their hard work and dedication to curating and disambiguating author names and helping to realize the new author records display in BHL. Look out for a forthcoming blog post from the Committee, during International Love Data Week 2023, which will detail how the group was able to harvest 88,000+ author identifiers from Wikidata and bring them back into BHL’s database.

Pre-generated Article PDFs

In 2022, the BHL Technical Team announced pre-generated PDFs for articles defined in BHL. While BHL had previously allowed users to download custom PDFs, the benefits of pre-generated article PDFs are manifold:

  • No waiting.
  • No selecting pages.
  • The PDF contains embedded, searchable, copy-paste-able text.
  • The PDF contains rich XMP-based metadata about the article.

The addition of these pre-generated PDFs article landing pages in BHL also allows content aggregators like Unpaywall to find BHL’s open access versions of paywalled literature and serve BHL content up to their user base via their free browser extension.
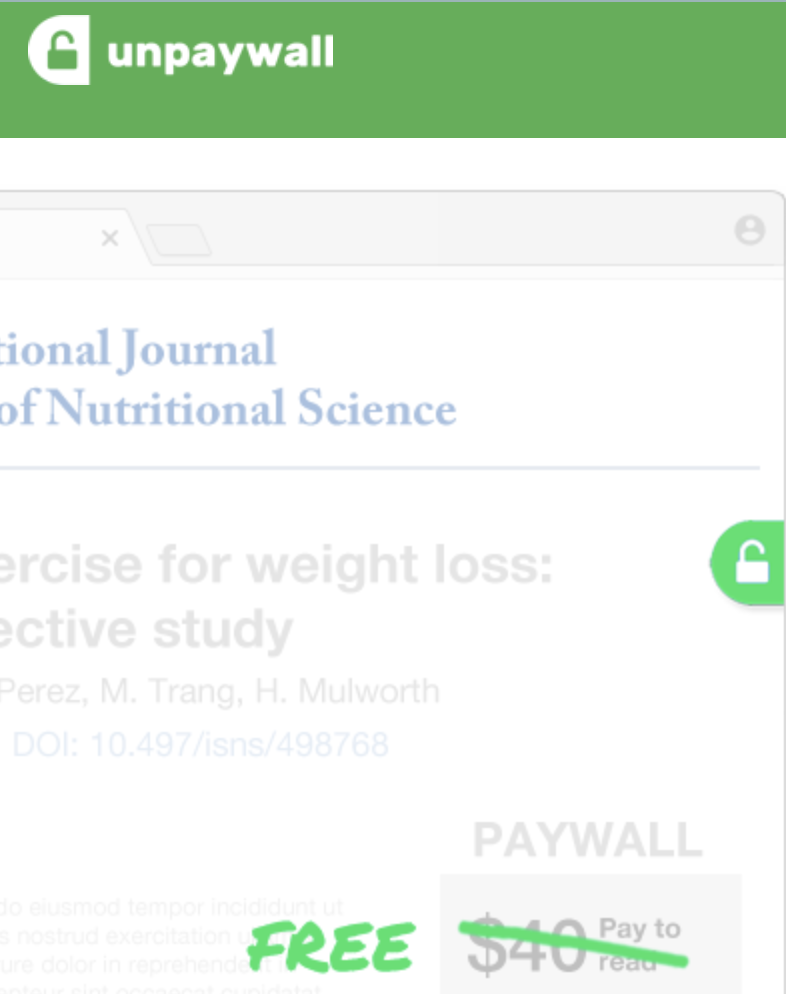
Unpaywall browser extension indicating an article is available for free elsewhere on the web

BHL’s article PDFs are now surfaced via the Unpaywall browser extension.

Many thanks to BHL’s Persistent Identifier Working Group (PIWG) and their ongoing communications with the Unpaywall Development Team to ensure BHL content is surfaced via the Unpaywall browser extension.

Data Quality Improvements

The BHL Technical Team and all of BHL’s Committees and Working Groups care passionately about the quality of BHL’s data. To support the various priorities around data management in BHL’s Strategic Plan, BHL announced the new position of BHL Data Manager in 2022. In this new role, the Data Manager leads the effort to develop and implement a comprehensive view of how BHL collections can be optimized to support the interoperability of BHL data in the larger biodiversity community.

Like any big data repository there are anomalies, errors, and omissions in BHL data as a result of aggregating records from hundreds of contributors and technology projects distributed all over the world. The way we collectively categorize, classify, and describe our materials can vary vastly across so many collaborating organizations that comprise the BHL network. In 2022, the data quality improvements of note included reprocessing BHL’s OCR files, updating the material type facet, and creating an open data collection with a new 40GB OCR text export.

Reprocessing BHL’s OCR files

BHL digitization partner, the Internet Archive (IA), has upgraded their OCR engine from ABBYY FineReader to the Tesseract Open Source OCR engine. BHL is working with IA to reprocess some of BHL’s oldest content with the newest available version of Tesseract OCR. Approximately 120,000 BHL items are eligible to be upgraded and at our current rate of progress of approximately 100 items per day, it will take close to two years to complete the BHL OCR reprocessing project. For more information check out OCR Improvements: An Early Analysis by BHL’s Technical Coordinator, Joel Richard.

Material Type Facet Update

Archival materials digitized for BHL are not like books and journals. The content is non-standard and thus often presents additional challenges for BHL staff. Prior to sending materials for digitization, archival materials must be intellectually organized, cataloged, and frequently undergo extensive preservation treatment. In doing this work, BHL’s catalogers and archivists collaborate to answer some very complex questions:

  • Are these materials considered published or unpublished? 
  • Are they in-copyright or out-of-copyright? 
  • How should these materials be divided and what should comprise an intellectual unit? 

The answers to the above truly vary and depend on the expertise, local digitization workflows, and the technological constraints of an organization. The sheer diversity of cataloging and digitization methods across the BHL partner network is truly astonishing, but it does not always result in precise search and retrieval for our users.
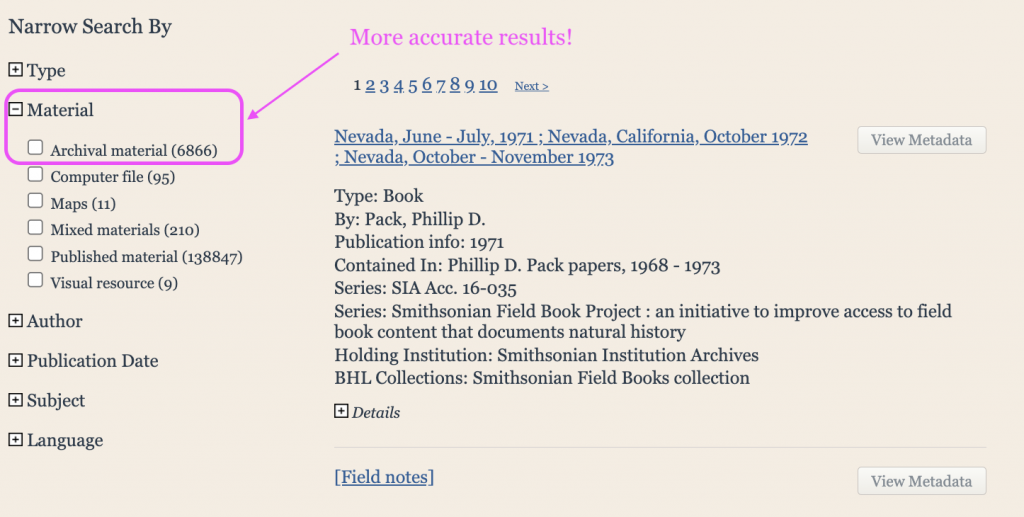
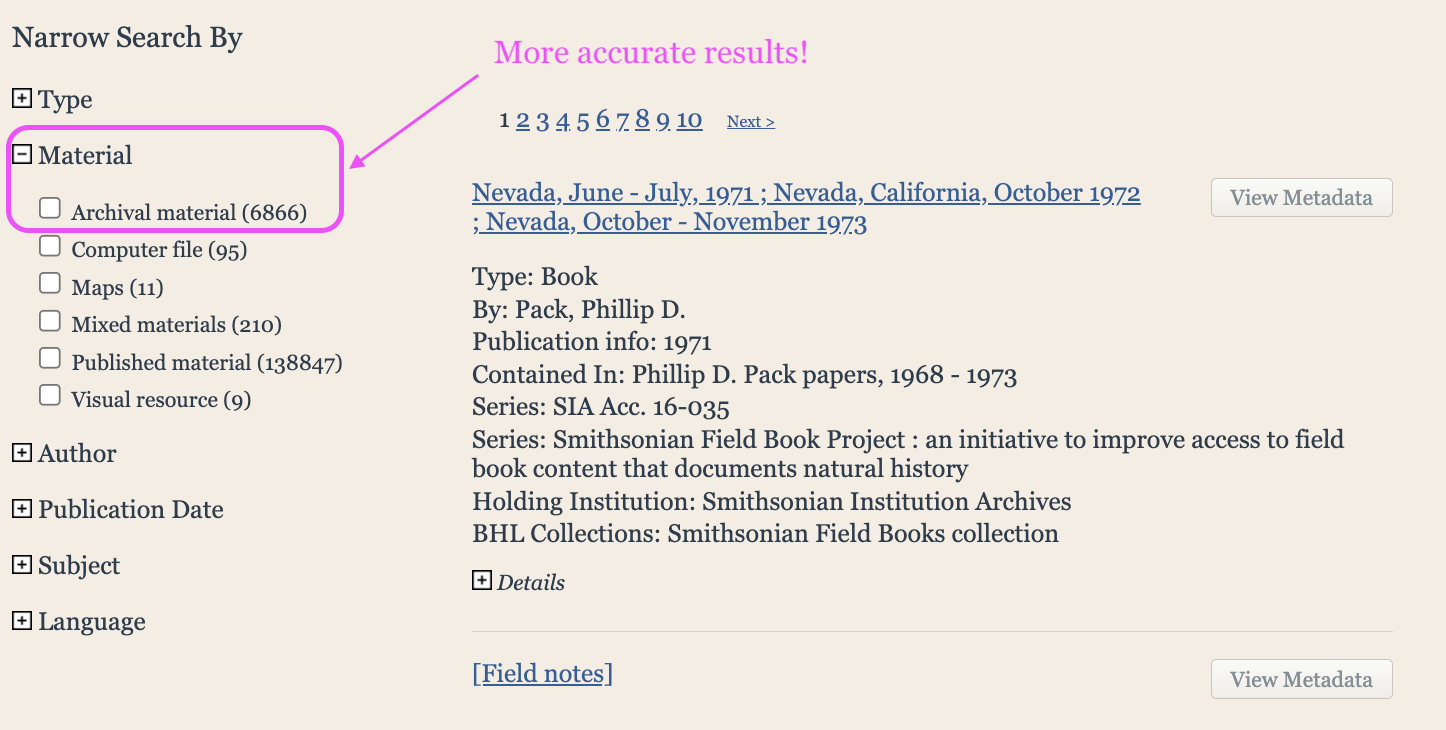
Example of search results demonstrating over 6,800 archival materials available

The Material facet allows users to filter on different categories of content. This data update ensures that the Archival Material facet brings in a more complete set of search results.

To facilitate better search precision, BHL has decided to update all archival materials to be classified as “Manuscript language material (Archival material)” which has resulted in 4,637 records being updated in the BHL database. For our users, who rely on search facets to drill down on relevant content, this ultimately means more relevant results, more archival content, and more happy BHL users! Many thanks to BHL’s Transcription Upload Tool Working Group (TUTWG) for their work and group analysis to make this major data update a reality.

Open Data Collection with new 40GB OCR Text Export

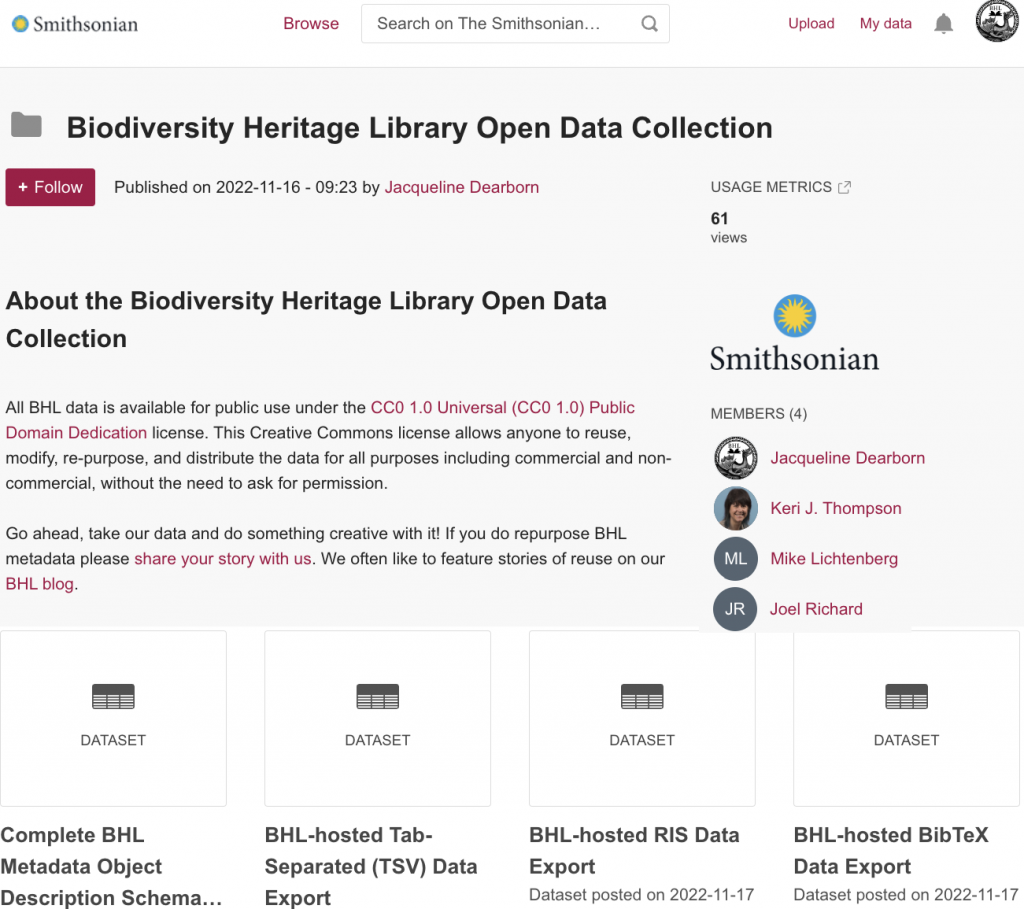
In the Fall of 2022, the BHL Technical Team worked with Keri Thompson, Data Management Specialist from Smithsonian’s OCIO’s Research Computing Office, to publish BHL data exports as FAIR data. BHL’s data has always been available for download on our Developer and Data Tools page but as an open access leader, BHL has decided to revamp each data export to include a DOI, a data dictionary, and multitude of citation formats. Most importantly, the data is now hosted on the Smithsonian Institution’s Figshare instance which serves as a “an open platform for hosting and sharing the raw material of Smithsonian research.” BHL’s data has also been cataloged using the W3C data description standard: Data Catalog Vocabulary (DCAT). In using DCAT, BHL data is now compliant and could be harvested by federally mandated data repositories like Data.gov.

A sample of data sets available from the BHL Open Data Collection on figshare

Access BHL Open Data Collection on Smithsonian Institution’s Data Repository

Lastly, a very exciting data export has been added to the BHL Open Data Collection. Data miners everywhere, this one’s for you:

BHL Optical Character Recognition (OCR) – Full Text Export (https://doi.org/10.25573/data.21422193.v4)

The BHL OCR full text export is our largest data export, representing the full textual corpus for all items in BHL. It is so large that we really struggled to find a place to host the file. The file is updated on a monthly basis and posted to the link above.

BHL Technical Team Goes Agile

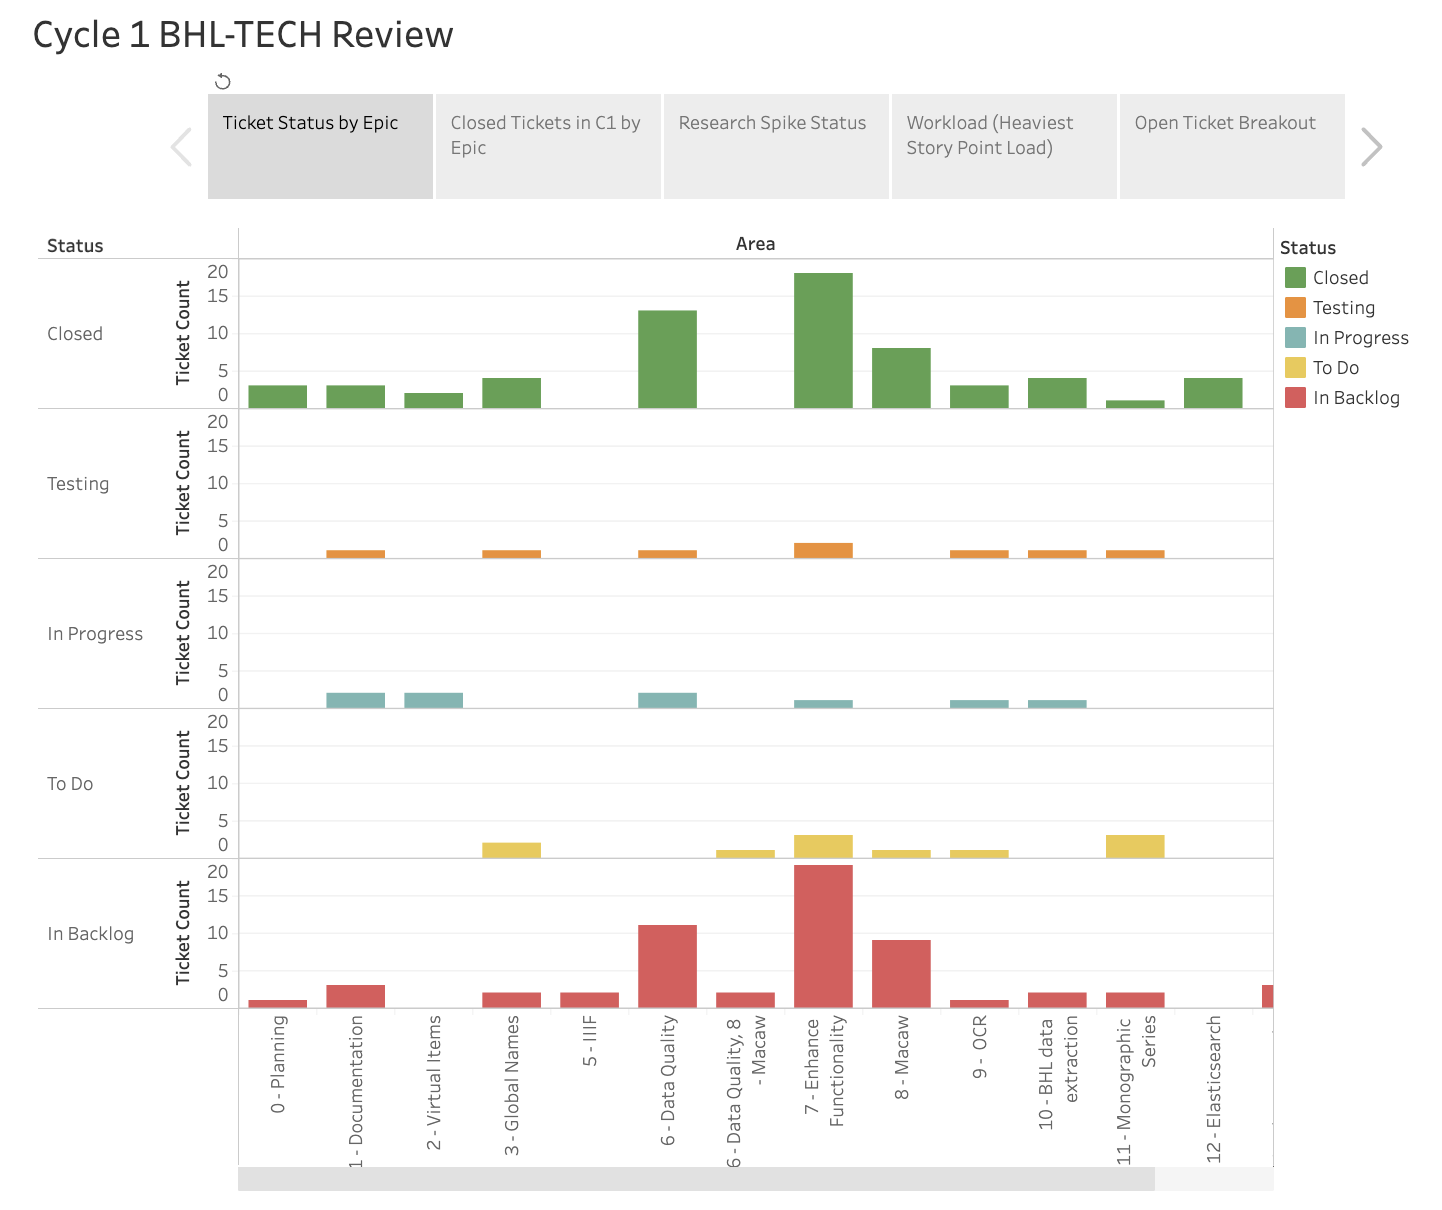
The BHL Technical Team had a transformational year. Not only did the Team complete critical upgrades, deliver exciting new features for BHL’s users, and improve overall data quality; we also adopted the popular Agile project management methodology and SCRUM framework. Agile is used by 3 out of every 4 technology projects to improve team communications, find new efficiencies, adapt to change, and maximize resources.
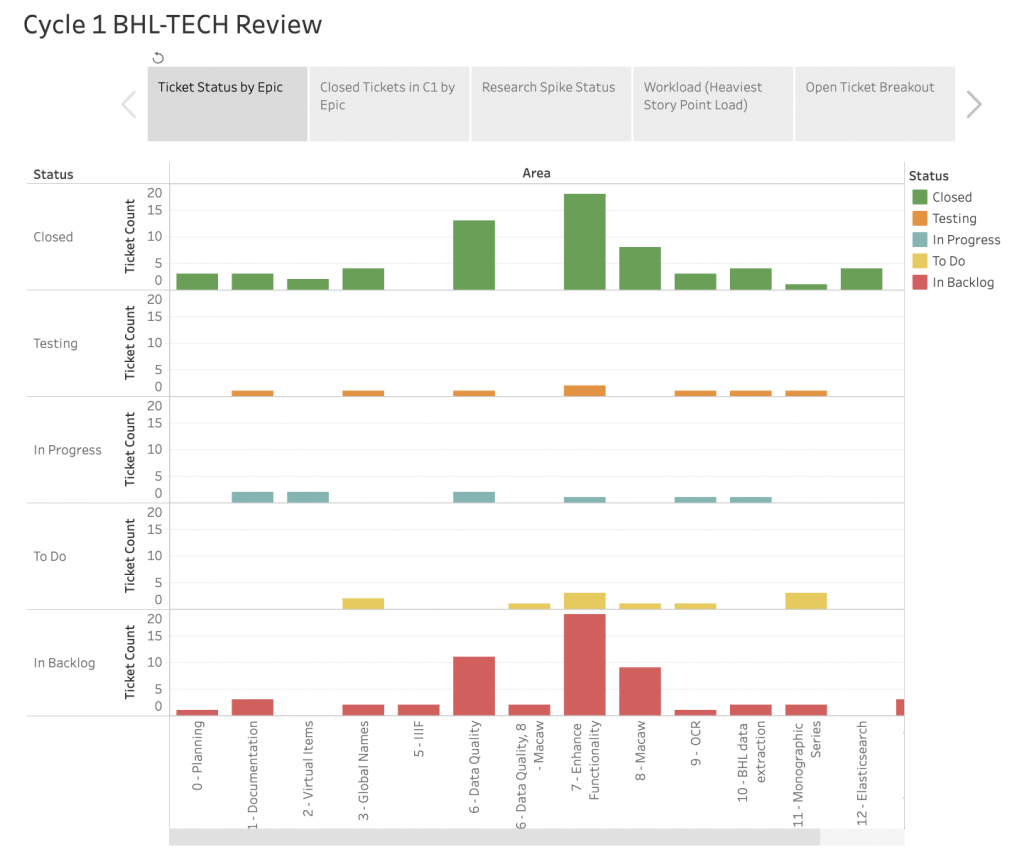
Bar graphs representing the status of tickets across 12 work areas

Agile Dashboard, reporting on the status of BHL Technical Epics. Click here for an interactive deep dive into our work.

We are still refining new workflows but overall, the “BHL Agile experiment” has been a boon for BHL technical development. Our Team now has a birds-eye view of all of the work in the pipeline. Knowing where we’ve been, where we are going, and focusing on continuous iterative improvement has helped us deliver more meaningful value to BHL Partners and users while furthering our collective mission of making biodiversity literature openly available to the world.

Kudos to the entire BHL Technical Team and Secretariat for a productive 2022!

A special thanks to BHL’s Lead Developer, Mike Lichtenberg, and Technical Coordinator, Joel Richard, for all of your hard work, knowledge, and dedication to the BHL platform, data, and our users. BHL is so incredibly lucky to benefit from your many talents!

For a sneak peak of what is in store for the year ahead, check out the 2023 BHL Technical Priorities.
January 31, 2023by mdimeo
Page 2 of 2«12

Help Support BHL

BHL's existence depends on the financial support of its patrons. Help us keep this free resource alive!

search

About BHL

The Biodiversity Heritage Library (BHL) is the world’s largest open access digital library for biodiversity literature and archives. BHL operates as a worldwide consortium of natural history, botanical, research, and national libraries working together to digitize the natural history literature held in their collections and make it freely available for open access as part of a global “biodiversity community.”

Join Our Mailing List

Sign up to receive the latest news, content highlights, and promotions.

Subscribe Now

Subscribe to Blog via Email

Enter your email address to subscribe to this blog and receive notifications of new posts by email.

Join 319 other subscribers

Subscribe to Blog Via RSS

Subscribe to the blog RSS feed to stay up-to-date on all the latest BHL posts.

Access RSS Feed

Inspiring Discovery through Free Access to Biodiversity Knowledge.

The Biodiversity Heritage Library makes it easier than ever for you to access the information you need to study and explore life on Earth…for free, anytime, anywhere.


64+ Million Pages of
Biodiversity Literature Online.

EXPLORE

Tools and Services
to Transform Research.

EXPLORE

300,000+
Illustrations on Flickr.

EXPLORE

ABOUT | HARMFUL CONTENT | PRIVACY | SITE MAP | TERMS OF USE