Biodiversity Heritage Library - Program news and collection highlights from BHL
  • Home
  • News
  • Featured Books
    • All Featured Books
    • Book of the Month Series
    • BHL at 20
  • User Stories
  • Campaigns
    • Fossil Stories
    • Garden Stories
    • Monsters Are Real
    • Page Frights
    • Her Natural History
    • Earth Optimism 2020
  • Tech Blog
  • Visit BHL
Home
News
Featured Books
    All Featured Books
    Book of the Month Series
    BHL at 20
User Stories
Campaigns
    Fossil Stories
    Garden Stories
    Monsters Are Real
    Page Frights
    Her Natural History
    Earth Optimism 2020
Tech Blog
Visit BHL
  • Home
  • News
  • Featured Books
    • All Featured Books
    • Book of the Month Series
    • BHL at 20
  • User Stories
  • Campaigns
    • Fossil Stories
    • Garden Stories
    • Monsters Are Real
    • Page Frights
    • Her Natural History
    • Earth Optimism 2020
  • Tech Blog
  • Visit BHL
Biodiversity Heritage Library - Program news and collection highlights from BHL
BHL News, Blog Reel, Tech Updates

BHL Servers are Moving!

An old map of the northeast United States with an arching arrow from Washington DC and Chicago

The big day is here! BHL’s Tech Team is starting the three-week process of moving BHL’s technical infrastructure from the Smithsonian data center just outside of Washington, DC, to the Field Museum in Chicago, Illinois.

First, though, we are deeply grateful to the Field Museum for welcoming BHL’s technology and helping ensure that biodiversity knowledge remains available to the global community. The support from their administration and technical team is invaluable.

We’ve been testing and configuring the network at the Field Museum and BHL is already quietly running on their network, so we are confident the process will go smoothly when we ship and install the production database and full-text-search servers.

“How will this affect BHL?”, you say. Great question! As much as possible, the BHL website will remain online and we do not expect any time where BHL is unavailable. The shipments to Chicago will take place in two parts to ensure BHL is always available, with some limitations. The first shipment on 11 June 2026 will have no impact on the regular functions of the site.

The second shipment on 25 June 2026 will cause the usual full-text search function to be temporarily unavailable while the full-text-search server is in transit. This means users will still be able to search titles, authors, subjects, and other catalog metadata, but users will not be able to search the full text of books and articles. This will last for 5-6 days over a weekend.

The 11th of June is a warm up, but the big day is the 25th of June when we officially begin serving BHL from the Field Museum.

We’ve set up an informational page with more details and will update it as things progress. We’ve also provided a map to illustrate where BHL’s servers are during transit.

An old map of the northeast united states with a winding dashed line between DC and Chicago.

A map of the route the servers will take to get to Chicago.
Please note that the path is neither accurate nor to scale. (Map Source)

But will the BHL servers feel at home in Chicago? To help them acclimate, we looked to historical maps of rainfall, soils, and vegetation to compare BHL’s former and future environments.


Vintage map showing rainfall in the northeastern part of the United States.

From: Atlas of American agriculture, no.5 (Source)

In Chicago, BHL will be receiving slightly less rainfall (30-35 ” or 75-88 cm per year) than on the U.S. East Coast (35-40″ or 85-100 cm). This, however, is mitigated by its proximity to Lake Michigan, which is one of the largest freshwater lakes in the world.

This looks like sufficient water for BHL, but these are historical values and may not reflect the effect of global climate change. In fact, it’s reported that the north-central part of the United States is in a moderate drought.


Vintage map showing soil types in the northeastern part of the United States.

From: Atlas of American agriculture, no.8 (Source)

What about soil type? BHL is leaving an area of Gray-Brown Podzolic soils to the much less prodigious Soils of the Northern Prairie. Looking closely at this map, we can see that BHL’s familiar soils are in close proximity to its new soil environment in Chicago, so we hope that this will help BHL rapidly make the transition to its new home.


Vintage map showing types of vegetation in the northeastern part of the United States.

From: Atlas of American agriculture, no.6 (Source)

Lastly, we look at vegetation. Historically the eastern seaboard of the United States is abundant in Oak-Pine and Chestnut-Oak-Yellow Poplar forests. The move to Chicago brings a potentially dramatic change as BHL moves from forests to the Tall Grasses of the Prairie Grasslands. Much like the new soil type, we see that BHL is still in close proximity to Oak-Hickory forests and we hope that the presence of the familiar Oaks will also help make the transition.


With familiar oaks nearby, sufficient water, and a welcoming new home at the Field Museum, we think BHL is well positioned to put down roots in Chicago.


June 9, 2026by Joel Richard
BHL News, Blog Reel, Tech Updates

A Brief Bit on BHL Battling a Barrage of Bots

People swatting a swarm of flying green and brown grasshoppers.

Summary

Over the past year, BHL has been forced to contend with the issue of AI Bot (short for robot) Crawlers and the effect of their unreasonable requests for BHL’s content. I say unreasonable because while BHL’s content is made freely available and is probably beneficial to modern Large Language Models (LLMs), the behavior of these bots and their disruptive effect on BHL has proven that they are bad partners in the exchange of information.

BHL is not the only organization to contend with this in recent months. Other cultural heritage organizations have reported the same or similar experiences, most notably this detailed report from Michael Weinberg at the GLAM-E Lab.

By the time this and other articles had been posted in mid-2025, BHL had already crested the first wave of interruptions.

A bit of background

When a request is made to a website, all actors are expected to identify themselves. Your browser informs the website that it is Firefox or Chrome. Many of the bots that come to a site are there to fill the index for a search engine. They have clever names like “GoogleBot” or “BingBot”. Furthermore, many LLM bots identify themselves, too. “ClaudeBot” or “GPTBot”, for example.

On the other side of the equation we have the “robots.txt” file which is meant to create an informal agreement between website and Bot to set rules on how the bots should behave. It contains directives like “you can go to these these URLs”, “please don’t go to these other URLs” or “please don’t make more than 10 requests per second”. These directives can be set individually for different bots to help guide them to what we think is the most useful content for them.

Some LLM bots ignore all of this.

The disruptive effect

In fact, the Grok bot sneaks its way into web servers by lying about who it is. No one has seen a “GrokBot” visiting their sites. This behavior is recently well documented. This is bad behavior, and it’s not something a handful of humans can fight alone.

We found that this is what was happening at BHL: The traffic that we saw did not identify themselves and they also came from many thousands of locations around the internet, making it difficult to control or block them. The numbers show it:

A line graph showing overall traffic to BHL with a step in the average traffic in the middle of the chart.

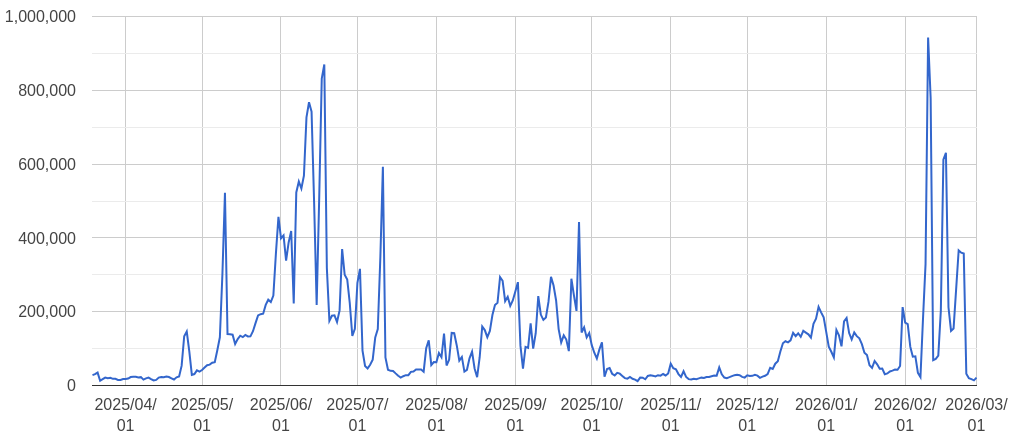
This chart shows traffic to BHL’s “/search” URL for approximately the past year. The peaks in June 2025 and February 2026 exceeded BHL’s capacity.

Beginning in April 2025, we saw a gradual increase in traffic that peaked on 19 June 2025 when it dropped off completely. This was the first wave of disruptions which we saw again later in 2025 and into 2026.

During this time, the Smithsonian was the host for the BHL servers and making changes in their ecosystem was a challenge, but the firewalls (and the team) at the Smithsonian are amazing and played a large part in keeping BHL operational. Regardless, we believe that enough traffic was allowed to get through the firewalls to still cause disruptions and unexpected errors trying to get to BHL.

Bar chart showing tall bars for many days over the past month.

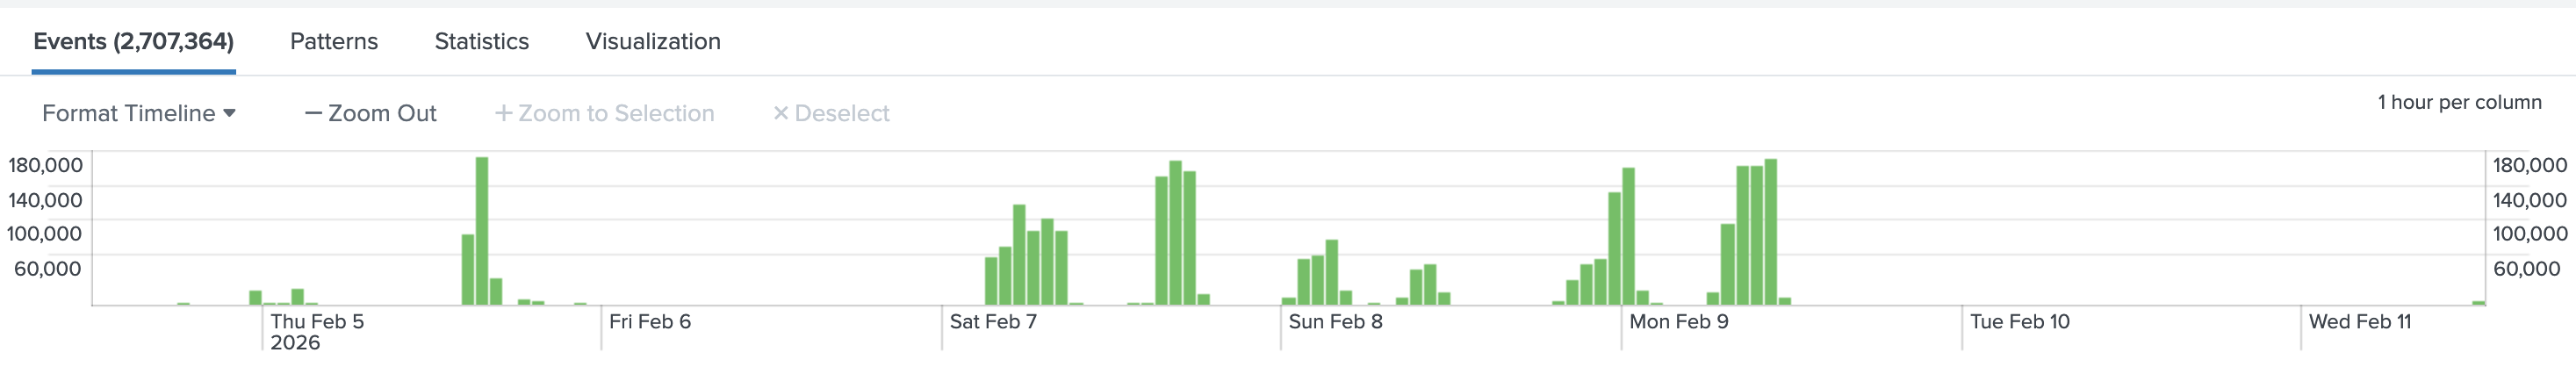
The Smithsonian’s firewalls were an important part of blocking traffic to BHL in February 2026. This chart shows requests per hour that were blocked by the firewalls for one week in February.

Our Response

Starting in June 2025 and continuing through September, Mike Lichtenberg, BHL Lead Software Engineer, made some small but effective changes to how BHL works internally. This allowed BHL to serve a new, higher level of traffic on the same technical infrastructure. Another change we made was to redirect certain requests to the Internet Archive, which was already protected by Cloudflare. This freed up capacity at BHL to serve more requests.

A line graph showing overall traffic to BHL with a step in the average traffic in the middle of the chart.

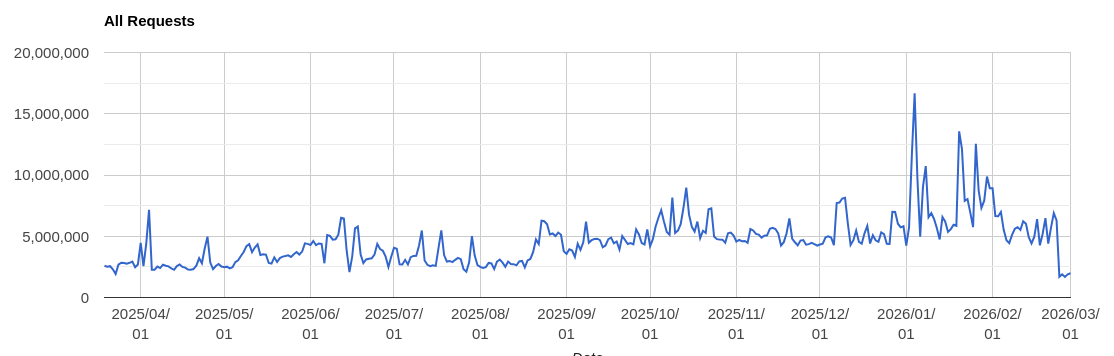
This chart shows per-day traffic to BHL. On the left side before August 2025, our regular traffic was around 2.5 million hits per day. On the right side, after Mike’s improvements the new baseline is closer to 5 million hits per day.

Unfortunately this was not enough. In January 2026, the bots returned, and worse than before.

The Cloudflare Cavalry

After a few weeks, it became clear that our efforts were no longer sufficient. Around 19 June 2025, BHL had responded to 870,000 search requests. This far exceeded our usual 22,000 searches per day.

On 10 February 2026, BHL received a peak of 943,000 search requests.

We’d been encouraged to pursue Cloudflare for some time, but it wasn’t until mid-February that our technical infrastructure was ready for the switch. On 20 February we officially started using Cloudflare and after a few missteps, everything was in place by 24 February.

But what is Cloudflare, you ask? It’s a service that sits between a web site and the rest of the internet and it looks at requests to that website to decide if they should be allowed through. As a very large player on the internet, Cloudflare has access to mountains of data on bot-like behavior to accurately analyze traffic in real-time.

After activating Cloudflare, we immediately saw a reduction in traffic and much more stability at BHL. In the following weeks, we made other changes, such as adding the ubiquitous “are you human?” checkbox that has become common across the internet.

A line chart showing a 60% drop in traffic around February 23 2026

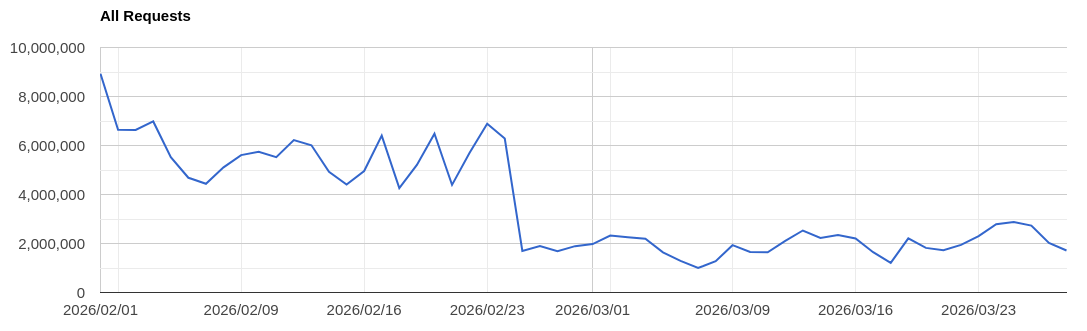
This chart shows traffic to BHL’s servers dropped dramatically when Cloudflare was fully activated.

Cloudflare is not simply a gatekeeper preventing unwanted traffic from coming to BHL. They also cache regularly requested parts of BHL (images, scripts, and styles) to deliver them to you from a location that is geographically closer to you. This means BHL will often seem to load faster than it did before. This also accounts for the drop in traffic to BHL as indicated in the chart above.

A line chart with three lines indicating that 2/3 of traffic to BHL is blocked by Cloudflare.

Cloudflare is now blocking a large amount of automated traffic coming to BHL. 

This chart shows a bit more detail of how Cloudflare is affecting requests to BHL. The top line is requests blocked by Cloudflare, the middle line is requests served by BHL’s own infrastructure, and the bottom line is requests served by  Cloudflare’s caches.

In Closing

It’s been a long journey, but BHL is much safer from the army of bots. This doesn’t mean that our work is done. We’ve had to make special efforts to not block access to BHL’s APIs and data feeds, which are often used by software or code…and which often behave like a bot! These settings have been in place for a few weeks now.

Additionally, we are investigating whether to allow the LLM bots to resume accessing our high-quality content, but we must be able to limit their flow of traffic to prevent overwhelming BHL’s servers.

Rest assured that BHL’s Technical Team is committed to keeping BHL up and running as we always have, but now we have a powerful new tool to help us in those efforts.

April 6, 2026by Joel Richard
Blog Reel, Tech Updates

BHL Traffic Challenges

In the past several weeks, we’ve seen a large, disruptive increase in traffic to the BHL main website. This blog post is meant to summarize the event, the effect on BHL and its servers, our response, and what we have planned should it happen again.

The problems experienced on BHL’s website are not related in any way to the transition away from the Smithsonian. We believe the timing of this activity and the resulting downtime to be purely coincidental.

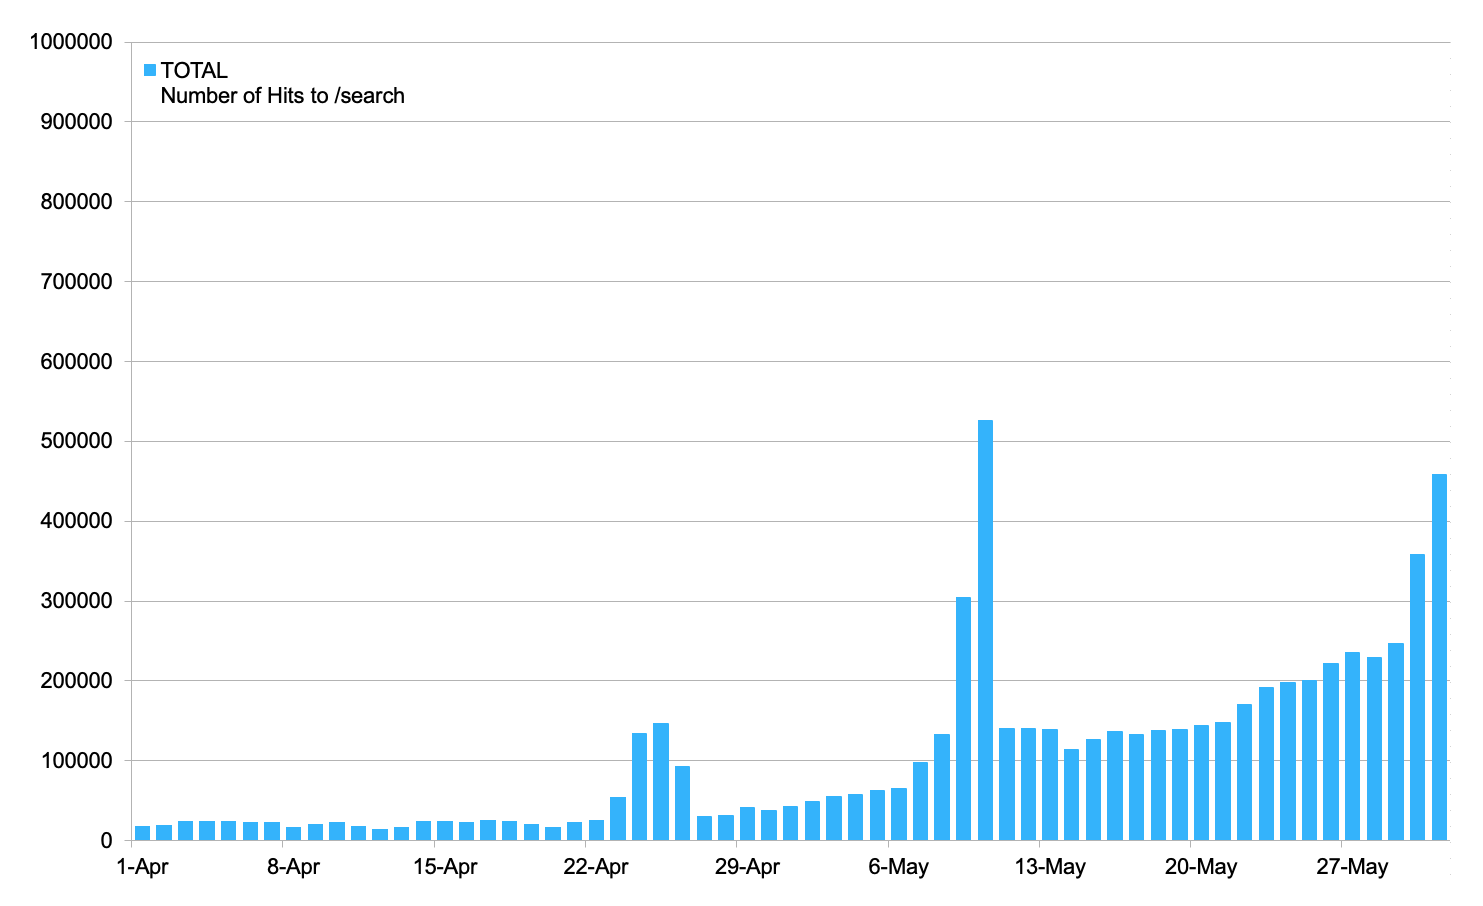
In early June, the Technical Team observed increased load on the full-text-search server, though it remained within acceptable limits and BHL performance was unaffected. Since this is not unusual for short periods of time and the server continued handling traffic, we weren’t  too concerned.

In the week of 7 June, we started to see that BHL was sometimes slower to respond. It was then that we noticed that traffic to the search server was dramatically higher than normal. A quick analysis of the server logs found that BHL was serving more than 10 times the usual number of searches. And more importantly, none of this activity was appearing in Google Analytics. It was clear that we were dealing with traffic from a bot. The bot wasn’t simply performing searches, it was also loading other parts of the sites, usually calling each part with a different taxonomic name each time.

A bar chart of BHL Search Traffic from April 2025 to June 2025 showing traffic increasing from 15,000 per day to 400,000 per day

BHL’s Search Traffic slowly increased in April and May.

What is most surprising is that this was not API traffic. BHL’s API provides rich data to anyone who uses it — data that is meant to be consumed by software. This bot was loading the BHL web pages as a person would using their computer’s web browser. It was getting results that were less computer-friendly than it would if it had used the API!

Unfortunately, the traffic was coming from all over the world and the bot was clearly not identifying itself as GoogleBot, BingBot or even OpenAI’s GPTBot. Slowing it down or blocking it entirely was proving to be a challenge. We activated rate limits on the web server, but the distributed nature of the bot prevented that from being effective. We investigated implementing Cloudflare Turnstile, but configuring that on short notice is a challenge. We thought about slowing down all queries to the server, but we knew that would affect all BHL users. In the end, we found that the bots had a sort of “fingerprint” that was different than that of regular users. We were prepared to start limiting traffic using the fingerprint when…. the traffic stopped. On 19 June, BHL started once again responding with its usual speed.

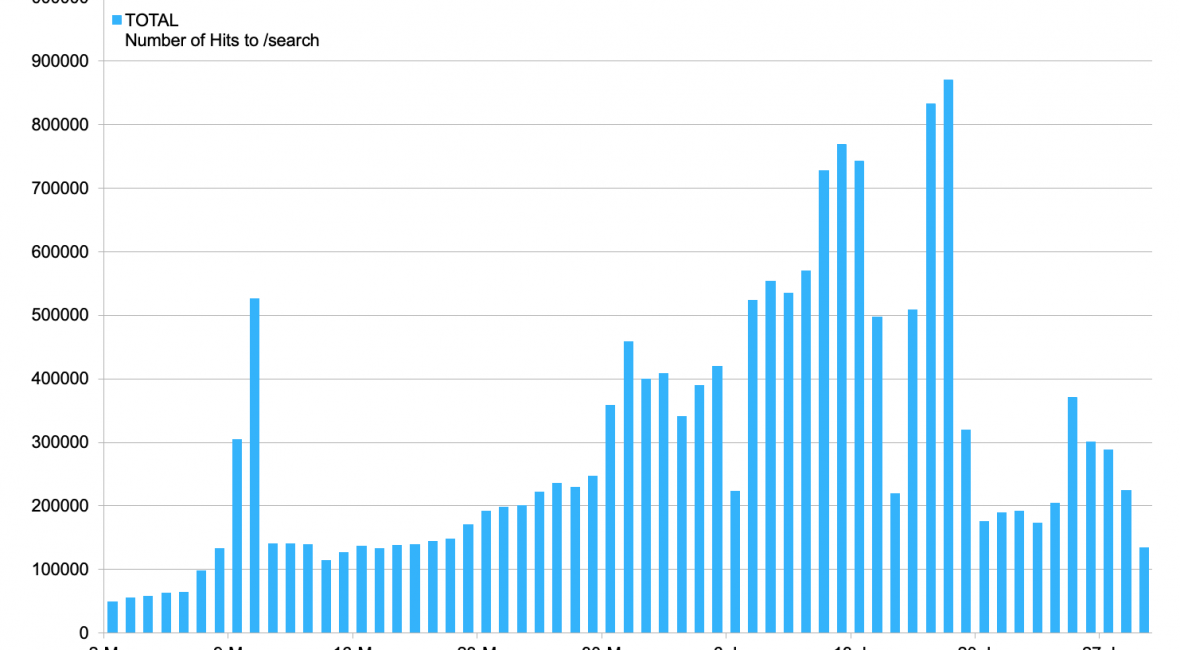
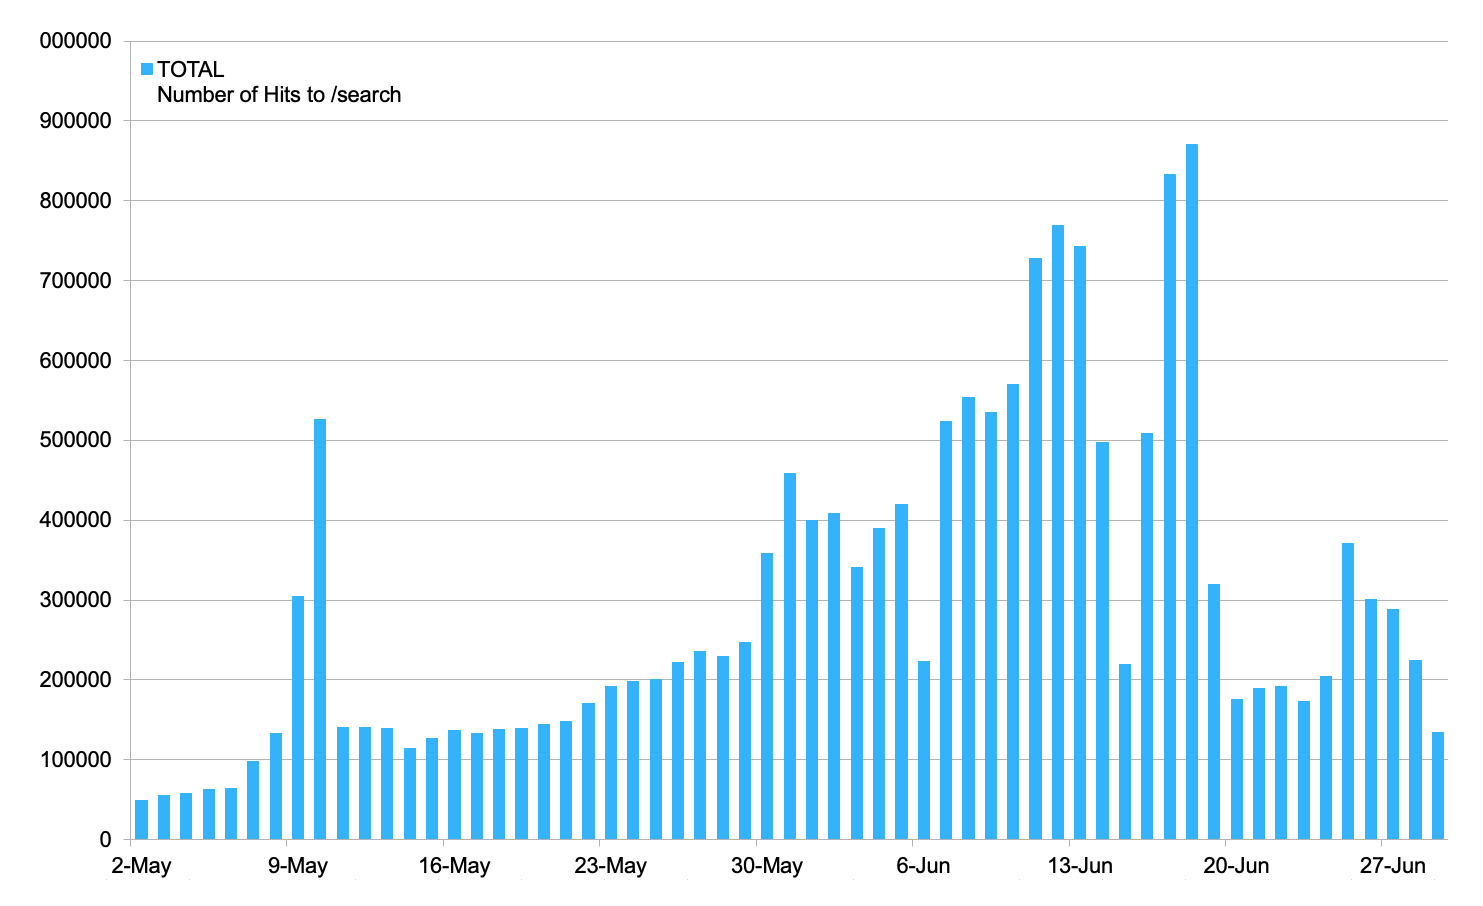
Looking at the graph of how many times the /search URL is called every day, we see some surprising numbers before traffic dropped on 19 June.

A bar chart of BHL Search Traffic from May 2025 through June 2025 showing traffic increasing from 40,000 per day to over 800,000 per day

BHL’s search traffic from May to June increased dramatically.

In general, BHL’s web infrastructure is able to easily support the current level of approximately 200k-300k searches per day. It is even possible to support up to about 400,000 searches per day, but that’s reaching the limit of what our infrastructure can handle. This is evidence that the hardware and software we have dedicated to search is very robust and well-suited to a busy site.

We haven’t performed an extensive analysis of the sources of this traffic, but at a glance they do seem to be from a variety of locations around the world. While the traffic may have been centered on certain countries or networks (such as the Google Cloud or others), we have no definitive evidence that it’s any one service.

One note: In the second chart, 6 June and 15 June show a much lower number of searches compared to the days before and after. This is not due to the bots slowing down, but instead were caused by BHL itself performing regular weekly and monthly tasks at the same time the bots were busy. This combination of activities overwhelmed the system and BHL was not responding at all.

When we look at the news, we find that our experience mirrors that of other cultural heritage sites, such as those reported in The Register:

Claburn, Thomas. (17 Jun 2025) Bots are overwhelming websites with their hunger for AI data. The Register.

…and also from smaller organizations such as our colleagues at FromThePage:

Brumfeld, Sara. (20 June 2025) Bot Traffic, AI Training, and Infrastructure Strain. FromThePage Blog.

Knowing we are not alone in this challenge is comforting, but it doesn’t eliminate the challenges. We continue to closely monitor BHL’s website performance and remain committed to keeping the website and API up and running as much as possible while we explore the best ways to mitigate the effects on BHL.

July 3, 2025by Joel Richard
Blog Reel, Tech Updates

OCR Improvements: An Early Analysis

Color coded comparison of OCR text highlighting the differences in text recognition

Optical character recognition (OCR) plays a critical part in BHL’s contributions to the scientific community. OCR in and of itself is a remarkable achievement, converting images of typewritten text to computer-readable text with “pretty good” accuracy. OCR on handwritten text is an even greater challenge to address and is beyond the scope of the improvements discussed here. The scientific work that BHL supports demands the best accuracy that we can provide using available tools, and let’s be honest, available budgets.

Recently, our colleagues at the Internet Archive made the transition away from the ABBYY FineReader OCR software to the Tesseract Open Source OCR engine. Over the past year or more, the OCR team at the Internet Archive has adapted and fine-tuned Tesseract to their workflows. Our first impression is that Tesseract OCR is more than “pretty good” in its ability to identify text from the page images provided to it.

The downside to this is that the Internet Archive has rightfully chosen to not re-process all existing text content through the Tesseract OCR engine. This is a prohibitively expensive and time-consuming prospect given that they have 35 million text-based items and reprocessing them would take several years and use up resources that could otherwise be used for gathering new content.

However, in the interests of supporting the efforts of the BHL community, the BHL Tech Team is working with our Internet Archive partner to reprocess some of BHL’s oldest content with the newest available version of Tesseract OCR. We are currently in a testing phase, and this blog post details some of our early results.

Selection

The first step in the process was to identify which versions of which OCR engine was used on BHL’s content. This was a simple matter of checking the “OCR” metadata value at the Internet Archive for each of the 263,000 items at BHL. The results as of December 2020 were:

“OCR” Metadata Value Count
ABBYY FineReader 8.0 80,447
ABBYY FineReader 9.0 35,276
ABBYY FineReader 11.0 45,679
ABBYY FineReader 11.0 (Extended OCR) 49,086
Tesseract 4.1.1 83
No OCR value  39,530

We suspect that those items with No OCR value are the very oldest content at BHL and were processed with an unknown OCR engine, or ABBYY FineReader 8.0 or earlier.

For a test and ultimately for moving forward with reprocessing, we chose the 80,000 items with ABBYY FineReader 8.0. We will likely add the other 39,500 items with No OCR value.

The Process

The steps to reprocess the OCR for an item are simple. We delete a few critical files at the Internet Archive and issue a “derive” command to restore them. In doing so, the OCR is regenerated and the “OCR” metadata value is updated accordingly.

The challenging part of the process is time and resources. OCR is a computationally expensive process and it can take dozens of minutes to several hours to create the OCR for a single Item. We also must be aware that we can potentially take computing resources from other activities at the Internet Archive, so we issue the “derive” command at a lower priority than other Internet Archive activities, effectively using up spare or unused resources as they are available.

In other words, we’re being good citizens of the Internet Archive ecosystem.

The Results

Since this is what you came for, in summary, the results are very good and this is a worthwhile effort.

Our tests for evaluating the results are a combination of visual inspection and computational analysis. For backup and local analysis purposes, BHL keeps a copy of all content at the Internet Archive, but its updates are currently disabled during this testing phase. Using this backup copy as the source of “old” content, we can compare it to the “new” content at the Internet Archive.

Analysis 1: Misspellings

The first analysis is to simply check for misspelled words. While at first glance this seems too simplistic, OCR operates on a letter-by-letter analysis of the text and often has challenges correctly identifying a letter and will often produce invalid words.

Using the Linux aspell tool, we can find misspelled words and count them using a command such as the following:

cat FILENAME | aspell list | wc -l

This command sends the contents of FILENAME to aspell, which lists misspelled words, one per line, then sends that list to the word-count wc command to list the number of lines. Using a test case of 1955seventyoneye1955harr, we count the misspellings for the old and new versions:

  • Old OCR Text (from 2013): 2,357 misspelled words
  • New OCR Text (from 2020): 1,639 misspelled words

There are expected commonalities between the two lists of misspelled words. Proper or scientific names such as Elberta and Harrison or varietal names such as Dixired or Redhaven don’t exist in the standard English dictionary. Additionally, legitimate misspellings in the printed text appear, such as Recomemnded, appear in the results. Regardless, the greatly reduced number of misspellings is a good indicator of OCR accuracy. 

Analysis 2: Visual Inspection

One of the most important downstream effects of improved OCR is improved identification of scientific names. BHL partners with the Global Names Architecture (GNA) to identify scientific names in the BHL text. Focusing on this, we can see that improvements in the OCR reveal more scientific names that were missed in the past.

Example A: Ligustrum ovalifolium

The original page image at BHL discusses the California Privet (Ligustrum ovalifolium).

The OCR comparison of the old engine (in red) and the new (in green) shows that the new Tesseract OCR engine was better able to convert the words to text. This will ultimately cause this name to appear in BHL’s list of scientific names on this page of the document where currently it may not appear.
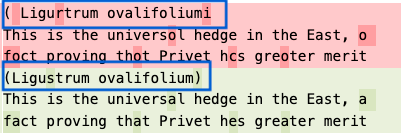
Color coded comparison of OCR text highlighting the differences in text recognition

Example B: Multiple names

A second example showing numerous taxon names that are now correctly identified by the OCR. It’s worth mentioning that this page in BHL includes the genus (Magnolia or Lonicera) but not the full species name. We expect that the full name will appear in BHL with the improved OCR.
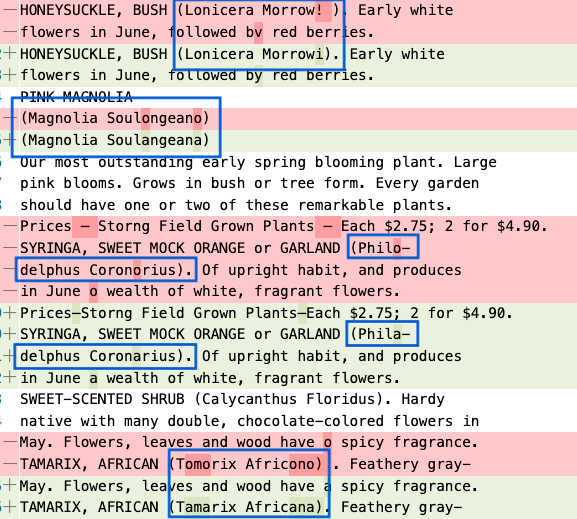
Color coded comparison of OCR text highlighting differences in text recognition

Analysis 3: Scientific Name Finding

As mentioned earlier, BHL partners with the Global Names Architecture (GNA) to identify scientific names in the OCR content of BHL. While we use APIs to perform this function, GNA also offers a command line tool to process a body of text to identify scientific names.

Similar to counting the misspelled words, we use a series of Linux commands to process the OCR text and count the scientific names found in the text.

gnfinder find FILENAME  -c -s 1,3,4,9,11,12,167,172,179,181 |
  jq '.names[] .verification.BestResult.matchedName' | 
  sort | uniq | wc -l

gnfinder is the command to find the scientific names. This command returns JSON content, which we then send to the jq command to count the number of BestResult.matchedName elements in the JSON. Then we sort, get the unique names, and count them with wc. A sample of the JSON output looks like:

{
  "type": "Uninomial",
  "verbatim": "(Lonicera",
  "name": "Lonicera",
  "odds": 93678.22872366496,
  "annotation": "",
  "verification": {
    "BestResult": {
      "dataSourceId": 1,
      "dataSourceTitle": "Catalogue of Life",
      "taxonId": "4091239",
      "matchedName": "Lonicera",
      "matchedCanonical": "Lonicera",
      "currentName": "Lonicera",
      "classificationPath": 
        "Plantae|Tracheophyta|Magnoliopsida|Dipsacales|
           Caprifoliaceae|Lonicera",
      "classificationRank": 
        "kingdom|phylum|class|order|family|genus",
      "classificationIDs": 
        "3939764|3942634|3942724|3942969|3942971|4091239",
      "matchType": "ExactMatch"
    }
  },
  [...]
}

Counting these for our example 1955seventyoneye1955harr, we find:

  • Old OCR Scientific Names: 20 unique names found
  • New OCR Scientific Names: 38 unique names found

This is a simple case indicating that an additional 18 unique names were found in the content. Taking a random sample of 10 other items shows the following larger differences in the number of unique scientific names found:

Item Identifier Unique Names Found in OCR
Old New
guidebooksofexcu03inte 190 190
dissectionofdoga00howe 23 25
ueberliasbeta00schl 38 55
mobot31753003413330 641 920
CUbiodiversity1249031-9750 1,042 1,244
annalesdelasoci2627188283soci 2,786 3,046
weiterebeobachtu00kl 59 62
verhandlungender42zool 2,487 2,806
etudedesfleu1865cari 1,077 1,148
bulletinbiologiq47univ 750 1,127

It is worth noting that a visual inspection of these names indicates there is some fine-tuning remaining. gnfinder identifies both binomial names (genus and species) and uninomial names (genus only) in the content. There look to be instances where names are found in the new OCR that don’t exist in the content, but are incorrectly being identified as uninomials. gnfinder provides a type of score that must be fine tuned for the new OCR in order to reduce this effect. This is a task for future discussion.

Summary

While there is further work to do in loading this new content into BHL and in the scientific-name-finding part of the process, these initial results are encouraging and are enough to help us make the decision to continue reprocessing the OCR using the Internet Archive’s installation of Tesseract OCR.

This journey is years in length. Even if we were to process at the highest priority (something we would never consider), we are planning to affect nearly half of BHL’s 263,000 items. Our current rate of progress at the aforementioned lower priority is approximately 100 items per day. At such a pace, the 120,000 items will take three years to complete.

Future blog posts will occur as there are more updates to share with the BHL community.
July 19, 2022by Joel Richard
BHL News, Blog Reel, Tech Updates

New Article PDF Content Available

A sample of a printed page of a book with highlighted text superimposed over the printed text

The BHL Tech Team is pleased to announce a new form of content available in BHL: Article PDFs. While this may not sound like anything new, after all, we have had a tool to download PDF content for some time, this update changes both how the PDFs are created and maintained, and how BHL is viewed by content aggregators on the internet, most notably Unpaywall.

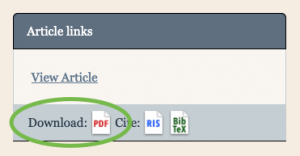
Screenshot of the Download PDF icon.

The new Download PDF icon

How to use it? While browsing an article, you will now see a Download PDF icon below the View Article link on the right side of the page. Clicking the link will immediately download the PDF to your computer (or view it in your web browser, depending on your settings.)

The benefits of the immediate download are:

  • No waiting.
  • No selecting pages.
  • The PDF contains embedded, searchable, copy-paste-able text.†
  • The PDF contains rich XMP-based metadata about the article.

An important change to note is that when viewing an article within an item at BHL, the Download Contents > Download Article link will now direct the visitor’s browser to the new PDFs for immediate download. This is a departure from what we had before in that the pages of the article were pre-selected for download and the visitor was then required to complete the process and wait for the PDF to be generated. We expect the new PDFs to be an improvement for our visitors who come to download articles. View the How do I download a PDF of an article? FAQ for simple download instructions.

Visitors to BHL are still able to manually create PDFs using the Download Contents > Select Pages to Download feature. This feature has not been removed, but it still means that it takes some time to create those PDFs and email the person when the PDF is ready. This option is useful for articles that have not been indexed in BHL, and therefore do not have a Download Article link. View the How do I generate a custom PDF of selected pages from the book? FAQ for complete instructions.

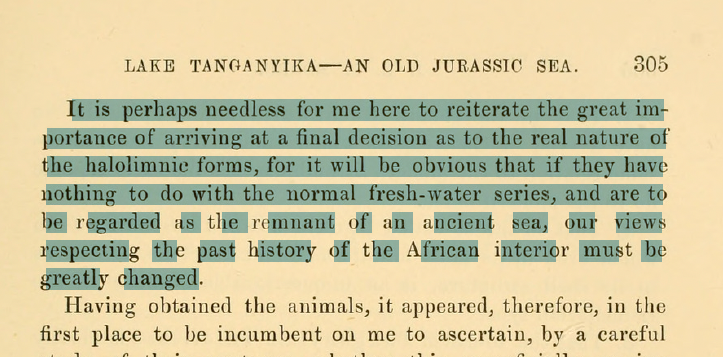
The most important feature of the new Article PDFs is the embedded text† within the document. The select-able text is an invisible text layer in the PDF, but it appears when you select or search for text within the document:

A sample of a printed page of a book with highlighted text superimposed over the printed text

An example of select-able text in an Article PDF.

While the appearance of the text may look… less than ideal, rest assured that the text can be copied out intact and used in another program. Example:

It is perhaps needless for me here to reiterate the great importance
of arriving at a final decision as to the real nature of
the haloliranic forms, for it will be obvious that if they have
nothing to do with the normal fresh-water series, and are to
be regarded as the remnant of an ancient sea, our views
respecting the past history of the African interior must be
greatly changed.

Other, less visible benefits to the PDFs are that they are directly linked from the citation_pdf_url meta-tag on the web page which makes them more findable by Google Scholar, Unpaywall, and potentially other aggregators.

For the technical-minded, the PDFs (many tens of thousands of them) are created in advance and stored on BHL’s servers. Changes to data within BHL will cause the PDF to be updated automatically, usually within several hours.

We hope that this is a welcome addition to BHL.


† – Please note that the text is only as good as the OCR that was generated for the text on the page. While the OCR text is probably very good for the prose sections of an article, titles, tables, and other special content may not appear as expected.

March 14, 2022by Joel Richard
BHL News, Blog Reel, Tech Updates

Additions to Text Exports Coming Soon

The BHL website was recently updated for new fields to download content. The TSV Data Exports are being updated on 1 September 2019 to mirror this change.

History

Recently, we added new URLs to the site to facilitate getting the text, Images or PDFs of the items at BHL. When viewing an item (for example, Darwin’s Origin of Species), the Download Contents > Download Book option presents four choices for downloading the contents of an item. Three of these have new, normalized URLs to download the content of an item.

  • PDF: https://www.biodiversitylibrary.org/itempdf/124544
  • All: (unchanged)
  • JPEG 2000: https://www.biodiversitylibrary.org/itemimages/124544
  • Text: https://www.biodiversitylibrary.org/itemtext/124544

We added these links because we discovered that there were some inconsistencies in connecting our content to the Internet Archive. Additionally with the new ability of BHL Partners to upload transcribed text, we needed a method of downloading the updated text rather than the original OCR.

What has changed?

In summary, these three new URLs have been added to the tab-delimited Item (volumes) TSV download files. The presence of these fields will impact any downstream processes that rely on the order of the fields. Please review your code if you rely on the field order instead of the field names of the TSV file.

In the past, the fields were:

ItemID, TitleID, ThumbnailPageID, BarCode, MARCItemID, CallNumber, VolumeInfo, ItemURL, LocalID, Year, InstitutionName, ZQuery, CreationDate

On 1 September 2019, the fields will change to the following:

ItemID, TitleID, ThumbnailPageID, BarCode, MARCItemID, CallNumber, VolumeInfo, ItemURL, ItemTextURL, ItemPDFURL, ItemImagesURL, LocalID, Year, InstitutionName, ZQuery, CreationDate

These fields mirror those of the new links mentioned above and will save you from needing to create the URLs to download content.

Please update your code or processes if necessary!

August 27, 2019by Joel Richard
BHL News, Blog Reel, Tech Updates

BHL Participates in the Global Names Workshop

gnames-workshop.jpg

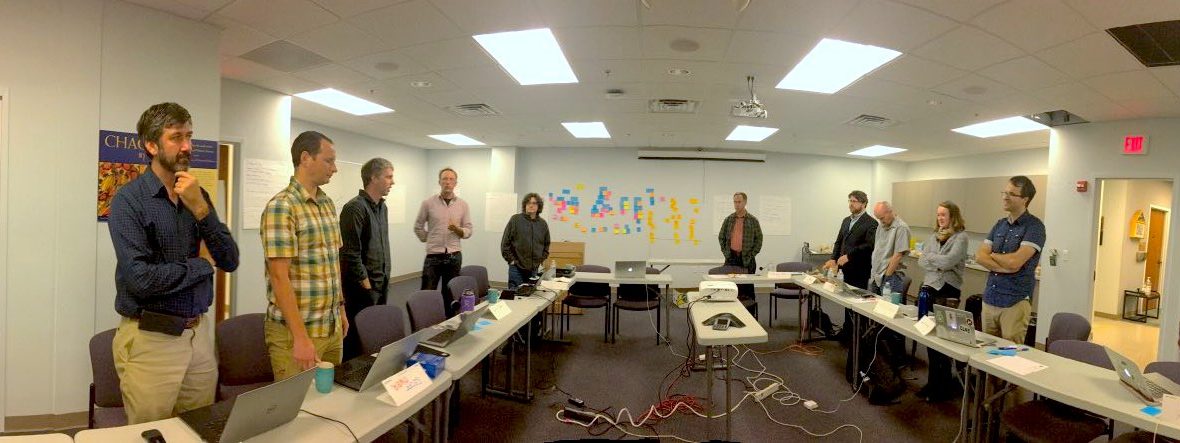
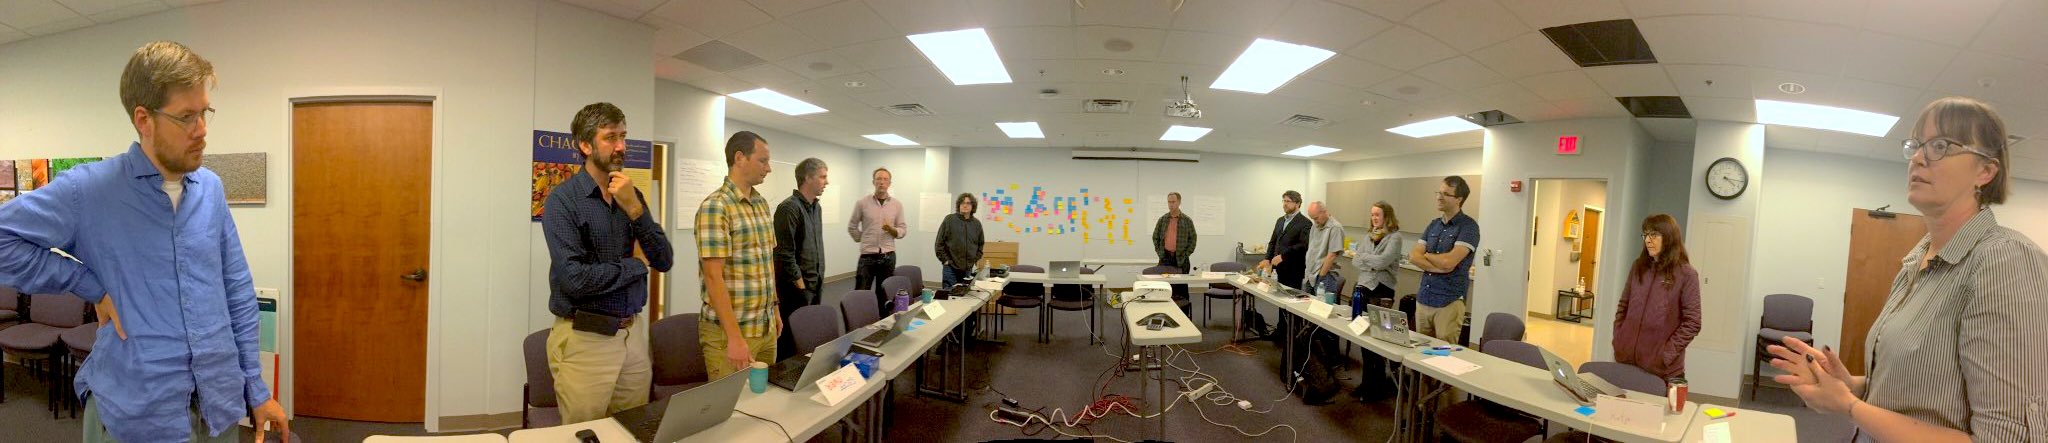
Participants at the The Global Names Project workshop discuss progress in a morning “stand up” briefing. Photo by Deborah Paul (iDigBio).

The Global Names Project held a workshop on 17-19 June 2019 on the Campus of the University of Illinois at Urbana-Champaign. The workshop was titled Scientific names indexing and data mobilization of Biodiversity Heritage Library using tools from Global Names project and was hosted by the Species File Group at the  Illinois Natural History Survey. Eighteen people attended representing a variety of organizations interested in BHL content: Global Names Architecture, iDigBio, TaxonWorks, UIUC Species File Group, the Illinois Library, Encyclopedia of Life, the DINA Project, the Catalogue of Life, GBIF, Species File Group Argentina, the HathiTrust Research Center, and Global Biotic Interactions.

The workshop was organized as an unconference/hackathon in which the meeting is planned by all participants at the workshop. We initially all proposed topics we individually were interested in exploring; these were our “selfish goals”. In an exercise at the workshop, those goals were broken into similar or related topics. The most popular topics (see those sticky notes on the wall — in the background of the photo) became the focus of “pitches”, i.e. challenges that we could address at the workshop. We self-organized into working groups under the banner of pitch and got to work.

Note that at a hackathon, the goal is that you are always either “doing or learning.” For example, some of us learned how to mine BHL content using the Developer and Data Tools. And if you’d like to try it, you too can install and use the gnfinder and gnparser tools. The gnparser tool breaks scientific name-strings into the semantic elements of the string. While gnfinder searches text output (like OCR) for names.

Overall, the activities of the workshop centered around further improving the information that we can extract from the OCR (optical character recognition) content that is generated from the page images in BHL, including improving that OCR content itself.

One group focused on attempting to find Species Identification Keys in BHL. Using a versioned, citable, and verifiable snapshot of the BHL OCR text corpus1, the group discovered that a variety of ways in which a species identification key is labeled in the text combined with the natural inaccuracies of OCR make the task of identifying a heading for a key challenging2.

Another group worked on connecting the APIs of TaxonWorks, Global Names, and BHL. Their goal was to integrate information and resources from all three in a single interface that highlighted the BHL pages that species were originally described on. This group managed to wrap all three APIs in a single place (a “Task” in TaxonWorks), but problems with matching citation data across platforms prevented them from truly “closing the loop”.

Finally, the largest group focused on extracting different entities from the OCR content of the BHL, for example geographic names, people names, and organizations. This group experimented with a variety of natural language techniques and tools including the Edinburgh Geoparser, IBM Watson, Microsoft Azure Cognitive Services, and LingPipe and identified some additional challenges to extracting such entities from BHL. Not surprisingly, there is some overlap between place names and taxon names. For example, “St. Lucia” can be conflated with the genus “Lucia” (a type of butterfly), which certainly adds a hurdle for accurate entity identification.

The results of the workshop are being integrated into a Wiki that contains our initial goals and that invites other stakeholders to get involved. One direct outcome of the workshop is that the BHL will move to provide quarterly exports of the OCR, available to anyone, to mine and experiment with.  Previously, this content was not easily downloadable. The workshop discussions and hacking drove home the point that this corpus is a key element for future developments. Many other broader topics were also raised throughout the meeting. In particular, we explored the idea of opening a worldwide biodiversity informatics channel to better facilitate communication and share ideas among interested parties in real-time. This could be done using Slack.

Many thanks to the Global Names and the Illinois Natural History Survey for hosting, and especially Dima Mozzherin for all of his work on the Global Names Name Finding algorithm, which has opened the door to moving BHL’s content into the next decade.

References

[1] Poelen, Jorrit H. (2019). A biodiversity dataset graph: Biodiversity Heritage Library (BHL) (Version 0.0.1) [Data set]. Zenodo. http://doi.org/10.5281/zenodo.3251134

[2] Poelen, Jorrit H., Schulz, Katja, Trei, Kelli J., & Rees, Jonathan A. (2019, July 10). Finding Identification of Keys in the Biodiversity Heritage Library (Version 1.1). Zenodo. http://doi.org/10.5281/zenodo.3311815

July 15, 2019by Joel Richard
Page 1 of 212»

Help Support BHL

BHL's existence depends on the financial support of its patrons. Help us keep this free resource alive!

search

About BHL

The Biodiversity Heritage Library (BHL) is the world’s largest open access digital library for biodiversity literature and archives. BHL operates as a worldwide consortium of natural history, botanical, research, and national libraries working together to digitize the natural history literature held in their collections and make it freely available for open access as part of a global “biodiversity community.”

Join Our Mailing List

Sign up to receive the latest news, content highlights, and promotions.

Subscribe Now

Subscribe to Blog via Email

Enter your email address to subscribe to this blog and receive notifications of new posts by email.

Join 319 other subscribers

Subscribe to Blog Via RSS

Subscribe to the blog RSS feed to stay up-to-date on all the latest BHL posts.

Access RSS Feed

Inspiring Discovery through Free Access to Biodiversity Knowledge.

The Biodiversity Heritage Library makes it easier than ever for you to access the information you need to study and explore life on Earth…for free, anytime, anywhere.


64+ Million Pages of
Biodiversity Literature Online.

EXPLORE

Tools and Services
to Transform Research.

EXPLORE

300,000+
Illustrations on Flickr.

EXPLORE

ABOUT | HARMFUL CONTENT | PRIVACY | SITE MAP | TERMS OF USE