Biodiversity Heritage Library - Program news and collection highlights from BHL
  • Home
  • News
  • Featured Books
    • All Featured Books
    • Book of the Month Series
    • BHL at 20
  • User Stories
  • Campaigns
    • Fossil Stories
    • Garden Stories
    • Monsters Are Real
    • Page Frights
    • Her Natural History
    • Earth Optimism 2020
  • Tech Blog
  • Visit BHL
Home
News
Featured Books
    All Featured Books
    Book of the Month Series
    BHL at 20
User Stories
Campaigns
    Fossil Stories
    Garden Stories
    Monsters Are Real
    Page Frights
    Her Natural History
    Earth Optimism 2020
Tech Blog
Visit BHL
  • Home
  • News
  • Featured Books
    • All Featured Books
    • Book of the Month Series
    • BHL at 20
  • User Stories
  • Campaigns
    • Fossil Stories
    • Garden Stories
    • Monsters Are Real
    • Page Frights
    • Her Natural History
    • Earth Optimism 2020
  • Tech Blog
  • Visit BHL
Biodiversity Heritage Library - Program news and collection highlights from BHL
BHL News, Blog Reel, Featured Books

Illuminating BHL’s Dark Data: Citizen Scientists and AI Unlock Key Biodiversity Data in GBIF

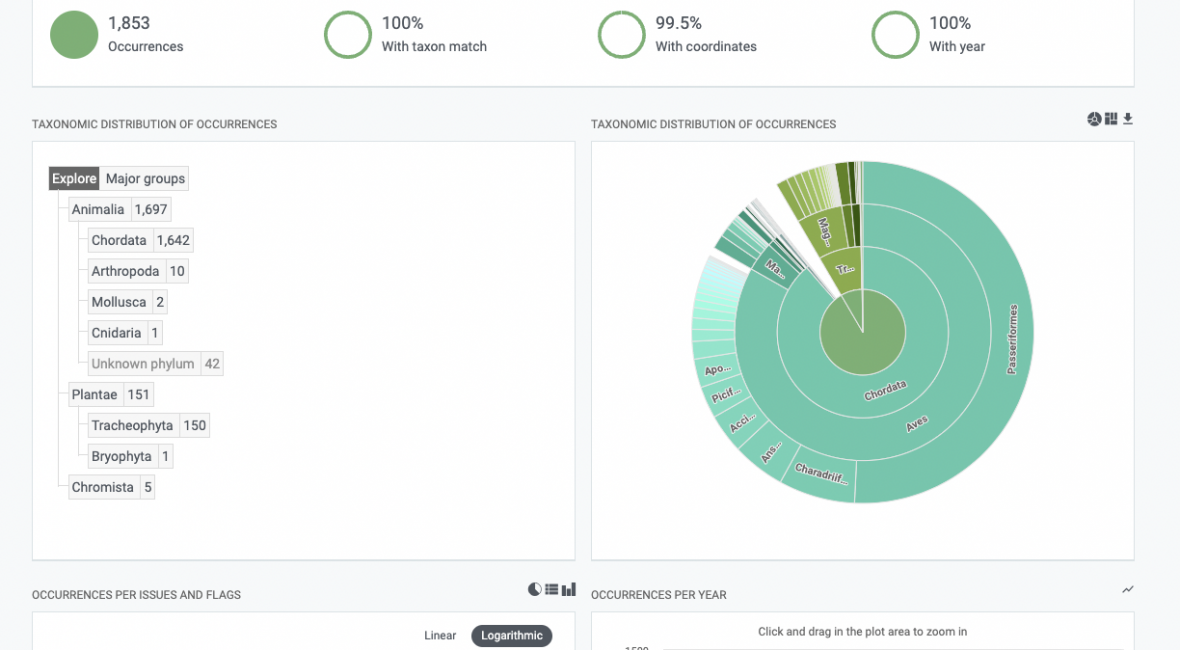
Visualizations of species occurrence data deposited in GBIF from the journals of William Brewster

In the face of climate change and environmental challenges, understanding and documenting Earth’s biodiversity is essential. The Global Biodiversity Information Facility (GBIF) serves as a global repository for biodiversity data, playing a pivotal role in this critical mission of safeguarding our planet’s biodiversity. Species occurrence data sourced from the Biodiversity Heritage Library (BHL) provides insights into species distributions, behaviors, and interactions much deeper into time, offering key species baseline data required to effectively address the climate crisis. Without accurate and comprehensive data in GBIF, our collective ability to track environmental changes and make informed decisions is severely hampered.
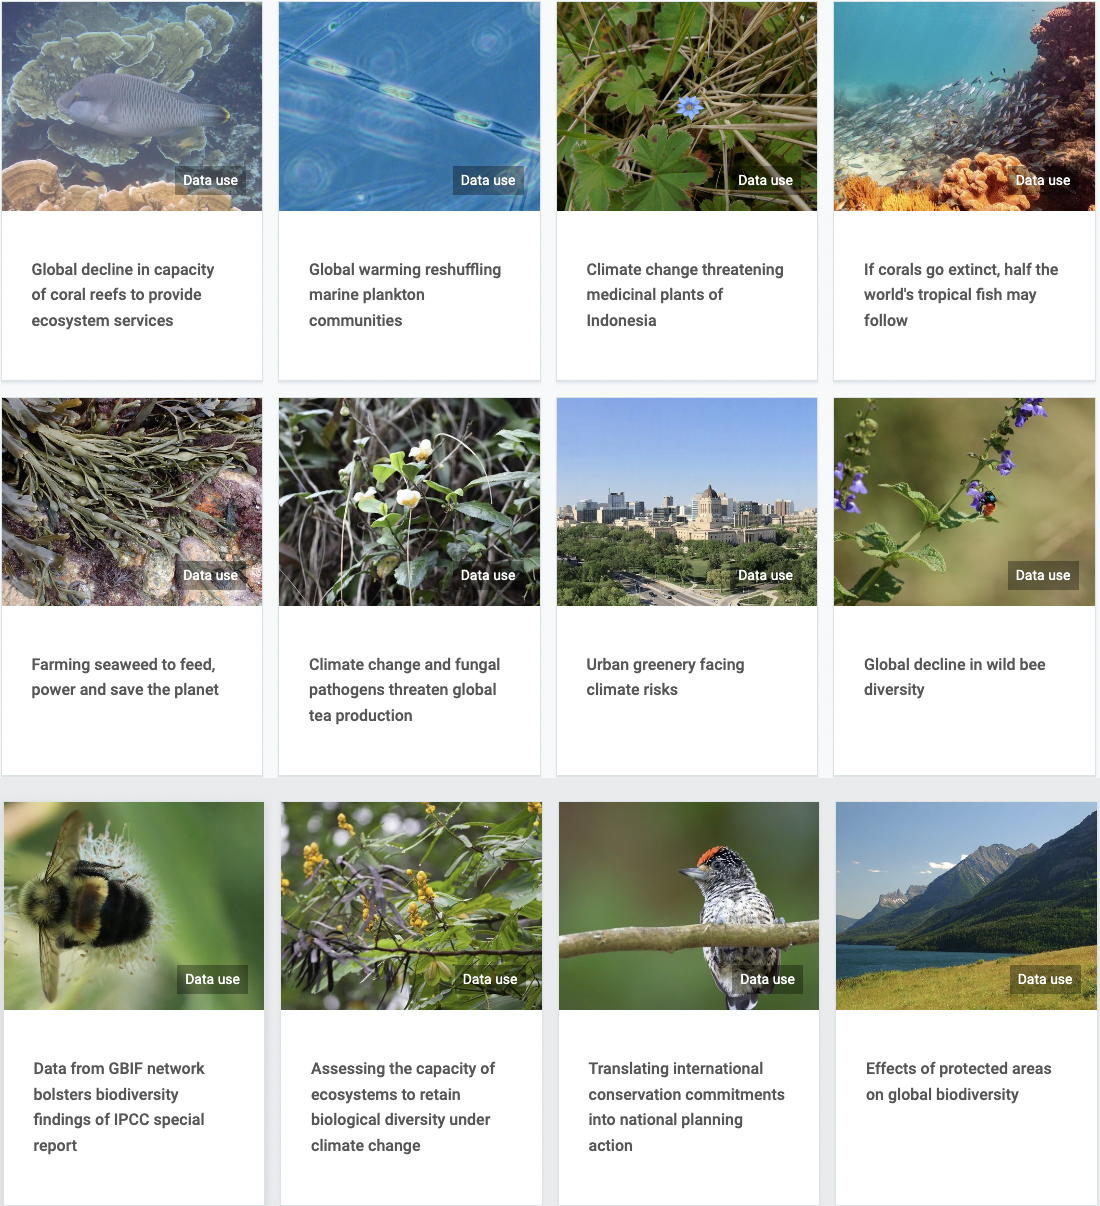
Collage of images representing data used from GBIF

Figure 1: GBIF-mediated data is used extensively in climate science and informs global environmental policy. For more information see: https://www.gbif.org/climate

As a GBIF participant node, BHL is committed to sharing biodiversity data openly, adhering to FAIR (Findable, Accessible, Interoperable, Reusable) and CARE (Collective Benefit, Authority to Control, Responsibility, Ethics) data principles, and collaborating with a global network of biodiversity organizations to bolster and build capacity to strengthen the biodiversity information infrastructure. To honor our commitments, technical staff from BHL are working to establish a scalable data pipeline of occurrence data currently trapped in archival field notes, journals, letters, correspondence, and other primary source materials. The journey has been an arduous one due to poor OCR (optical character recognition) data quality for BHL’s sub-corpus of handwritten materials.
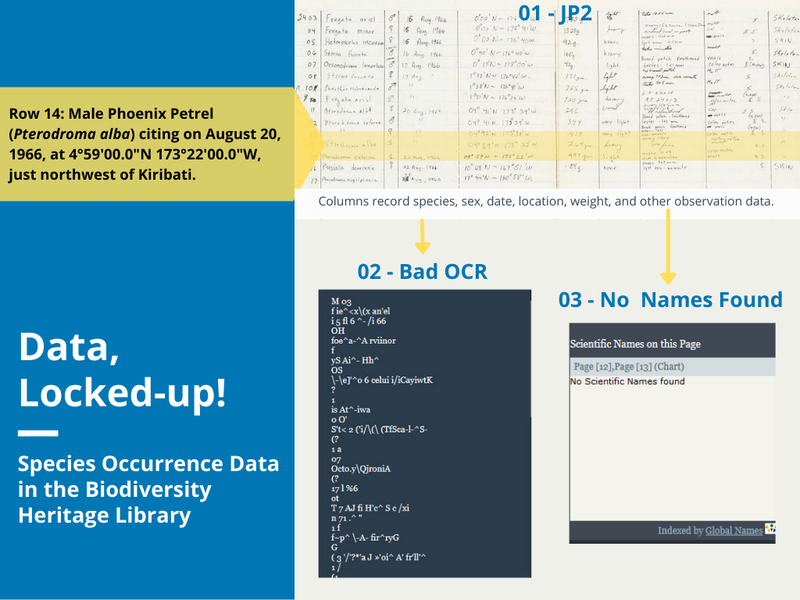
Example of handwritten observation data with poor quality OCR and no scientific names found on the page

Figure 2: Sample of “dark” handwritten observation data with corresponding unstructured, uncorrected OCR text. From National Museum of Natural History, Pacific Ocean Biological Survey Program, At-sea, 1963-1966, 1968, part 3: July – August 1966.

Technical approaches to building a BHL ETL (Extract, Transform, and Load) data pipeline of species occurrence data from BHL’s field notes include machine learning, artificial intelligence (AI), and data extraction through innovative transcription projects like DigiVol, the crowdsourcing citizen science platform collaboration between the Australian Museum and the Atlas of Living Australia.
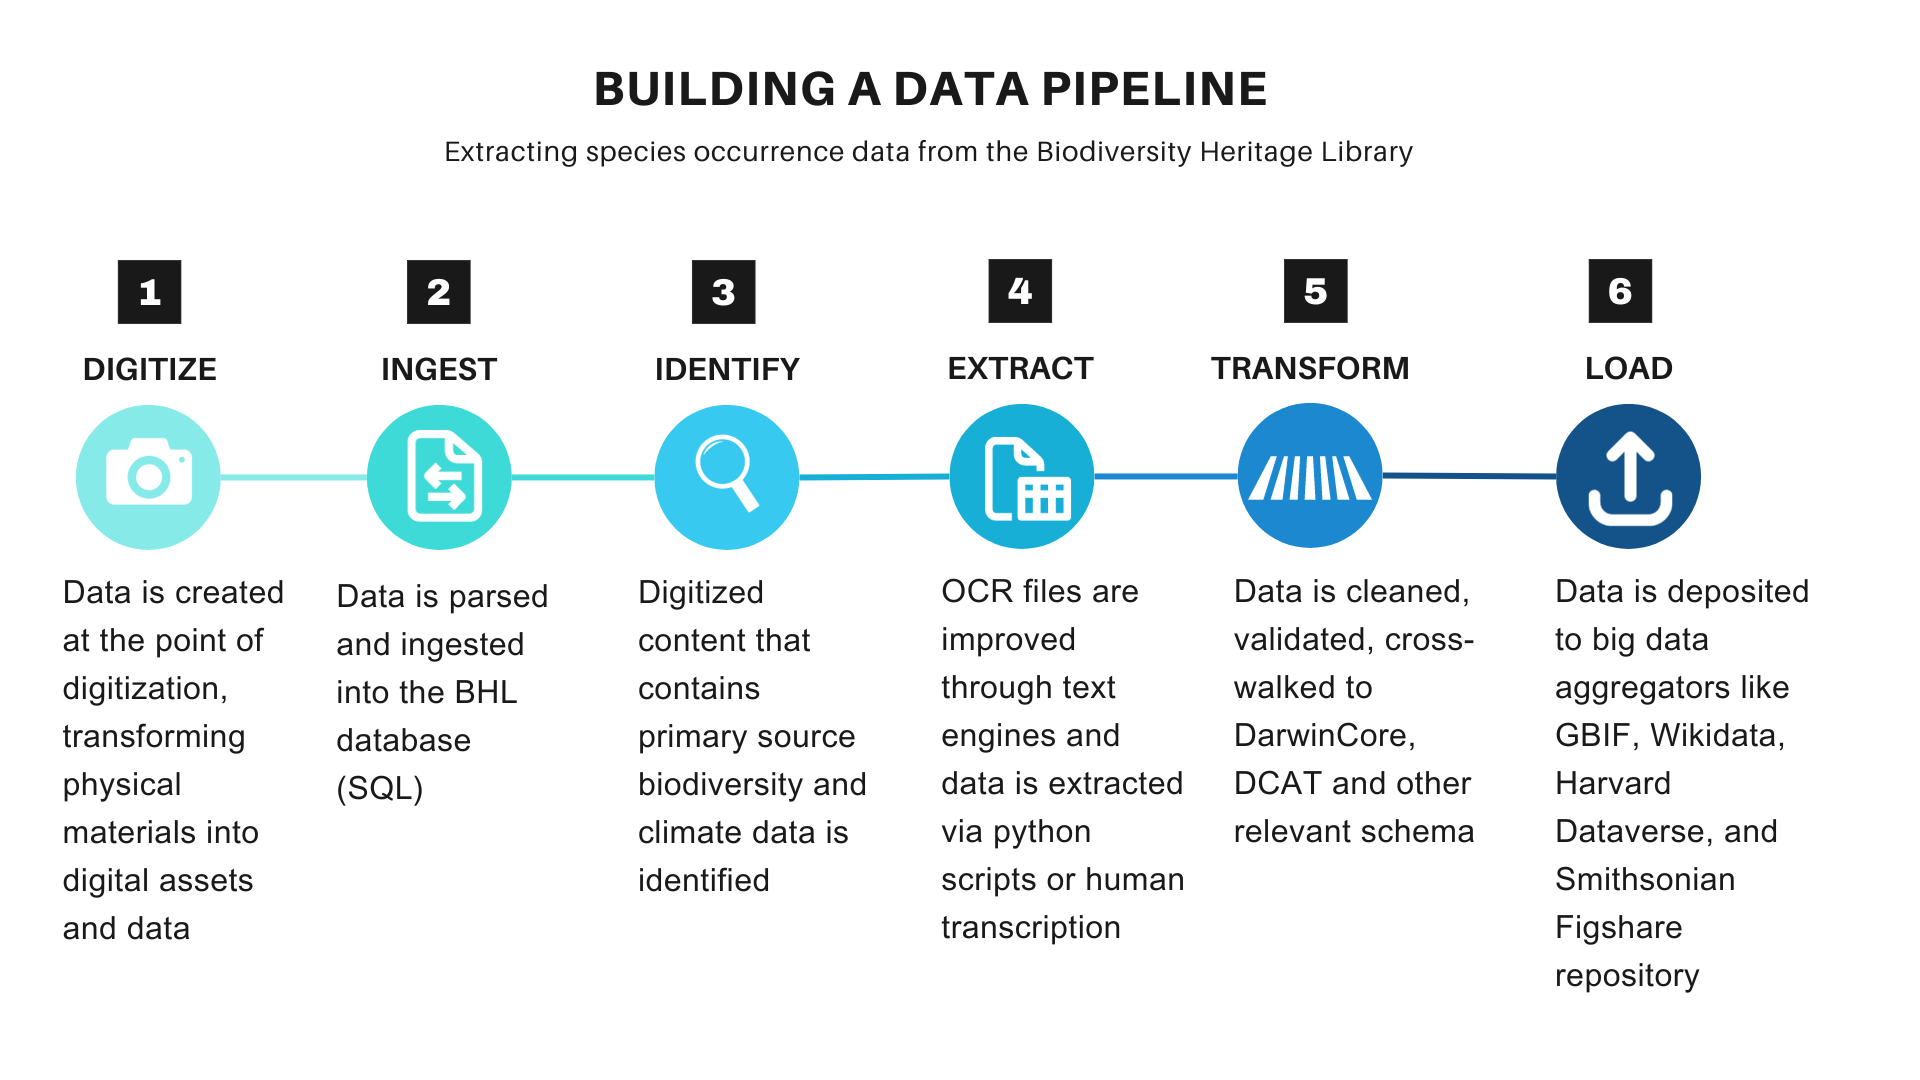
Building a data pipeline: extracting species occurrence data from BHL. 6 steps include: digitize, ingest, identify, extract, transform, and load.

Figure 3: Learn more about how BHL is building a new data pipeline from the recent talk given at TDWG 2023 entitled Unearthing the Past for a Sustainable Future: Extracting and transforming data in the Biodiversity Heritage Library for climate action; abstract; recording.

Now underway, is a global effort to convert centuries of biodiversity knowledge into accessible and actionable data, utilizing advanced AI and technical approaches. BHL Partners now have a stake in supporting international conservation policy aimed at safeguarding Earth’s biodiversity through greater data integration with the global biodiversity data infrastructure.

The Journals of William Brewster

The ornithological papers of William Brewster (1851-1919), held in the Ernst Mayr Library and Archives of the Museum of Comparative Zoology (MCZ) at Harvard University, are a rich source of historical species occurrence data and an ideal use case for building a BHL ETL data pipeline. Brewster’s field notes, journals, diaries, and correspondence comprise over 60,000 pages replete with detailed bird observations spanning 54 years (1865-1919). These records augment and extend his collection of over 40,000 bird specimens, bequeathed by Brewster to the MCZ and considered “one of the largest private collections ever made in this country [United States], and in some respects … by far the most valuable” (Henshaw, 1920). Thanks to a number of projects facilitated by the Ernst Mayr Library over the years, Brewster’s journals have been digitized and later transcribed using DigiVol.

Figure 4 below shows one example of Brewster’s extensive species lists. Brewster fastidiously recorded all essential elements of a species occurrence record and often more such as habitat information and detailed behavioral descriptions. The complexity of this example, featuring Brewster’s unique formatting, use of ornithological symbols, and tiny, crowded handwriting, highlights the value of crowdsourced human transcription by a team of enthusiastic, dedicated volunteers.

Figure 5 shows a portion of the transcription of this species list, produced in DigiVol by one of our long-time transcribers.
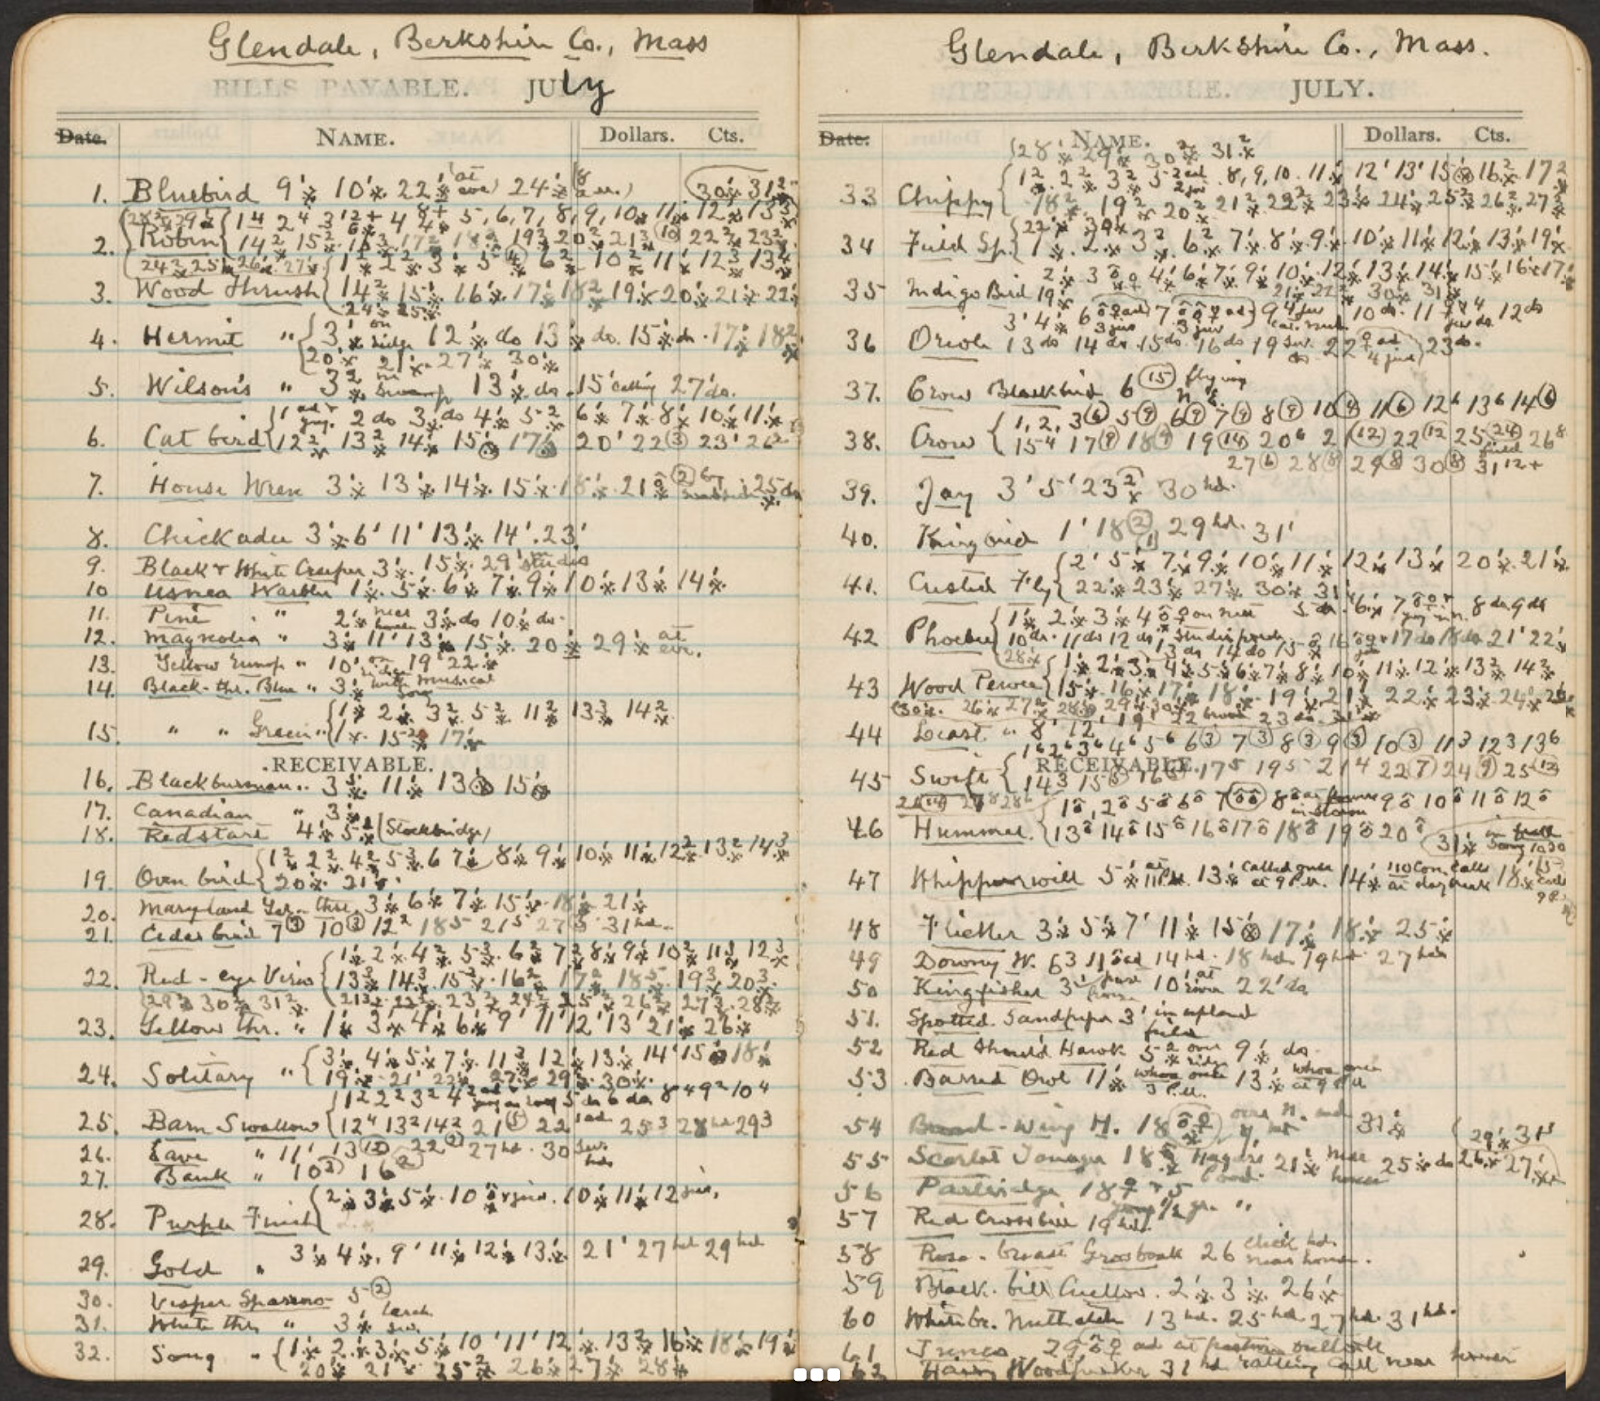
Handwritten list of species observed by William Brewster

Figure 4. Brewster’s bird observations for July from his 1915 Diary.
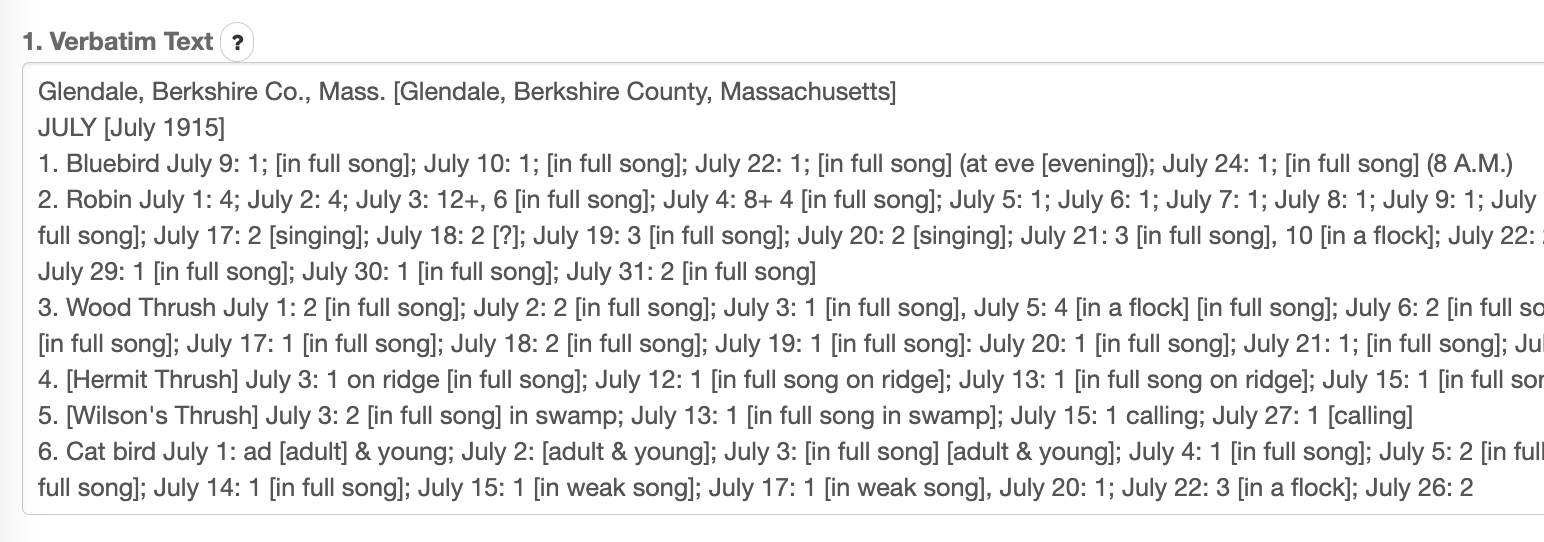
Typed transcription of the handwritten species list from William Brewster

Figure 5. A portion of the transcript of Brewster’s July, 1915 species list.

Extracting Data via Citizen Scientists and DigiVol

DigiVol, first developed in 2011 to crowdsource the transcription of specimen labels, enables institutions around the world to engage volunteers to extract data of various types, such as text, species identifications, and species traits from images. Each institution is able to upload images and manage their crowdsourcing project through the DigiVol platform. Through a combination of gamification and engagement tools such as a user forum and secure, private emails, institutions can build volunteer skills, a sense of community, and commitment.
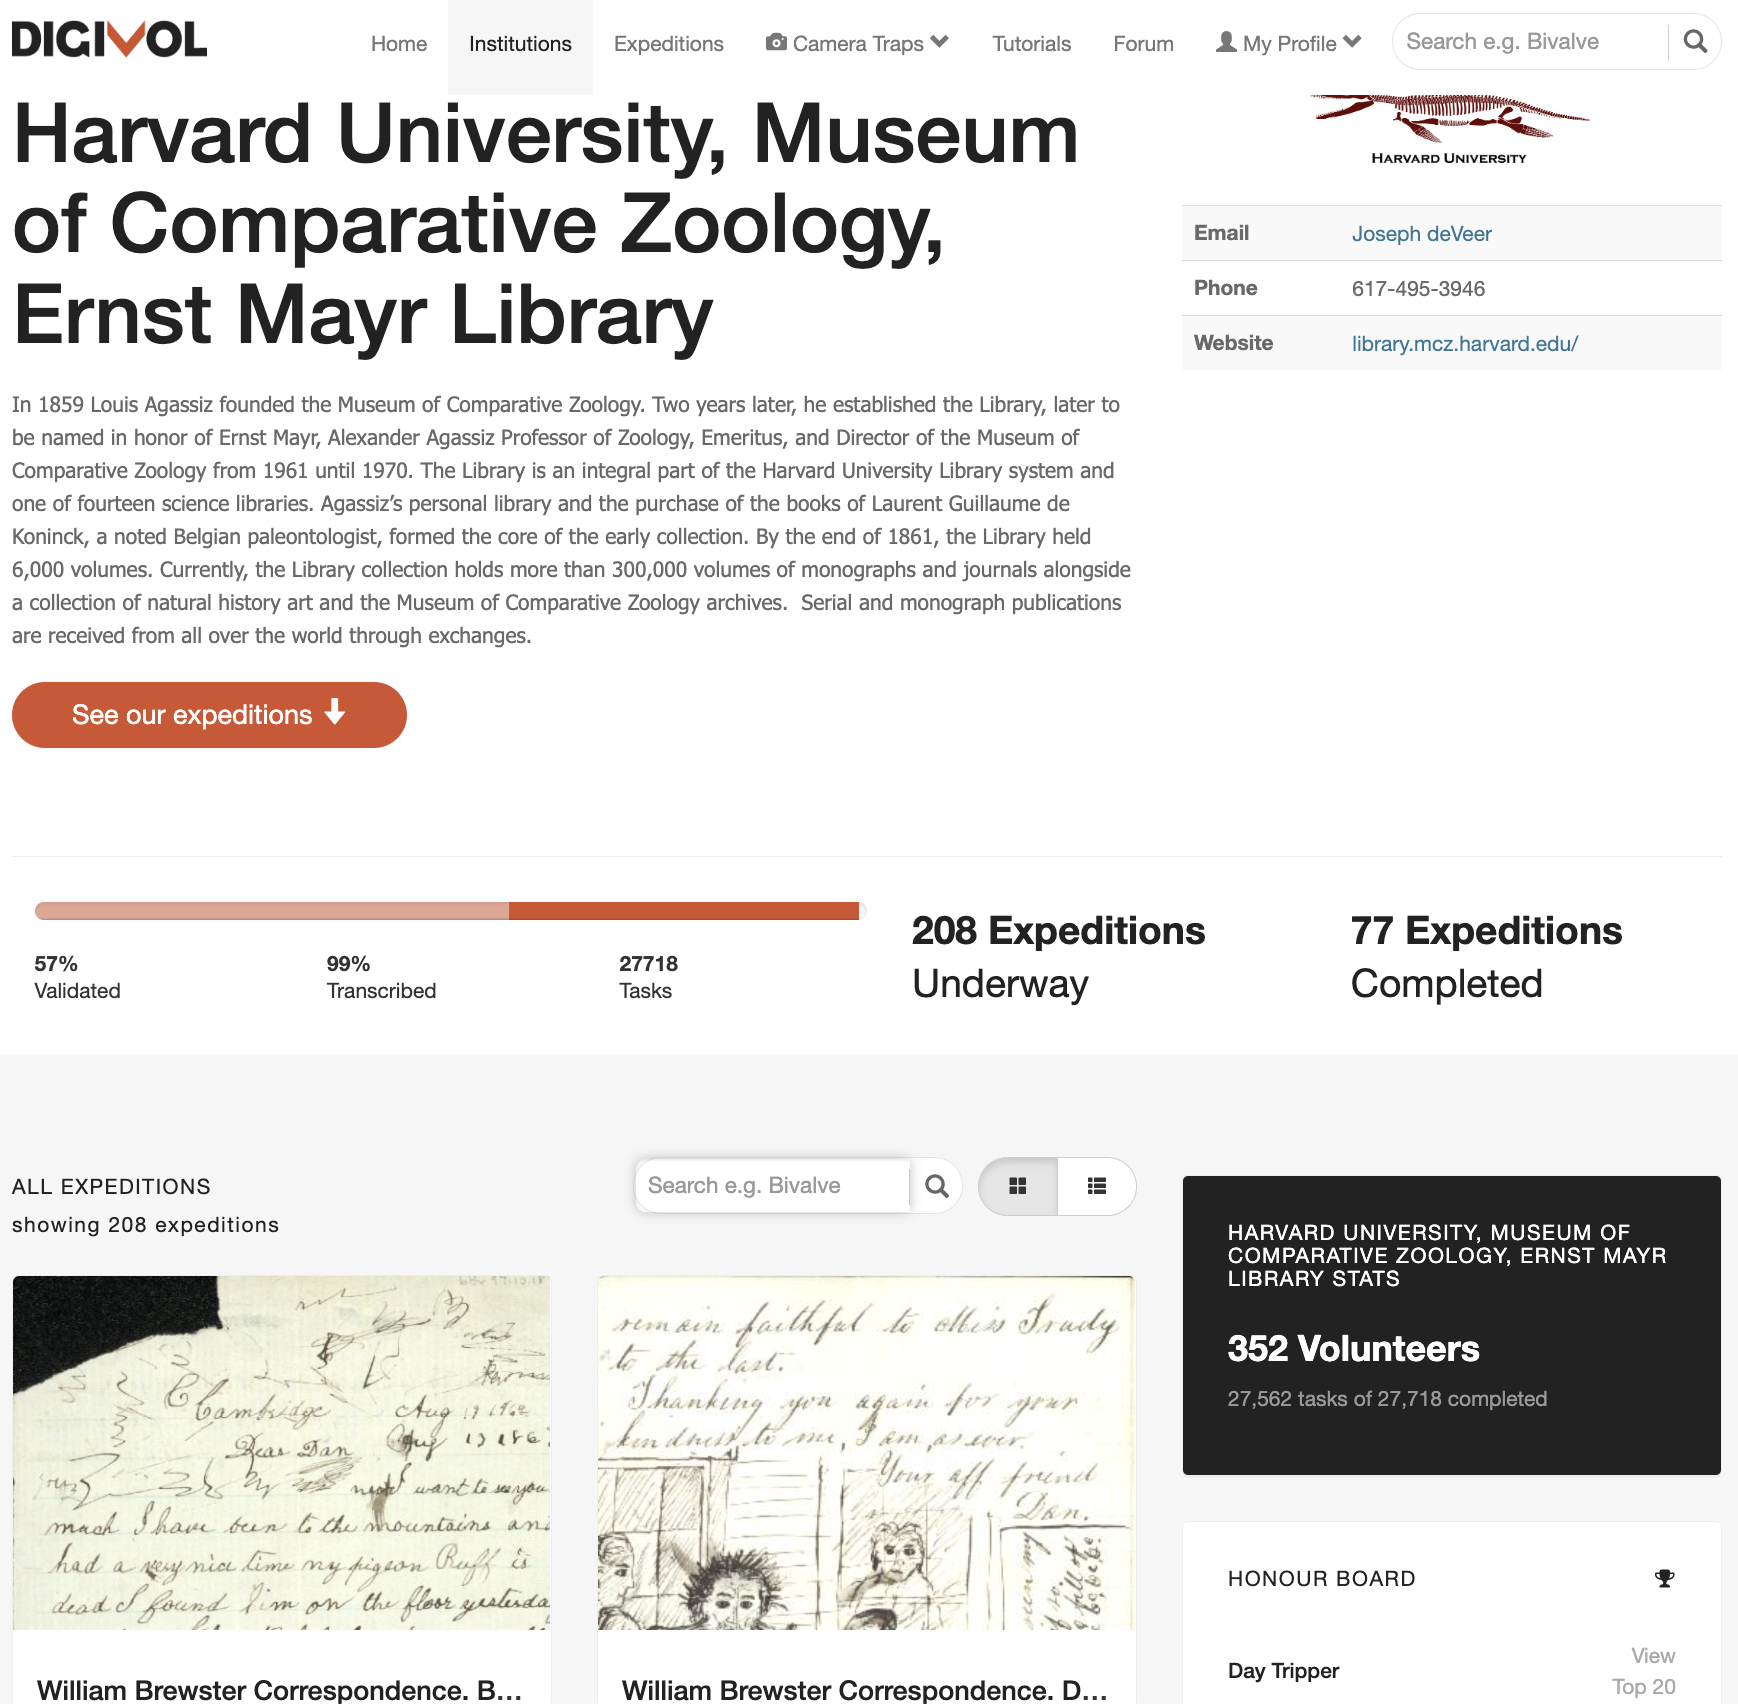
Screenshot of the Harvard University, Museum of Comparative Zoology, Ernst Mayr Library transcription portal on DigiVol platform, listing the number of expeditions and volunteers

Figure 6: The DigiVol dashboard for the Harvard Museum of Comparative Zoology, Ernst Mayr Library.

Volunteers on the website can contribute any time of day – 24/7, 365 days a year. They can choose from a broad array of “virtual expeditions” on DigiVol, from identifying animals in camera traps located in the Australian “bush” to transcribing specimen labels and field notes from locations around the world.

The DigiVol platform has seen more than 14,000 volunteers contribute 155 equivalent work years (7 hour days, 261 days a year) to the digitisation of over 6 million tasks at an estimated equivalent value of A$12 million.

In terms of the William Brewster project, 352 volunteers have transcribed over 27,000 pages of diaries and field notes, at an average 23 minutes per page. This contribution amounts to more than 5.8 work years at an equivalent cost of A$462,000.

Publishing Data to GBIF

The final output of these recent data pipeline investigations was the deposit of 1,853 species occurrence records at GBIF from the Journals of William Brewster. The data deposit comprises valuable biodiversity records extracted through transcription efforts on DigiVol, transformed into DarwinCore, and subsequently published on GBIF. The species occurrence records span diverse geographical locations, primarily focusing on New England but extending to other regions of the United States, the Caribbean, and Europe. Brewster’s meticulous observations, encompassing species observation, behavioral data, and environmental conditions offer a rich historical perspective on biodiversity dating back over a century.
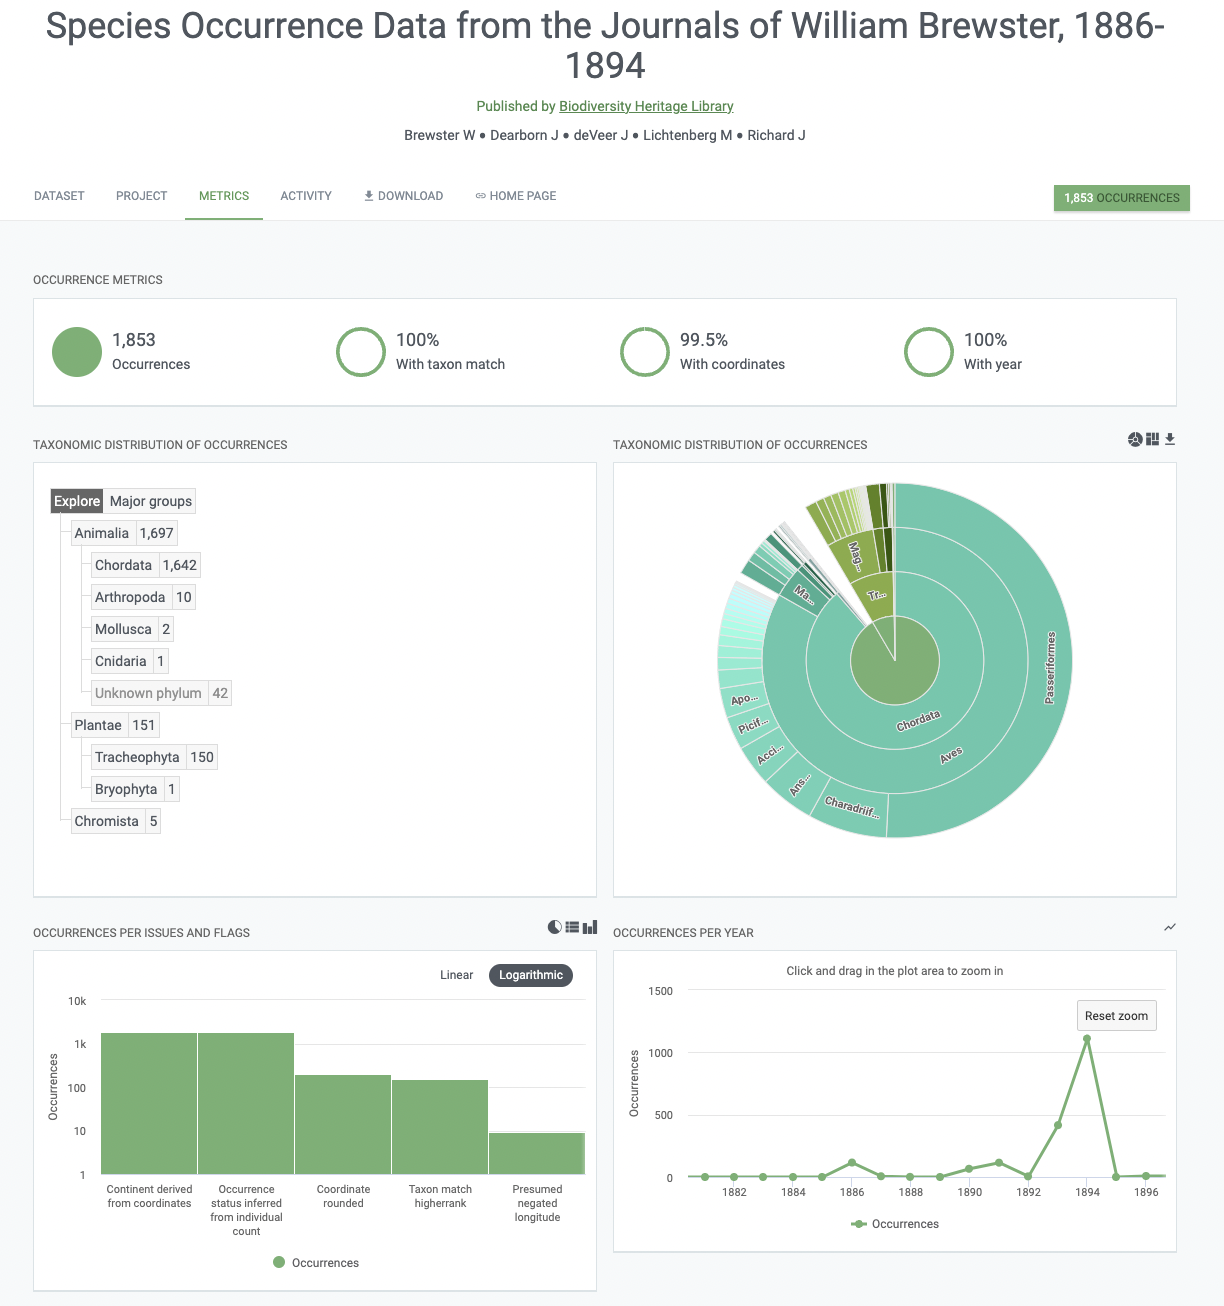
Visualizations of species occurrence data deposited in GBIF from the journals of William Brewster

Figure 7: Species Occurrence Data from the Journals of William Brewster are now available on GBIF. Additional data deposits are planned in 2024. Data deposit: https://doi.org/10.15468/q45atb

This deposit of historic biodiversity data demonstrates how valuable BHL’s collection is to global biodata infrastructure, as it plays a crucial role in establishing species base lines, informing climate change studies, tracking key environmental indicators, and contributing to the development of global biodiversity monitoring platforms.

Having the data available in BHL, even as transcribed text is one thing, but it is the human resources to review and reconcile the data that is really required to facilitate the flow of historic biodiversity data into today’s bioinformatics ecosystems. To all the humans involved in this species data project, from the initial observation and recording, to the preservation, digitization, transcription, data extraction and reconciliation, machine-learning, and creation of vital ETL data pipelines, we thank you.


Related Works

Biodiversity Heritage Library Open Data Collection. (2022, November). Smithsonian Figshare.

Crowley, B., Dearborn, J., Funkhouser, C., Kalfatovic, M., Merriman, K., Iggulden, D., Trei, K., & Herrmann, E. (2023, October). Safeguarding Access to 500 Years of Biodiversity Data: Sustainability Planning for the Biodiversity Heritage Library [TDWG2023]. Biodiversity Information Standards, Hobart, Tasmania, Australia.

Data Flows Diagram. (2023, March). BHL Technical Team (BHL-TECH) Biodiversity Heritage Library.

Dearborn, JJ (2023, April). Unifying Biodiversity Knowledge for Life on a Sustainable Planet. Biodiversity Heritage Library. https://bhl.pubpub.org/

deVeer, J. (2021, February 24). Making the Best of Difficult Times: Accelerating the Transcription of William Brewster’s Writings During the COVID-19 Pandemic. Biodiversity Heritage Library.https://blog.biodiversitylibrary.org/2021/02/accelerating-transcription-brewster-covid19.html

deVeer, J. and Rinaldo, C. (2021, February 23). The Life and Work of Robert Alexander Gilbert: Empowering New Insights through Digitization and Transcription of Archival Materials. Biodiversity Heritage Library. https://blog.biodiversitylibrary.org/2021/02/life-work-robert-gilbert.html

Henshaw, Henry W. 1920. In Memoriam: William Brewster, Born July 5, 1851 – Died July 11, 1919. The Auk 37, 1 (1920), 1–23. https://doi.org/10.2307/4072953

Lichtenberg, M. (n.d.). BHL Data Model. BHL Github Repository. https://github.com/gbhl/bhl-us/tree/master/Documentation/DataModel

Mika, K. and Dearborn, J. (2022). [poster] Extracting expedition log data found in the Biodiversity Heritage Library. Through the door and through the web: releasing the power of natural history collections onsite and online, June 5, 2023. Edinburgh, Scotland, United Kingdom: Society for the Preservation of Natural History Collections (SPNHC). https://doi.org/10.5281/zenodo.6593457.

Richard, J. (2022, December 20). OCR Improvements: An Early Analysis. Biodiversity Heritage Library. https://blog.biodiversitylibrary.org/2022/07/ocr-improvements-early-analysis.html

Rinaldo, C. (2021, February 22). Nature Conservation and William Brewster: Insights From a Lifetime of Scientific Observations. Biodiversity Heritage Library. https://blog.biodiversitylibrary.org/2021/02/william-brewster-post-one

Trizna, M., & Dearborn, J. (2023, June). AI models are getting better and better at reading handwriting, but how can we find handwritten text to begin with? [poster]. 7th Annual Digital Data Conference, Leveraging Digital Data for Conservation, Ecology, Systematics, and Novel Biodiversity Research, Tempe, Arizona, United States of America. https://doi.org/10.25573/data.23523495.v1
November 9, 2023by mdimeo
Blog Reel, Tech Updates

OCR Improvements: An Early Analysis

Color coded comparison of OCR text highlighting the differences in text recognition

Optical character recognition (OCR) plays a critical part in BHL’s contributions to the scientific community. OCR in and of itself is a remarkable achievement, converting images of typewritten text to computer-readable text with “pretty good” accuracy. OCR on handwritten text is an even greater challenge to address and is beyond the scope of the improvements discussed here. The scientific work that BHL supports demands the best accuracy that we can provide using available tools, and let’s be honest, available budgets.

Recently, our colleagues at the Internet Archive made the transition away from the ABBYY FineReader OCR software to the Tesseract Open Source OCR engine. Over the past year or more, the OCR team at the Internet Archive has adapted and fine-tuned Tesseract to their workflows. Our first impression is that Tesseract OCR is more than “pretty good” in its ability to identify text from the page images provided to it.

The downside to this is that the Internet Archive has rightfully chosen to not re-process all existing text content through the Tesseract OCR engine. This is a prohibitively expensive and time-consuming prospect given that they have 35 million text-based items and reprocessing them would take several years and use up resources that could otherwise be used for gathering new content.

However, in the interests of supporting the efforts of the BHL community, the BHL Tech Team is working with our Internet Archive partner to reprocess some of BHL’s oldest content with the newest available version of Tesseract OCR. We are currently in a testing phase, and this blog post details some of our early results.

Selection

The first step in the process was to identify which versions of which OCR engine was used on BHL’s content. This was a simple matter of checking the “OCR” metadata value at the Internet Archive for each of the 263,000 items at BHL. The results as of December 2020 were:

“OCR” Metadata Value Count
ABBYY FineReader 8.0 80,447
ABBYY FineReader 9.0 35,276
ABBYY FineReader 11.0 45,679
ABBYY FineReader 11.0 (Extended OCR) 49,086
Tesseract 4.1.1 83
No OCR value  39,530

We suspect that those items with No OCR value are the very oldest content at BHL and were processed with an unknown OCR engine, or ABBYY FineReader 8.0 or earlier.

For a test and ultimately for moving forward with reprocessing, we chose the 80,000 items with ABBYY FineReader 8.0. We will likely add the other 39,500 items with No OCR value.

The Process

The steps to reprocess the OCR for an item are simple. We delete a few critical files at the Internet Archive and issue a “derive” command to restore them. In doing so, the OCR is regenerated and the “OCR” metadata value is updated accordingly.

The challenging part of the process is time and resources. OCR is a computationally expensive process and it can take dozens of minutes to several hours to create the OCR for a single Item. We also must be aware that we can potentially take computing resources from other activities at the Internet Archive, so we issue the “derive” command at a lower priority than other Internet Archive activities, effectively using up spare or unused resources as they are available.

In other words, we’re being good citizens of the Internet Archive ecosystem.

The Results

Since this is what you came for, in summary, the results are very good and this is a worthwhile effort.

Our tests for evaluating the results are a combination of visual inspection and computational analysis. For backup and local analysis purposes, BHL keeps a copy of all content at the Internet Archive, but its updates are currently disabled during this testing phase. Using this backup copy as the source of “old” content, we can compare it to the “new” content at the Internet Archive.

Analysis 1: Misspellings

The first analysis is to simply check for misspelled words. While at first glance this seems too simplistic, OCR operates on a letter-by-letter analysis of the text and often has challenges correctly identifying a letter and will often produce invalid words.

Using the Linux aspell tool, we can find misspelled words and count them using a command such as the following:

cat FILENAME | aspell list | wc -l

This command sends the contents of FILENAME to aspell, which lists misspelled words, one per line, then sends that list to the word-count wc command to list the number of lines. Using a test case of 1955seventyoneye1955harr, we count the misspellings for the old and new versions:

  • Old OCR Text (from 2013): 2,357 misspelled words
  • New OCR Text (from 2020): 1,639 misspelled words

There are expected commonalities between the two lists of misspelled words. Proper or scientific names such as Elberta and Harrison or varietal names such as Dixired or Redhaven don’t exist in the standard English dictionary. Additionally, legitimate misspellings in the printed text appear, such as Recomemnded, appear in the results. Regardless, the greatly reduced number of misspellings is a good indicator of OCR accuracy. 

Analysis 2: Visual Inspection

One of the most important downstream effects of improved OCR is improved identification of scientific names. BHL partners with the Global Names Architecture (GNA) to identify scientific names in the BHL text. Focusing on this, we can see that improvements in the OCR reveal more scientific names that were missed in the past.

Example A: Ligustrum ovalifolium

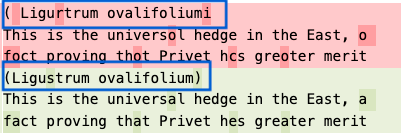
The original page image at BHL discusses the California Privet (Ligustrum ovalifolium).

The OCR comparison of the old engine (in red) and the new (in green) shows that the new Tesseract OCR engine was better able to convert the words to text. This will ultimately cause this name to appear in BHL’s list of scientific names on this page of the document where currently it may not appear.

Color coded comparison of OCR text highlighting the differences in text recognition

Example B: Multiple names

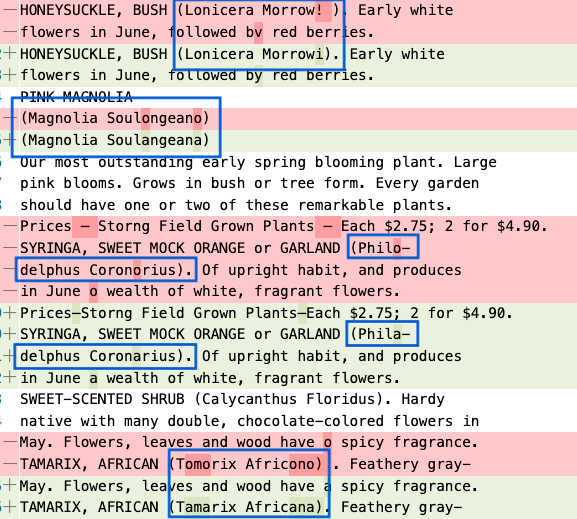
A second example showing numerous taxon names that are now correctly identified by the OCR. It’s worth mentioning that this page in BHL includes the genus (Magnolia or Lonicera) but not the full species name. We expect that the full name will appear in BHL with the improved OCR.

Color coded comparison of OCR text highlighting differences in text recognition

Analysis 3: Scientific Name Finding

As mentioned earlier, BHL partners with the Global Names Architecture (GNA) to identify scientific names in the OCR content of BHL. While we use APIs to perform this function, GNA also offers a command line tool to process a body of text to identify scientific names.

Similar to counting the misspelled words, we use a series of Linux commands to process the OCR text and count the scientific names found in the text.

gnfinder find FILENAME  -c -s 1,3,4,9,11,12,167,172,179,181 |
  jq '.names[] .verification.BestResult.matchedName' | 
  sort | uniq | wc -l

gnfinder is the command to find the scientific names. This command returns JSON content, which we then send to the jq command to count the number of BestResult.matchedName elements in the JSON. Then we sort, get the unique names, and count them with wc. A sample of the JSON output looks like:

{
  "type": "Uninomial",
  "verbatim": "(Lonicera",
  "name": "Lonicera",
  "odds": 93678.22872366496,
  "annotation": "",
  "verification": {
    "BestResult": {
      "dataSourceId": 1,
      "dataSourceTitle": "Catalogue of Life",
      "taxonId": "4091239",
      "matchedName": "Lonicera",
      "matchedCanonical": "Lonicera",
      "currentName": "Lonicera",
      "classificationPath": 
        "Plantae|Tracheophyta|Magnoliopsida|Dipsacales|
           Caprifoliaceae|Lonicera",
      "classificationRank": 
        "kingdom|phylum|class|order|family|genus",
      "classificationIDs": 
        "3939764|3942634|3942724|3942969|3942971|4091239",
      "matchType": "ExactMatch"
    }
  },
  [...]
}

Counting these for our example 1955seventyoneye1955harr, we find:

  • Old OCR Scientific Names: 20 unique names found
  • New OCR Scientific Names: 38 unique names found

This is a simple case indicating that an additional 18 unique names were found in the content. Taking a random sample of 10 other items shows the following larger differences in the number of unique scientific names found:

Item Identifier Unique Names Found in OCR
Old New
guidebooksofexcu03inte 190 190
dissectionofdoga00howe 23 25
ueberliasbeta00schl 38 55
mobot31753003413330 641 920
CUbiodiversity1249031-9750 1,042 1,244
annalesdelasoci2627188283soci 2,786 3,046
weiterebeobachtu00kl 59 62
verhandlungender42zool 2,487 2,806
etudedesfleu1865cari 1,077 1,148
bulletinbiologiq47univ 750 1,127

It is worth noting that a visual inspection of these names indicates there is some fine-tuning remaining. gnfinder identifies both binomial names (genus and species) and uninomial names (genus only) in the content. There look to be instances where names are found in the new OCR that don’t exist in the content, but are incorrectly being identified as uninomials. gnfinder provides a type of score that must be fine tuned for the new OCR in order to reduce this effect. This is a task for future discussion.

Summary

While there is further work to do in loading this new content into BHL and in the scientific-name-finding part of the process, these initial results are encouraging and are enough to help us make the decision to continue reprocessing the OCR using the Internet Archive’s installation of Tesseract OCR.

This journey is years in length. Even if we were to process at the highest priority (something we would never consider), we are planning to affect nearly half of BHL’s 263,000 items. Our current rate of progress at the aforementioned lower priority is approximately 100 items per day. At such a pace, the 120,000 items will take three years to complete.

Future blog posts will occur as there are more updates to share with the BHL community.

July 19, 2022by Sheila Rabun
Blog Reel

How’s your fern and bird coverage, BHL?

“Every one knows what a bird is,” asserts an early 20th century book that I found while browsing the Biodiversity Heritage Library (BHL).

As I’ve learned during my Professional Development Internship with Jacqueline Chapman at Smithsonian Libraries this summer, it’s not always that simple. Taxonomy is ever-changing, especially at the granular level needed by subject specialists around the world who use BHL to conduct research on organisms ranging from mosses to turtles to fungi.

BHL is a consortial digital library whose member libraries digitize works in natural history and botany based on both user requests and subject librarians’ selections. My project for this summer was to refine a collection assessment methodology for BHL using both taxonomic and bibliographic analyses. Along the way, I’ve learned valuable lessons in using library tools, troubleshooting in Python (a computer programming language), and understanding the thought processes of 19th century ornithologists and pteridologists.

View Full Size Image
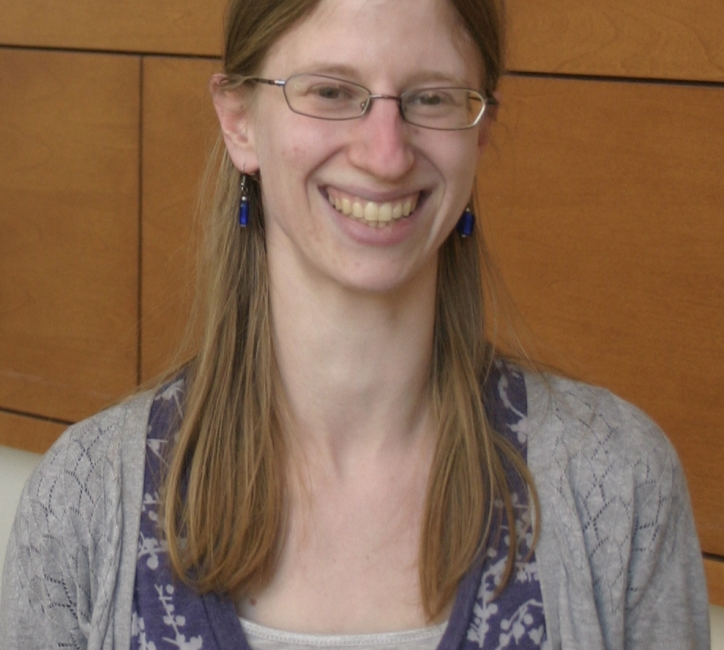
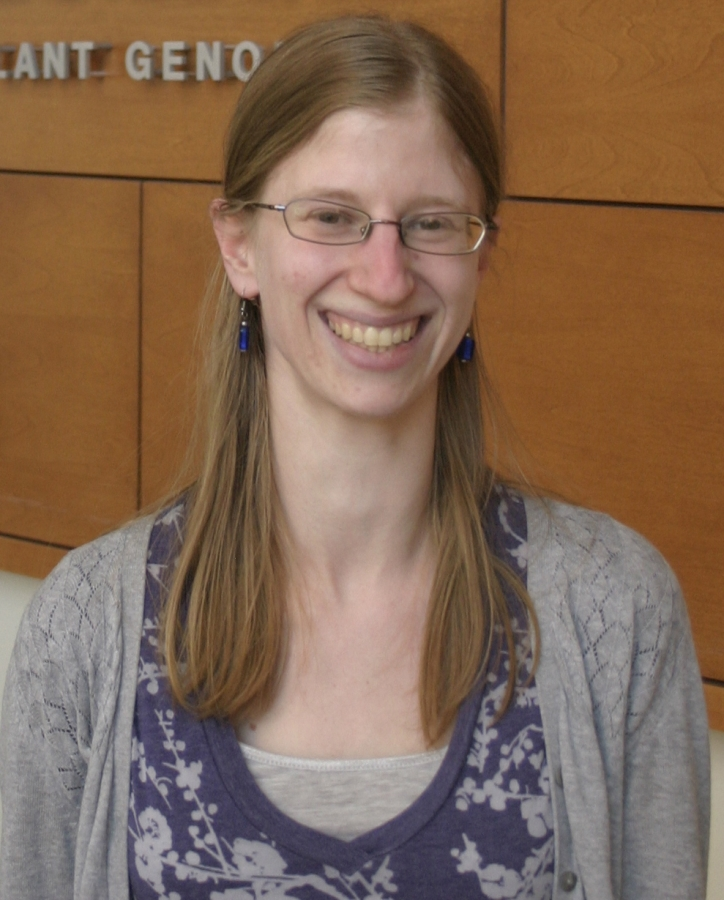
Becca Greenstein

Last year, Jacqueline worked with Robin Everly, the Smithsonian’s Botany and Horticulture Librarian, to conduct a taxonomic and bibliographic analysis to assess the depth of the BHL’s fern and lycophyte literature. They presented their results at an international conference on ferns, Next Generation Pteridology, and had the unique ability to talk with many subject-specialist users from around the world. Jacqueline later shared this proof-of-concept with researchers at TDWG in Nairobi, Kenya.

For the bibliographic portion of the project, Fern Books and Related Items in English before 1900 was used to create a list that could be referenced to determine whether a book was available on BHL, and if not, if we had access to it. A year later, I furthered this analysis by seeing what has changed in the past year and making requests for partner libraries to scan items to add to the collection. I enjoyed gathering data for books with titles such as Greenhouse Ferns and the Romance of Plant Life, Rambles in Search of Ferns, and The Fern Paradise: A Plea for the Culture of Ferns (2nd edition in BHL).

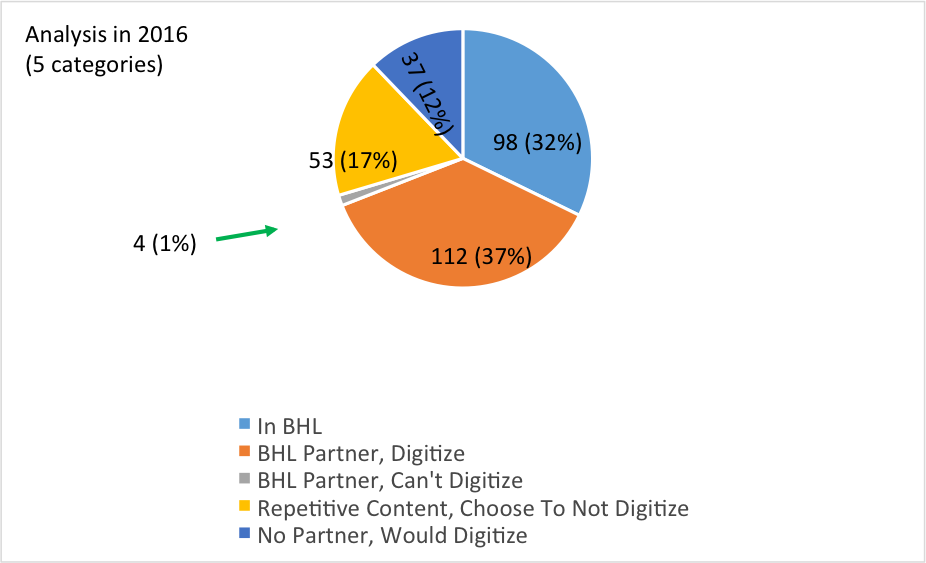
As the bibliography used included all editions of a particular work, regardless of whether the content had changed, I decided to not digitize the 53 works on the list whose content was already in BHL in another edition of the same work. As you can see in the graphs below, the number of fern books on BHL from this list has increased by 36% over the past year. The 112 titles from the list that are not yet in BHL but that we have access to via partner libraries will be in BHL after they are digitized. We lack access to only 37 of the titles on the list that would add content to BHL, and it will be interesting to follow up with this study to see if current partners acquire new resources or if new partners that possess these materials join the BHL Consortium.

View Full Size Image
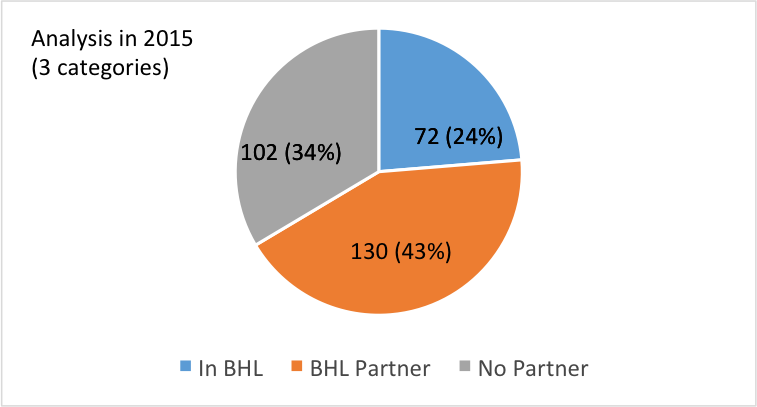
2015 Bibliographic Analysis: Graph presents percentage of books from the list generated using Fern Books and Related Items in English before 1900 that are in BHL, are not in BHL but are held by a BHL partner, and are neither in BHL nor held by a BHL partner.
View Full Size Image
2016 Bibliographic Analysis, showing that the BHL collection of fern books has increased from 2015 to 2016.

For the taxonomic portion of the project, BHL’s coverage of a particular taxonomic grouping using scientific names was analyzed. The digitized material on BHL is in the form of images, which the computer does not recognize as text. Using Optical Character Recognition (OCR), the images are converted to machine-readable text. Taxonomic Name Recognition (TNR) then searches the OCR to find scientific names using multiple recognized lists of scientific names.

To use this powerful analytical tool to analyze BHL’s literature on birds, I upgraded the Python 2 code used for last year’s analysis to Python 3, the newest version of the programming language. Using my code, I counted the number of mentions in BHL of each genus of birds that appear in Catalogue of Life, as determined by TNR, to identify potential gaps in the BHL collection.

Of the 2234 genera analyzed, 99.6% of them are mentioned in the BHL corpus, 131 individual genera had more than 10,000 mentions in BHL, and 88% of them had more than 100 mentions.

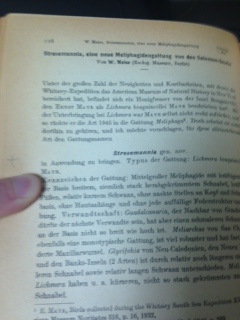
I conducted an in-depth analysis of the 37 genera with fewer than ten mentions in BHL to figure out possible reasons for the paucity of literature. I determined that this lack of literature could be attributed to such things as the more-recent description of some of the genera, such as within the past 20 years, to the locality of some genera, as in some birds being endemic to far-away (to 19th century European ornithologists) places like New Guinea and Mozambique, and to taxonomic changes to the genera over the years. I then looked for the first mention of each of the 37 genera in books and journal articles online and in print, in addition to submitting scan requests for the books we have access to that weren’t already in BHL. There was something surreal about trekking up to the Birds Library, which is tucked away on the sixth floor of the National Museum of Natural History, finding Ornithologische Berichte on the shelf (and no, I don’t speak German), and opening to page 118 to find Wilhelm Meise’s initial description of Stresemannia bougainvillea.

View Full Size Image
Meise’s initial description of Stresemannia bougainvillea is next to my thumb.

My internship lasted six weeks, but it did not feel like that long. I hope that BHL will use my code to analyze larger sets of data and/or data at a higher level (for example, how is BHL doing at collecting literature on Kingdom Animalia?).

Through conducting my project, I’ve learned that things you learn in library school really do apply to the real world, how an academic library at an institution without students functions, and the workflow behind digitizing materials that appear in BHL and on the Smithsonian Digital Library. I’ve learned that library tools we take for granted can be unreliable, but aren’t usually, and that getting help from people who do research on ferns and those who do speak German can be very beneficial. I hope to bring the things I’ve learned back to my final two semesters of library school, as well as into my hoped-for career as a science librarian after I graduate.

________________________

About the Author

Becca Greenstein is getting her Master’s in Library Science at UNC-Chapel Hill. For her Bachelor’s degree, she went to Carleton College, where she majored in Biology and minored in Chinese. After graduating from Carleton, she worked as a lab technician at the University of Minnesota before starting library school. After she graduates, she hopes to continue honing these skills while working in an academic or special library as a science librarian.

August 23, 2016by ulib-libraryjobs
Blog Reel, User Stories

Original Publications at our Fingertips

Systematics is the branch of biology concerned with classification and nomenclature. It is sometimes used synonymously with taxonomy.

In their 1970 publication Systematics in Support of Biological Research, Michener et al. defined systematic biology and taxonomy as:

Systematic biology (hereafter called simply systematics) is the field that (a) provides scientific names for organisms, (b) describes them, (c) preserves collections of them, (d) provides classifications for the organisms, keys for their identification, and data on their distributions, (e) investigates their evolutionary histories, and (f) considers their environmental adaptations…Taxonomy is that part of Systematics concerned with topics (a) to (d) above.

Identifying species, their relationships and evolutionary hierarchies, is critical to saving biodiversity. Recognizing this, the White House Subcommittee on Biodiversity and Ecosystem Dynamics declared systematics a research priority essential to ecosystem management and biodiversity conservation and identified improvements in the organization of, and access to, standardized nomenclature as a priority within the field.

ITIS (Integrated Taxonomic Information System) was established to address this priority.

View Full Size Image

A partnership of federal agencies (including BHL members the Smithsonian, United States Geological Survey, and CONABIO), ITIS is a database containing reliable information on species names and their hierarchical classification, including the authority (author and, in the case of zoological names, date), taxonomic rank, associated synonyms and vernacular names where available, a unique taxonomic serial number, data source information (publications, experts, etc.) and data quality indicators for each indexed scientific name. Among other applications, ITIS classifications are used as a taxonomic backbone for the Encyclopedia of Life, to which BHL also provides primary source materials such as publications and illustrations.

Dedicated ITIS working groups ensure that the system is designed and continually developed to meet user needs and that the information contained within is valid, thorough, and regularly updated with classification revisions and new species information. Ensuring such a high level of data quality requires extensive research and access to a wealth of primary natural history information.

View Full Size Image
Sara N. Alexander, Data Development Specialist for ITIS.

Sara N. Alexander is a Data Development Specialist for ITIS, stationed at the Smithsonian National Museum of Natural History. With a background in taxonomic botany and the benefit of six years working for the National Herbarium, Alexander joined ITIS five years ago to work with botanical data and has since branched out to proofread zoological taxonomic files.

For her work, Alexander requires access to historic taxonomic information, which is contained within the pages of natural history literature…literature which is made freely available on the Biodiversity Heritage Library.

“I rely on BHL for my daily work; it streamlines taxonomic research immensely,” applauds Alexander. “I am fortunate to have access to multiple libraries in the Smithsonian’s National Museum of Natural History, but even so without BHL I would spend lots of time traveling back and forth to the libraries, scanning pages and making photocopies, waiting on interlibrary loans, and sending emails to taxonomic specialists. With BHL, not only do I have access to original and old literature, but I can easily include a stable and precise link in an email or on a website to allow coworkers to check the accuracy of my work, specialists to answer tricky questions without the burden of hunting down the physical literature themselves, and ITIS users to see the basis of our taxonomic information.”

While she primarily uses BHL to locate the original publication of a name or to find accurate bibliographic information, Alexander has found many additional applications for and points of interest within BHL resources.

“I’ve even occasionally been able to use BHL to discover errors on other online resources on which I rely heavily,” confides Alexander. “For example, I sometimes find a subspecific name published before 1975 that is not yet included in IPNI (The International Plant Names Index). I also enjoy getting ‘sidetracked’ on BHL to read early descriptions of ‘exotic’ animals and look at full-color plates and engravings.”

When asked to give an example of her use of BHL, Alexander related a project that resulted in extensive augmentation of ITIS records with BHL data.

“For worldwide Chiroptera (bats) I was tasked with double-checking the use of parenthetical authorship (whether a name was originally published in the same genus or a different genus than the genus in which it is treated today), which necessitated finding the originally published name for over 2,000 species and subspecific names,” recalls Alexander. “Many of these names were available through major checklists like Hall’s 1981 The Mammals of North America, but others had to be tracked down individually. The now-loaded ITIS treatment of Chiroptera includes links to 72 literature sources accessed through BHL.”

View Full Size Image
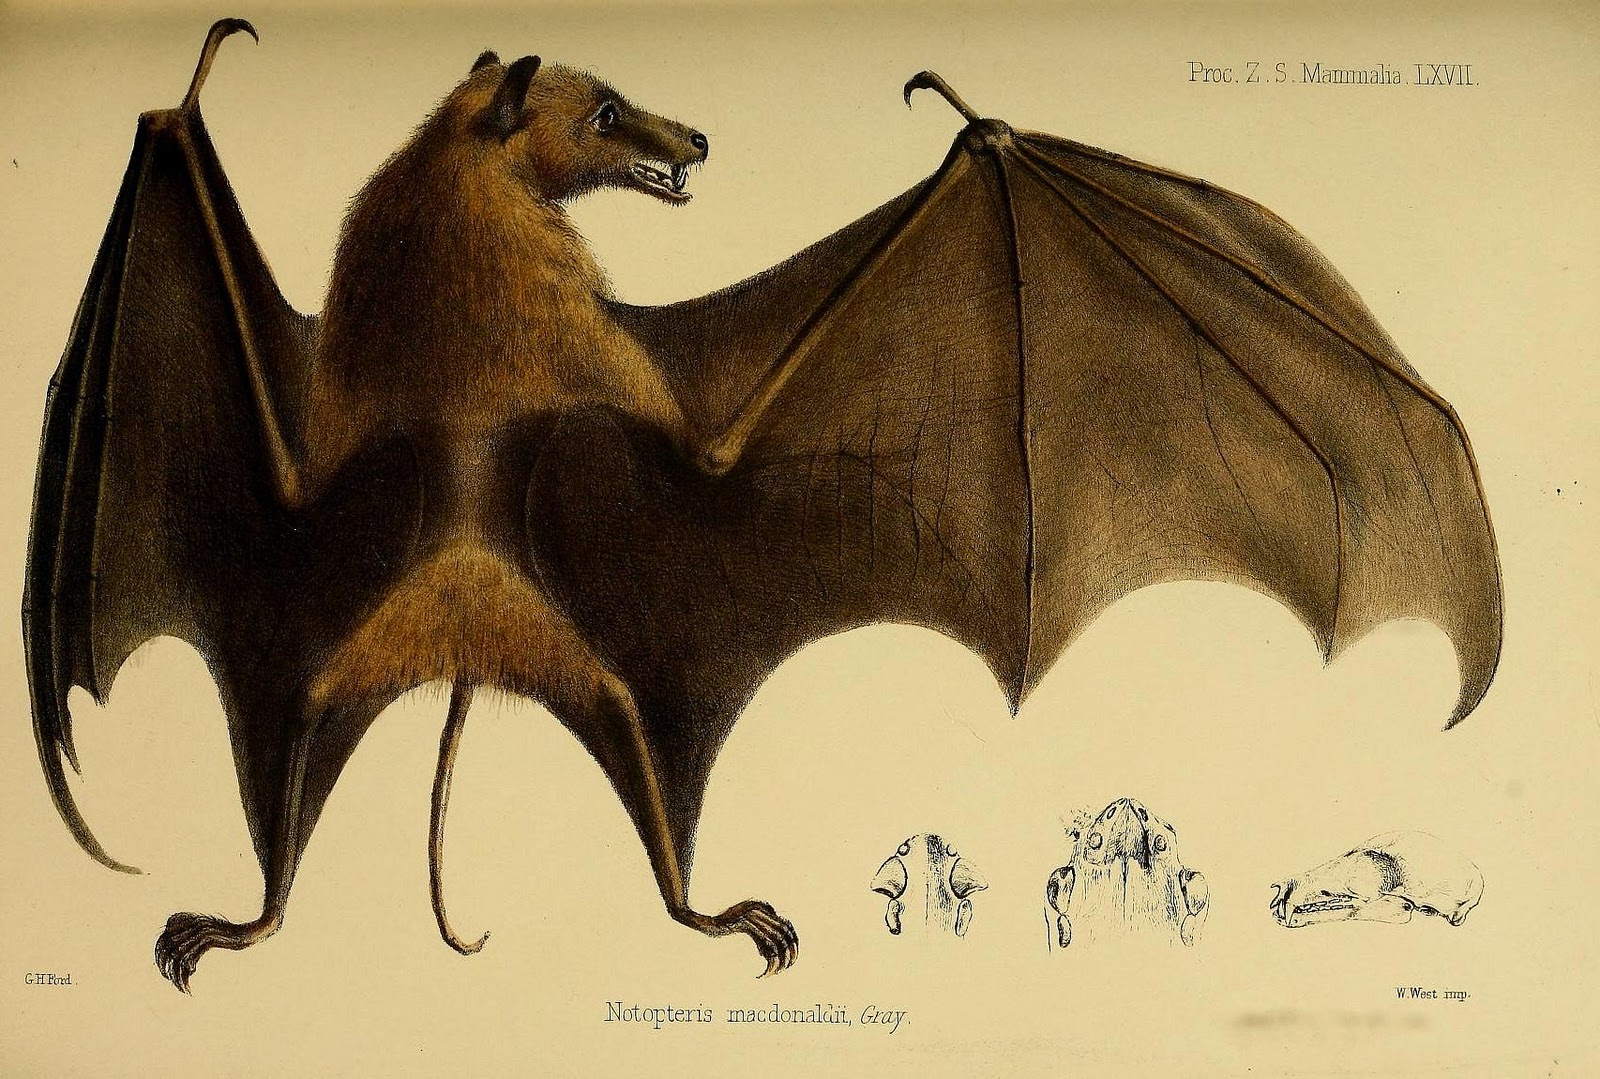
A member (Notopteris macdonaldi) of the Chiroptera, or bat, order, the ITIS treatment for which now includes 72 literature sources accessed through BHL, thanks to Sara Alexander. Proceedings of the Zoological Society of London. v. 1 Plates (1848-60). http://biodiversitylibrary.org/page/37028041.

As her work relies heavily on locating taxonomic names, BHL’s recent initiatives to improve the quality of our OCR, as through the Purposeful Gaming and Mining Biodiversity projects, are of particular interest for Alexander.

“Correcting OCR, and allowing more scientific names to be accurately indexed, will make my work a lot easier. My ideal would be to be able to type in a scientific name and always find its original publication among the returned documents.”

Through the work of dedicated contributors like Sara Alexander and collaboration among multiple agencies, ITIS is significantly advancing scientific research by providing a common framework for and widespread access to taxonomic data that is “fundamental to the description, conservation, and management of the nation’s biodiversity.” The application of BHL data within ITIS demonstrates once again the critical importance of historic, foundational biodiversity literature to modern scientific endeavors. BHL, ITIS, and other open, like-minded biodiversity initiatives are committed to ensuring that everyone, everywhere has the information they need to study, understand, and save the incredible biodiversity on our planet.

We hope you enjoyed this post. Interested in being interviewed for BHL? We’d love that! Email us at [email protected].

January 13, 2015by ulib-libraryjobs
BHL News, Blog Reel

Crowdsourcing and BHL: Current Projects that Allow Users to Help Us Improve Our Library!

Recent crowdsourcing initiatives are revolutionizing scientific research, allowing the public to help scientists and researchers document, identify, and better understand biodiversity.

For example, the Atlas of Living Australia’s FieldData program allows anyone to contribute sightings, photos and observational data to help researchers and natural resource management groups collect and manage biodiversity data. Birds Australia is using this data to help record sightings of Carnaby’s Black-Cockatoo to inform conservation initiatives for this endangered species.

As another example, in 2013 a new mammal species, the olinguito (Bassaricyon neblina), was discovered in South America, the first carnivore species to be discovered in the Americas in 35 years. Scientists at the Smithsonian’s National Museum of Natural History are using citizen science-contributed observational data and photos to learn more about the new species.

BHL has taken advantage of crowdsourcing’s potential, implementing several initiatives to improve access to BHL images, support OCR correction and transcription, and generate semantic metadata for the BHL portal.

Art of Life: Improving Access to Images

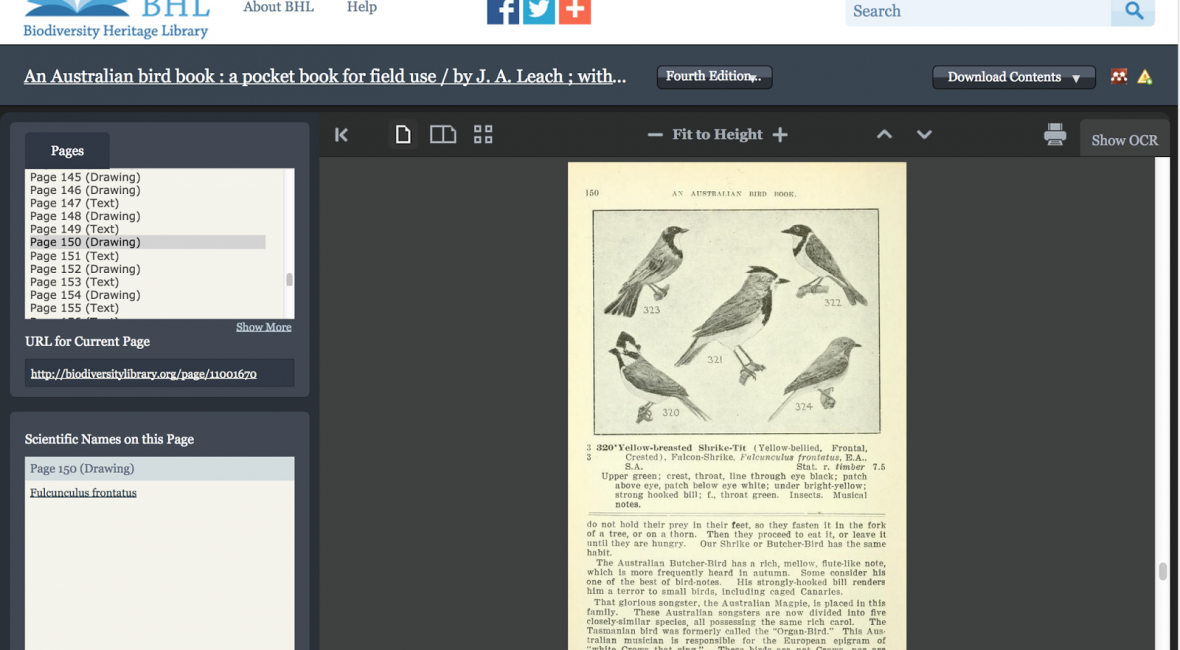
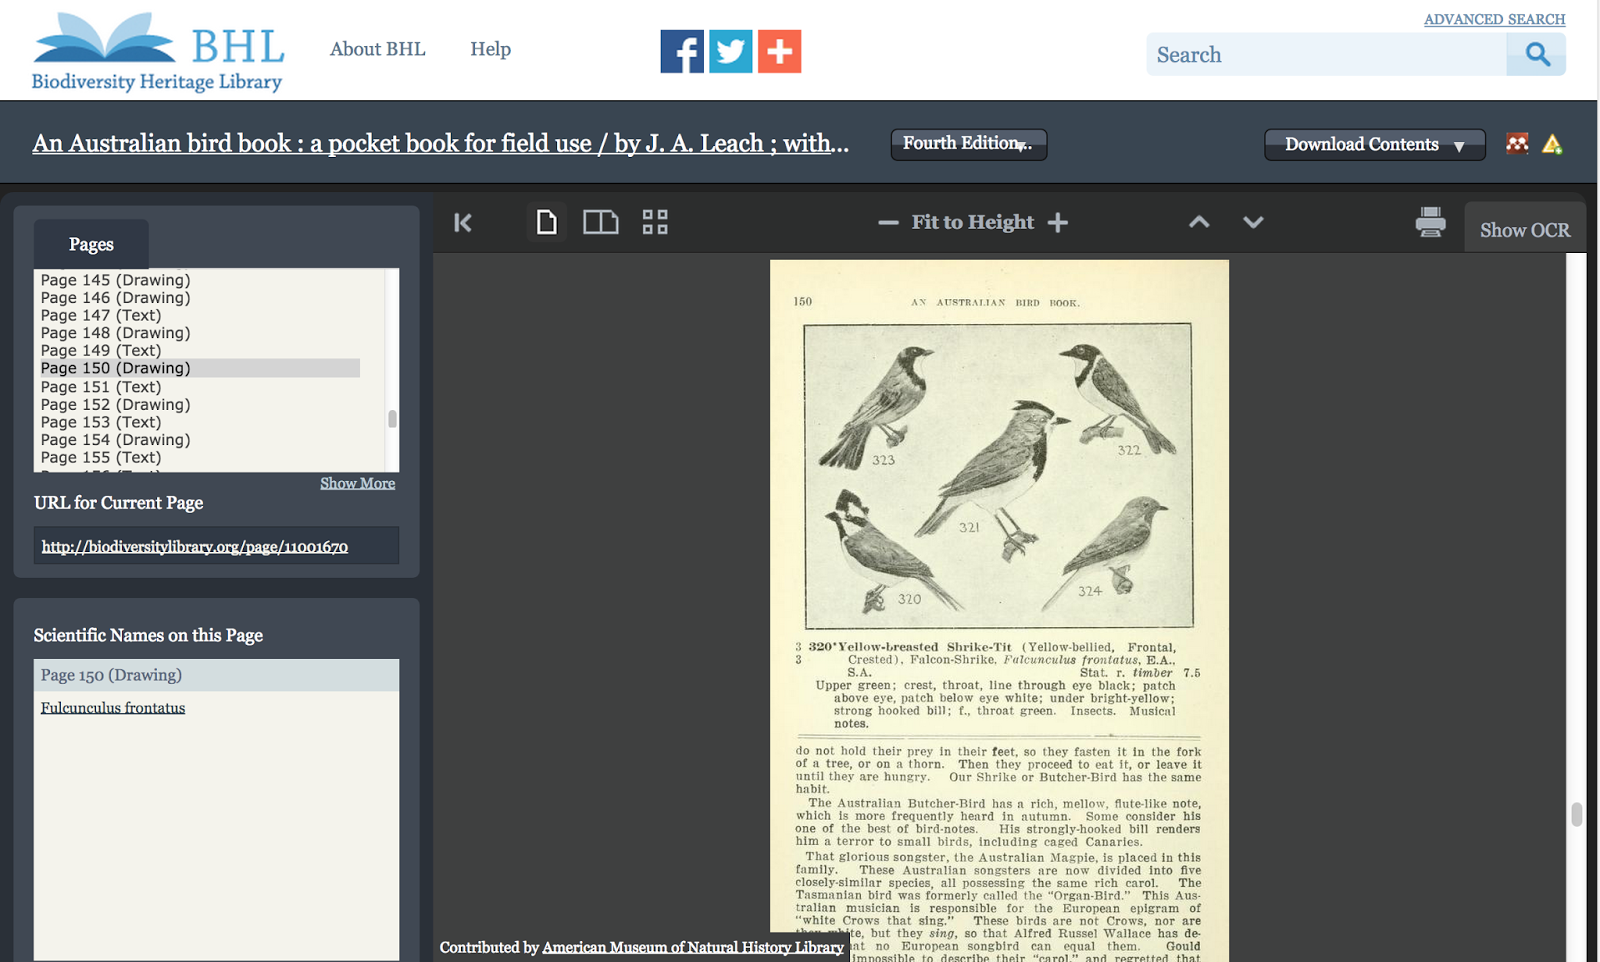
The Art of Life project, funded by NEH and based at the Missouri Botanical Garden, has been making active progress on its objective of improving access to the natural history illustrations within BHL. The image-finding algorithms developed by the Indianapolis Museum of Art Lab have been run across 18 million BHL pages and you’ll now notice a significant increase in the number of pages tagged as having illustrations within the BHL portal. Pages with illustrations are currently being manually classified by volunteers as belonging to one or more image types: drawing, table, photograph, map, and/or bookplate. A few examples in the BHL portal include:

  • http://www.biodiversitylibrary.org/page/11001670
  • http://biodiversitylibrary.org/page/11001551
  • http://www.biodiversitylibrary.org/page/3601565
  • http://biodiversitylibrary.org/page/12284099
View Full Size Image
Example of how metadata now displays descriptive information about the types of images found within BHL pages.

Next steps for the project are to crowdsource descriptions for the image’s content (e.g. subjects, dates, illustrator) through platforms such as Flickr and Wikimedia Commons. Learn more about the Art of Life project, which runs through April of 2015.

Learn how you can help tag BHL’s illustrations in Flickr.

On a related note, we will also be crowdsourcing BHL image descriptions through another platform, Zooniverse, the premier host for citizen science projects. This opportunity came about through a partnership with Constructing Scientific Communities (aka ConSciCom). More details will be forthcoming in a future blog post but expect to see BHL content available in Zooniverse in late spring or early summer of 2015.

Purposeful Gaming and BHL: Playing at OCR Correction and Transcriptions

Another crowdsourcing BHL project called Purposeful Gaming and BHL, funded by IMLS and based at the Missouri Botanical Garden, has been making significant strides in its objective to improve access to BHL texts through gamifying the text correction process. Digital outputs of BHL text are created both through automated (OCR of published text) and manual means (transcription of hand-written text from ornithologist William Brewster). Multiple outputs of the same page are then compared and differences incorporated into an online digital game in which the public will help verify the accuracy of individual words. Those corrections will then be incorporated back into the BHL portal for viewing by users and to enable full text searching. The project’s game designer, Tiltfactor, has recently completed and beta-tested 2 initial prototypes for both gaming and non-gaming audiences. The final games are expected to go live in May 2015. Learn more about the Purposeful Gaming project, which runs through November of 2015.

View Full Size Image
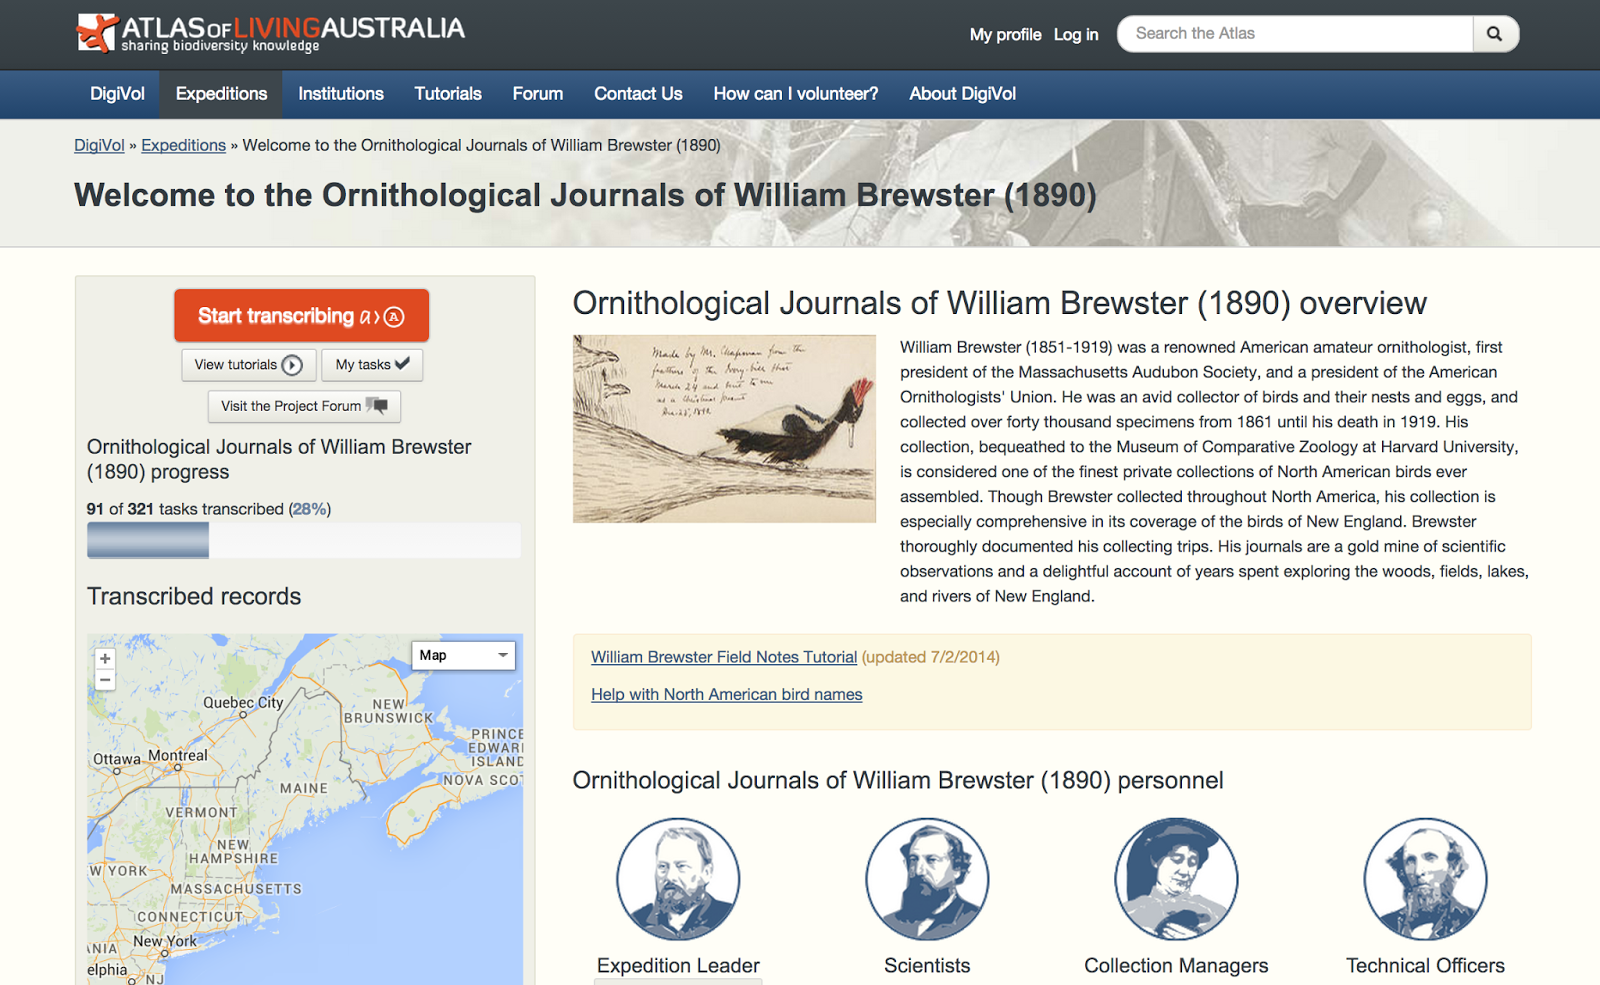
William Brewster’s journals available for transcription in the ALA/Australian Museum Biodiversity Volunteer Portal.

Help us transcribe William Brewster’s journals and diaries in the ALA/Australian Museum Biodiversity Volunteer Portal (click on any of the William Brewster projects listed) and FromThePage! Find guidelines for transcribing the documents here.

Mining Biodiversity: Semantics and the Crowd

In the near future, the Mining Biodiversity Project, whose USA partners’ participation is also funded by IMLS, will be crowdsourcing the creation of a gold standard annotated set of pages to train the mining algorithms that will search for named entities (ie. concepts like taxa, places, people, habitat, traits). After that, a bigger group of volunteers will help validating the pre-annotated relations through time (events) automatically discovered from our BHL corpus. Learn more about the Mining Biodiversity Project, which runs through December 2015.

The Field Book Project: Improving Access to Researchers’ Fieldnotes

The Smithsonian Field Book Project has been hard at work discovering and making accessible field book materials through cataloging, digitization, and online publication. Thanks to dedicated staff and volunteers, the Project has made huge strides in that direction. To date, 90 fieldbooks digitized by The Field Book Project have been ingested into BHL.

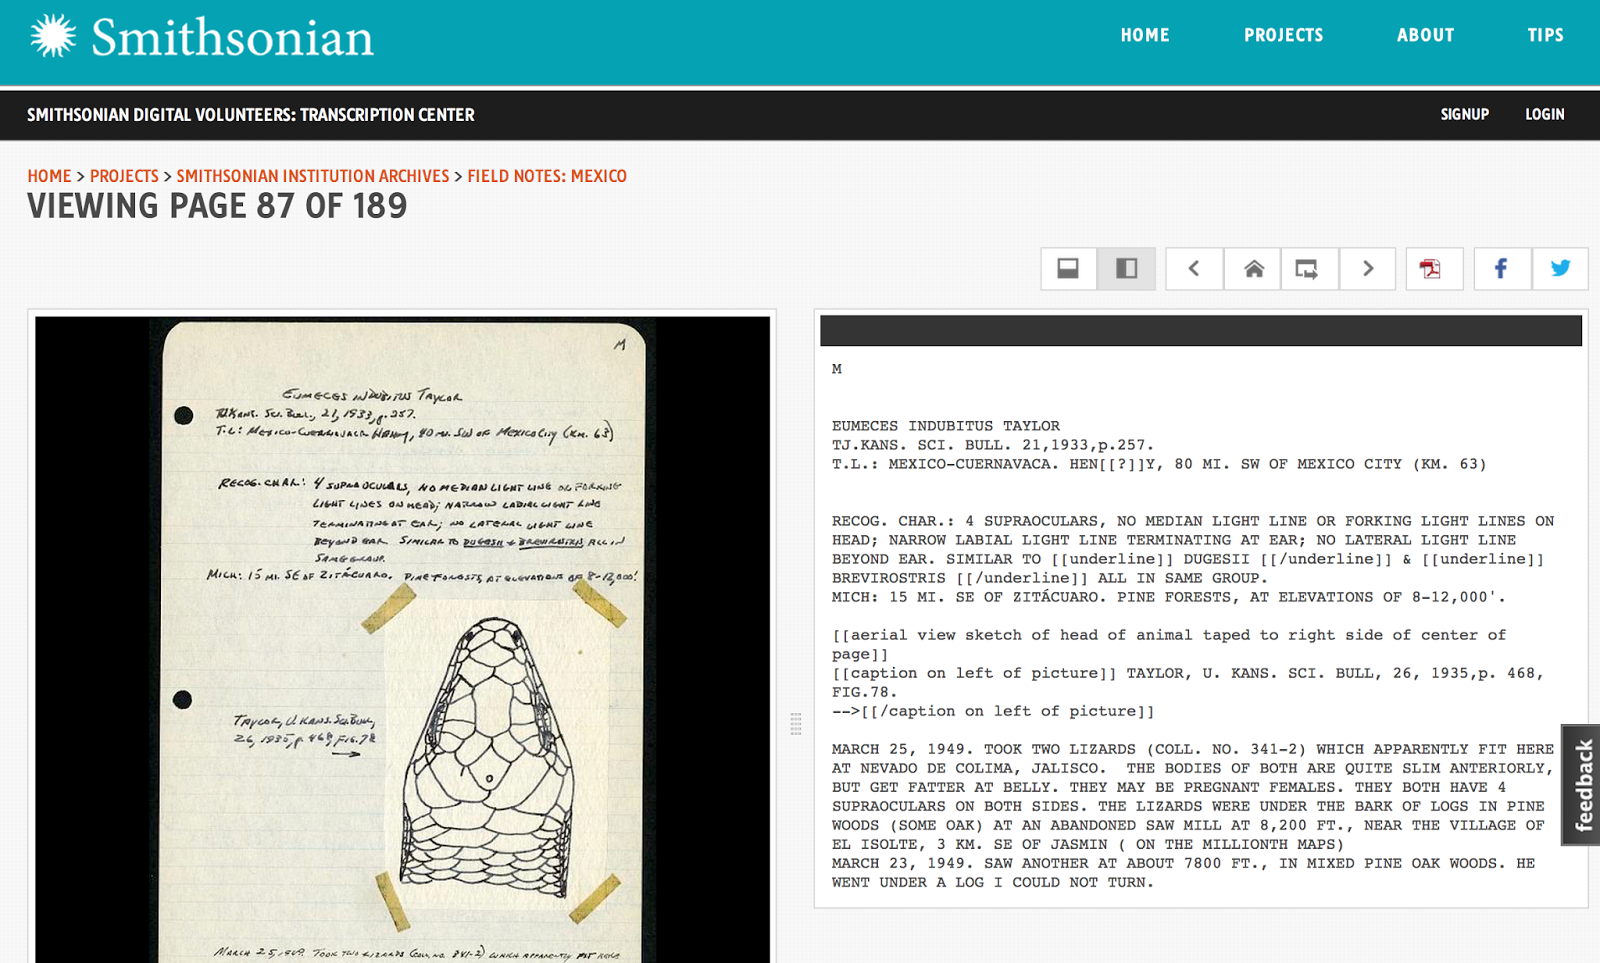
However, no celebration of success would be complete without a mention of the passionate “volunpeers” of the Smithsonian Transcription Center. Field books are often difficult to search and read due to their age and generally hand-written entries; pages may be faded and smudged, handwriting may be cramped or scribbled or stained by exposure to the elements, and the author may have used symbols and index marks that are foreign to modern readers. Unless a researcher knows exactly what they are looking for, they may be discouraged by the time and effort it takes to parse the archival text. Thankfully, the Smithsonian Transcription Center, which opened to the public on August 12th, has included the Field Book Project as one of its partners since the very beginning, allowing us to ask the crowd for assistance in conducting detailed readings and transcribing of field book content.

View Full Size Image
James Peter’s fieldnotes from Mexico (1949-50), transcribed for The Field Book Project in the Smithsonian Transcription Center.

Each item that goes into the Transcription Center must first be transcribed and then reviewed by a volunpeer, who must create an account and can then access both the training documents on the site and also the rich community on the Center and on related social media platforms for questions and answers. Several of the volunpeers have become “super users,” transcribing and reviewing a large volume of material, and also serving as rich information sources for new transcribers on how to document tricky situations such as foreign characters, symbols, marginalia, and in field books in particular, the scientific names for observed flora and fauna.

At last count there were 84 items in the Transcription Center, 69 of which had been fully transcribed, an incredible resource for researchers and reference archivists alike! More fieldbooks are being added continuously and the eventual goal is to place those completed transcriptions into BHL alongside the original field books. The crowd of volunpeers has and is enabling the Field Book Project to offer more and better access to everyone from professional researchers to curious onlookers, and sometimes even leads researchers to information that may never have been discovered without the dedicated assistance of the volunpeers on the Smithsonian Transcription Center.

Become a volunpeer today and help us transcribe field notes to improve access to these valuable primary-source documents!

We Love Our Users!

With over 44 million pages of biodiversity literature, several million images, and a desire to continuously improve access to and discovery of these materials, leveraging the power of the crowd is a match made in heaven for BHL. With contributions from our users, we can ensure that our wealth of biodiversity information can continue to inspire discovery of the natural world. Thank you for your contributions, and if you’d like to know more about how you can contribute, send us feedback.

Trish Rose-Sandler, BHL Data Analyst, Missouri Botanical Garden
Julia Blase, Project Manager, The Field Book Project
Grace Costantino, BHL Outreach and Communication Manager

View Full Size Image

The Art of Life project is funded by the National Endowment for the Humanities (Grant number PW-51041-12).

View Full Size Image

Mining Biodiversity is funded in part by the Institute of Museum and Library Services (Grant number LG-00-14-0032-14).

Purposeful Gaming is funded by the Institute of Museum and Library Services (Grant number LG-05-13-0352-13).

November 6, 2014by Grace Costantino
BHL News, Blog Reel

Game Laboratory Tiltfactor Selected for the Purposeful Gaming and BHL Project

BHL and the Missouri Botanical Garden are pleased to announce a major milestone reached in the project, “Purposeful Gaming and BHL”. Dartmouth College’s Tiltfactor was chosen to design the game that will help improve access to texts from the Biodiversity Heritage Library (BHL).

View Full Size Image

The Purposeful Gaming and BHL project is based at the Missouri Botanical Garden (MOBOT) in St Louis, Missouri. In the fall of 2013, MOBOT was awarded a $449,641 grant by the Institute of Museum and Library Services (IMLS) to test new means of using crowdsourcing and gaming to support the enhancement of texts from the BHL. Grant funding began in December 2013 and ends in December 2015. The Garden is partnering with Harvard University, Cornell University and the New York Botanical Garden on the project.

Principal Investigator for the project, Trish Rose-Sandler, reports that the project received “several strong bids for the design of the game so it wasn’t an easy decision. We are very excited to have found a great partner for this project because the game will be the critical component to improving access to digitized texts of the BHL.” The project’s goal is to demonstrate whether or not online games are a successful tool for analyzing and improving digital outputs. Users will be presented words that are difficult for software to recognize as tasks in a game.

View Full Size Image
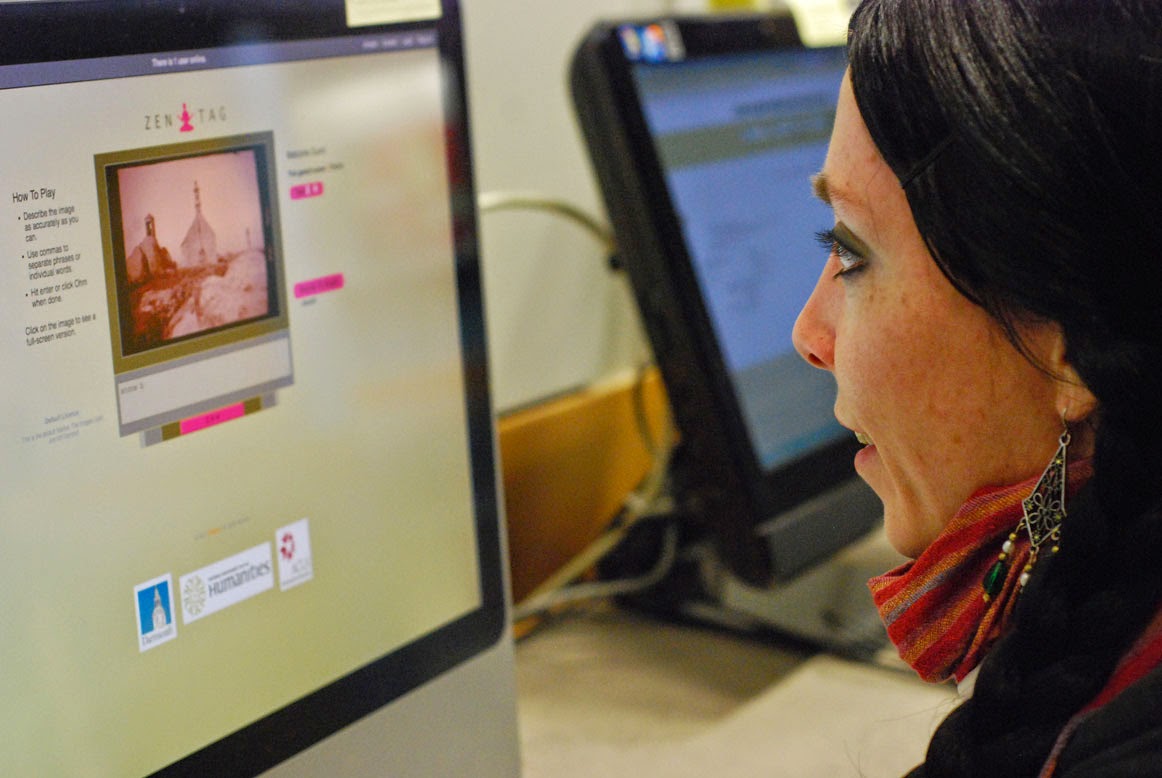
User engages with Zen Tag, one of Tiltfactor’s games available via the Metadata Games platform.

Tiltfactor had several strengths that made their bid stand out, including extensive experience designing games for the education sector. “We were also impressed that not only do they design games but they do extensive research into the impact of those designs on players from a psychological perspective – they even have two social psychologists on their design team,” states Rose-Sander. Tiltfactor’s greatest strength, however, is arguably their work with crowdsourcing metadata as demonstrated in their Metadata Games platform, which entices players to engage with and help improve access to archival content found in cultural heritage institutions.

The folks at Tiltfactor were interested in bidding on the project for several reasons. “The ‘Purposeful Gaming and BHL’ initiative extends our work with metadata games creation to bring in the public to meaningfully participate in our nation’s robust archives,” states Tiltfactor’s founding director, Dr. Mary Flanagan. “Games can be harnessed to provide fun experiences that also improve transcription and make bioheritage accessible to many more people. Tiltfactor is thrilled to work with BHL and their partners on an endeavor with such a high social return.”

The two teams will begin working collaboratively on the design of the game in July of 2014, and it is expected that the game will be released publicly sometime in early summer of 2015.

To learn more about project details see http://biodivlib.wikispaces.com/Purposeful+Gaming.

View Full Size Image

This project was made possible in part by the Institute of Museum and Library Services [LG-05-13-0352-13].

June 30, 2014by ulib-libraryjobs
BHL News, Blog Reel, Tech Updates

The 2012 BHL Staff & Technical Meeting

View Full Size Image
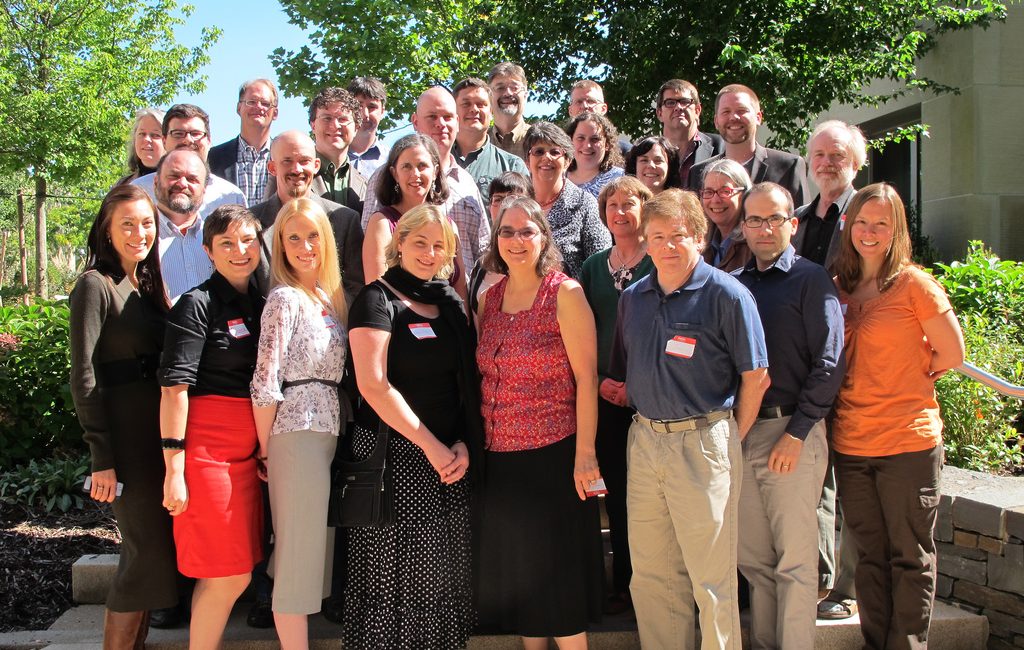
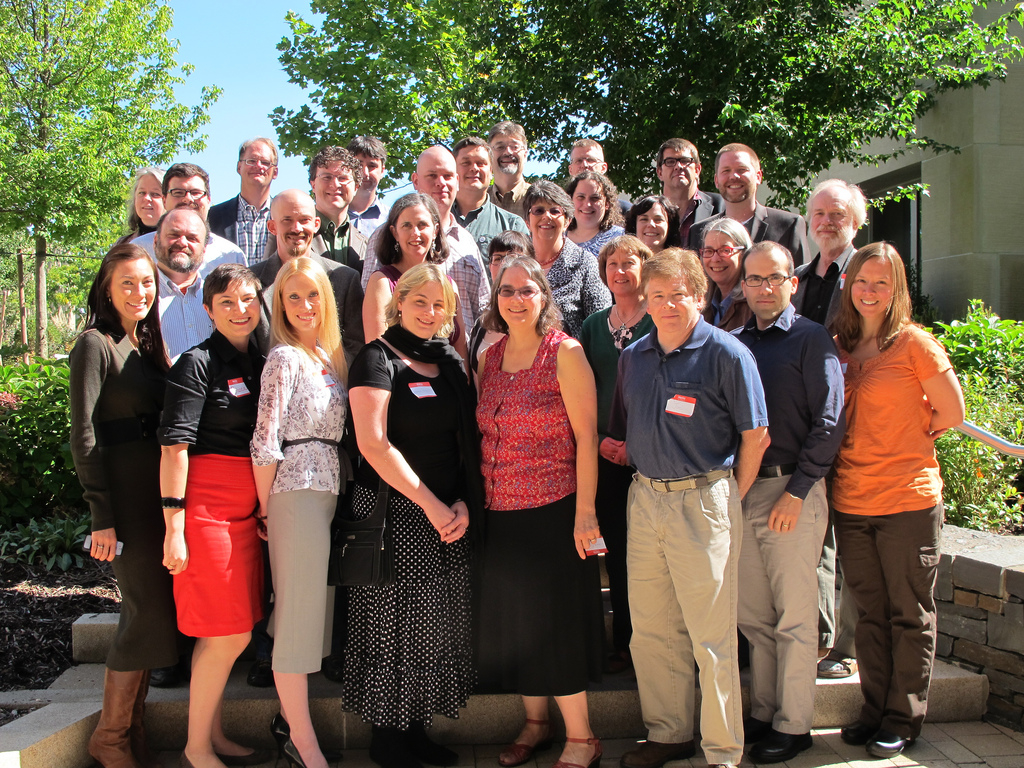
BHL Staff at the 2012 BHL Staff & Technical Meeting, Cambridge, MA, 27-28 September

On September 27-28, 2012, thirty-one staff members representing all 14 BHL member institutions convened at the Ernst Mayr Library at the Museum of Comparative Zoology at Harvard University for the 2012 BHL Staff and Technical Meeting. As a combined meeting, it brought together not only those that manage the digitization workflow at each member institution, but also those that work to keep BHL’s technical infrastructure running smoothly and constantly improving.

To maximize the 16 hours available for discussions, the meeting was divided into separate Staff and Technical tracks, with only those sessions relevant to all staff combined. Combined sessions included Program and Technical updates, as well as a discussion of BHL Projects and Initiatives, which was a chance for staff to identify high-impact projects to incorporate into a 2-year workplan for BHL. Staff sessions included a Program Management Update; brainstorming requirements for a BHL-Awareness Program; a Collections Analysis, Scope, and Prioritization discussion; a Blog brainstorming session; and discussions about BHL’s mission statement and goals. The Technical sessions discussed providing article-level access in BHL; replicating and synchronizing BHL content globally; the NEH Art of Life project status; BHL’s boutique digitization workflow management tool Macaw; Full-text searching; and OCR improvements.

This was also the first opportunity for BHL’s newest members, Cornell and the United States Geological Survey (USGS), to participate in one of our staff meetings. As a BHL-staff meeting virgin, we asked Jenna Nolt, librarian at the USGS, to share with us her thoughts about the meeting.

View Full Size Image
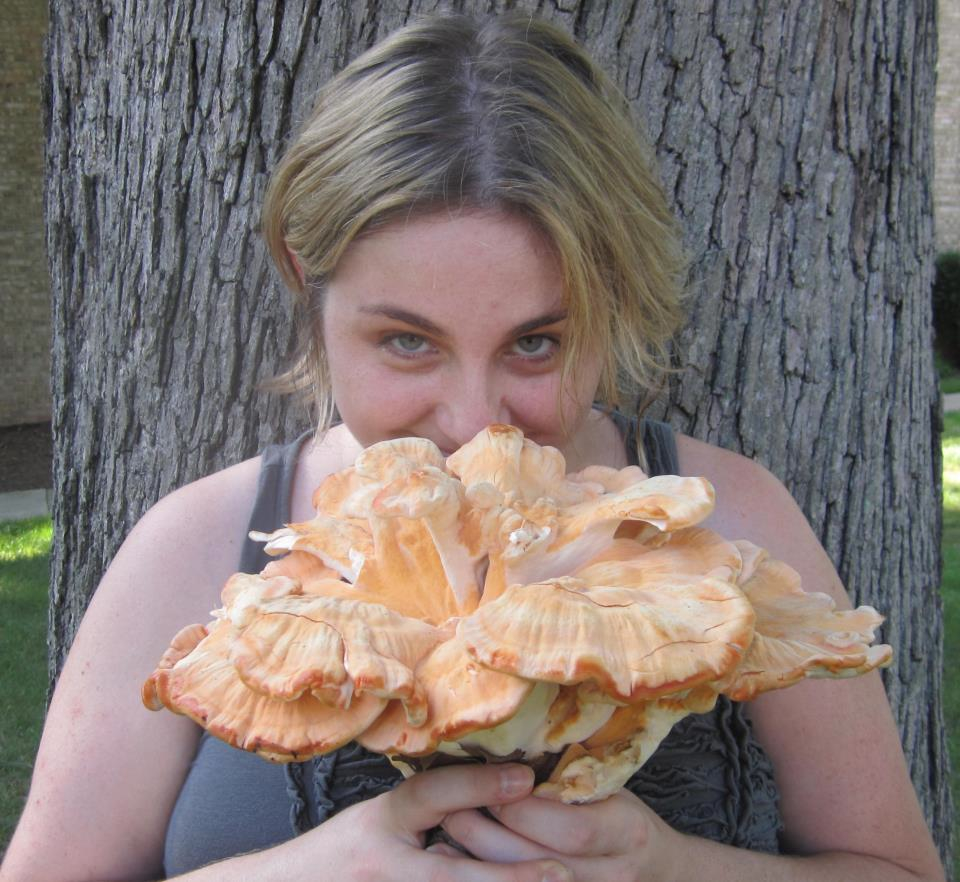
Jenna Nolt with a specimen of an edible polypore, genus Laetiporus, commonly known as chicken of the woods.

As a new librarian and new member of BHL, I was privileged to represent the U.S. Geological Survey Libraries at the staff meeting in September.  Our libraries have been contributing to BHL since March, and this was an exciting opportunity to meet, learn from, and collaborate with the other members.

From the moment I walked through the door I was impressed by the positive energy and enthusiasm of the whole group. After a general session we broke out into the staff track and the technical track; I stayed on the technical track.  As the sole librarian at my library dedicated to digitization, this was a valuable opportunity for me to discuss in detail some of the complexities of the digital world.  One thing I realized very quickly during these discussions is that all of us, in our individual libraries as well as in BHL, are addressing the same challenges of how to best organize, preserve, and expose complex objects in a constantly shifting digital landscape.

I was particularly interested in the discussion about OCR (optical character recognition) and excited by the plan for BHL to implement full-text searching, something that would be a huge benefit to our scientists and researchers. To accomplish this BHL will be using Solr which not only allows full-text searching, but also allows for faceted navigation, hit highlighting, and corrective spelling (“did you mean…”) features that any researcher knows the value of.

I was most actively involved with the section on Macaw, a piece of software created by Joel Richard at the Smithsonian used to upload digital objects packaged with metadata to Internet Archive. Our library has been testing and using Macaw for the past few months, and it has given us the ability to create a completely in-house digitization process for public domain materials. It was a great chance to speak with Joel directly and discuss with the group the possibility of setting up a cloud-based instance with multi-institutional access, which would be a huge advantage for many BHL members.

One theme emerged strongly for me over the course of the meeting.  I’ve become increasingly aware working in the information field that there are no simple answers in the digital world, no clear standards, and sometimes no answers at all. As anyone who has tried to do serious research online knows, this can be extremely frustrating.  But what I realized is that the BHL is at the cutting edge of constructing standards and creating answers where there are none to find.  When those skills are combined with the enthusiasm, passion for knowledge, and a love of science I saw at the meeting – well, that’s where the really cool stuff happens.

Thank you all and…I can’t believe I am saying this, but…can’t wait for the next meeting!

We are thrilled to welcome Jenna and our other new staff members to the BHL project. Nothing solidifies the initiation process more than participation in a two-day intensive staff and technical meeting!

The meeting may be over, but now the real work begins! We are busy developing plans to address our meeting action items and continue discussions about revising BHL’s mission and goals in order to further inform a 2 year workplan for the project. The 2012 Staff and Technical Meeting was a hands-down success and a fabulous opportunity for BHL’s dedicated staff to further our vision to repatriate biodiversity knowledge to the world.

October 9, 2012by Grace Costantino
Page 1 of 212»

Help Support BHL

BHL's existence depends on the financial support of its patrons. Help us keep this free resource alive!

search

About BHL

The Biodiversity Heritage Library (BHL) is the world’s largest open access digital library for biodiversity literature and archives. BHL operates as a worldwide consortium of natural history, botanical, research, and national libraries working together to digitize the natural history literature held in their collections and make it freely available for open access as part of a global “biodiversity community.”

Join Our Mailing List

Sign up to receive the latest news, content highlights, and promotions.

Subscribe Now

Subscribe to Blog via Email

Enter your email address to subscribe to this blog and receive notifications of new posts by email.

Join 319 other subscribers

Subscribe to Blog Via RSS

Subscribe to the blog RSS feed to stay up-to-date on all the latest BHL posts.

Access RSS Feed

Inspiring Discovery through Free Access to Biodiversity Knowledge.

The Biodiversity Heritage Library makes it easier than ever for you to access the information you need to study and explore life on Earth…for free, anytime, anywhere.


64+ Million Pages of
Biodiversity Literature Online.

EXPLORE

Tools and Services
to Transform Research.

EXPLORE

300,000+
Illustrations on Flickr.

EXPLORE

ABOUT | HARMFUL CONTENT | PRIVACY | SITE MAP | TERMS OF USE